International Research Journal of Engineering and Technology (IRJET)

Volume: 09 Issue: 04 | Apr 2022 www.irjet.net
e ISSN: 2395 0056
p ISSN: 2395 0072

International Research Journal of Engineering and Technology (IRJET)
Volume: 09 Issue: 04 | Apr 2022 www.irjet.net
e ISSN: 2395 0056
p ISSN: 2395 0072
Dr. Preeti Savant1, Lakshmi Sandhya H2
1 Assistant Professor, School of CS & IT, Jain University, Bangalore, India
2MCA Department, Jain University, Bangalore, India
***
Abstract The voice is most important and one of the natural forms of communication among from livelihood. The voice isa signal of countlessinformation. In this field we can collect infinite data and information in the voice signal.Therearemanyaspectsinthisfieldofresearchlike voice recognition, voice verification, voice synthesis, speaker recognition; speaker identification language recognitionetc.Voicerecognitionisadominanttoolofthe information interchange using the acoustic signal. Due to these reasons the voice signal is the leading subject of research from many decades. With the help of microphone, we can easily store or capture voice of any speaker. All captured words are later on recognized by voice recognizer, and in the end, system outputs the recognized words. Voice recognition is basically the science of talking with the computer, and having it correctlyrecognized.
Key Words: speech detection, speech recognition, audio to text processing, voice recognition, speech detection, speech recognition, audio to text processing
Speech recognition involves many fields of physiology, psychology, linguistics, computer science and signalprocessing,andisevenrelatedtotheperson’sbody language, and its goal is to achieve natural language communication between man and machine. The speech recognition technology is gradually becoming the key technology of the IT man machine interface. The paper describes the development of speech recognition technologyanditsbasicprinciples,methods,reviewedthe classification of speech recognition systems and voice recognition technology, analyzed the problems faced by thespeechrecognition.
Speech recognition is the machine on the command of human voice to identify and understand and react accordingly. The speech recognition technology allows the machine to turn the speech signal into the appropriate text through the process of identification and understanding. Speech recognition involves a wide range. It has a close relationship with acoustics, phonetics, linguistics, information theory, pattern recognition theory and neurobiology disciplines. With the development of computerhardware,softwareandinformationtechnology,
2022, IRJET
speechrecognitiontechnologyisgraduallybecomingakey technology in the computer information processing technology. Things to develop speech recognition technologyisalsowidelyusedinvoiceactivatedtelephone exchange information networks, medical services, bank services,industrialcontrolandpeople’slives[1].
Theobjectivesofthisprojectareasfollows:
Thisprojectiscompletelyascriptedlanguage.Weare usingmultiplelanguagestoproducetheoutput.
Theadvantageisthat,wecanhavethevoiceoverforthe translatedsentenceforbetterunderstanding.
The author provided the overview of the speech recognition pattern in [1] "Overview of the Speech Recognition Technology," which was published in 2012. Healsoexplainedhowspeechrecognitiontechnologyuses theHiddenMarkovModelandArtificialNeuralNetwork.
Forsberg, Markus, explained in [2] "Why is speech recognition tough" that voice recognition is one of thekeythingshappening, where wefindthe mosthelpful information. Every aspect has its own set of benefits and drawbacks. However, this study succinctly explains the difficulties and complications that arise when we target morethanoneusage.
Theauthorsof[3] "Astudyonvoicerecognition system: a literature review" by Gupta, Shikha, A. Pathak, and A. Saraf have attempted to describe speech recognitiontechniquesandmodellingmethodologies.This document also includes a list of strategies for feature extraction and feature matching, as well as their attributes. This review research discovered that MFCC is commonly utilised for feature extraction and that VQ outperformsDTW.
In [4] "Automatic voice recognition for under resourced languages: A survey," published in 2014 by Besacier, Laurent, et al., this work shows that speech processingforunder resourcedlanguagesisanactivefield of research that has made great progress over the last
Impact Factor value: 7.529 | ISO 9001:2008
of Engineering and Technology (IRJET)
Volume: 09 Issue: 04 | Apr 2022 www.irjet.net
decade. Although the technical developments outlined have accounted for most of recent progress. It is also evident thatthechanges will berequiredto resolvemany ofthepertinentissues.
In the year 2020, N. M. and A. S. Ponrajpublished[5] "Speech Recognition with Gender Identification and Speaker Diarization." The focus of the research is on speech analysis, with the MFCC and GMM beingutilisedtocreatemodelparameters.Duringtraining, the model had a 92 percent accuracy rate. Gender identification with speaker identification is trained using real time data from the dataset. The duration and overlappingofthespeakersintheaudiosamplesareused to determine speaker diarization. The audio processing performedwiththismodelcanbeusedtopredictgender basedclass.
This work was published by Zwass, Vladimir in theyear2016in[6] "voicerecognition."As weallknow, research is currently focused on inventing and constructingsystemsthatarefarmoreresilienttochanges in the acoustic environment, speaker characteristics, languagecharacteristics,externalnoisesources,andsoon. The author discovered that HMM is the most effective methodforcreatinglanguagemodels.
A. P. Singh, R. Nath, and S. Kumar published [7] "A Survey: Speech Recognition Approaches and Techniques" in 2018. The essential strategies and approaches for speech recognition are presented in this study.ThemanyoptionsavailableforconstructinganASR systemaredescribedindetail,togetherwiththeirbenefits and drawbacks. The performance of an ASR system is determined by two factors: first, the feature extraction techniques used, and second, the speech recognition approachusedforthespecificlanguage.
"A Review Article on Speaker Recognition with Feature Extraction" is found in [8]. Parvati J. Chaudhary and Kinjal M. Vagadia published the book in 2015. This survey study discusses speaker recognition classification, which can be utilised for a variety of speech processing applications, including security and authentication. The most popular feature extraction techniques are detailed here,withMFCCbeingthemostpopular.
In this paper, Speech Recognition is discussed. Speech Recognition is the procedure and the related innovation for changing over the discourse signal into its comparing groupingofwordsorothersemanticsubstances.
i.Automaticspeechrecognition
e ISSN: 2395 0056
p ISSN: 2395 0072
Automatic Speech Recognition is basically used to change over expressed words into computer content. Also, Automatic Speech Recognition is utilized for validating clients by means of their voice (biometric confirmation) and playing out an activity dependent on the directions characterized by the human. Generally, Automatic Speech Recognition requires preconfigure for voices of the essential clients. Human needs to prepare the Automatic SpeechRecognitionframeworkbyputtingawaydiscourse examplesofthemintotheframework[5].
Fig 1:AutomaticSpeechRecognition
ii.Speechtotextconversation
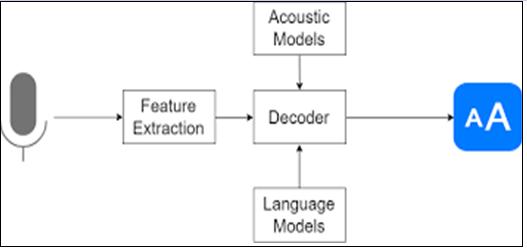
Speech is an uncommonly methodology for human computer collaboration: it is "without hands"; it requires just humble equipment for obtaining (top notch mouthpiece or amplifiers); and it shows up at an unassuming piece rate. Perceiving human speech, particularly persistent (associated) speech, without troublesome preparing (speaker autonomous), for a vocabulary adequate multifaceted nature (60,000 words) is exceptionally hard. Be that as it may, with present day forms, stream outline, calculations, while developing the framework speech recognition is being made using the decoder. In this framework, speech to text convertor is builtwithASR[5].
9001:2008
Fig 2:Speechtotext
ISSN:
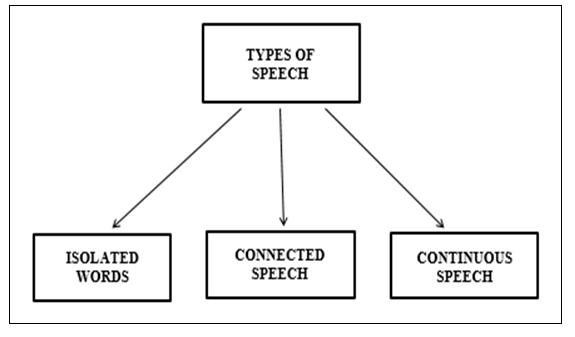
Speech can be generally classified into following categories:
i.Isolatedwords:
Isolatedwordacceptssinglewordatatime.Thesemethod have "Listen/Not Listen" states, where they require the speaker to wait between utterances. Isolated Utterance mightbethebetternameforthistype[3][7]
ii.Connectedwords:
Connected word speech recognition is the type where the words are separated by pauses. Connected word speech recognitionisatypeoffluentspeechstringswheretheset of strings is derived from small to moderate size vocabulary such as digit strings, spelled letter sequences, combination of alphanumeric. Like isolated word speech recognition, this set too has a property that the basic speech recognition unit is the word/phrase to much extent[3][7].
iii.Continuousspeech:
Continuous speech recognition deals with the speech where wordsareconnected togetherinsteadofseparated by pauses. As a result of information about words, co articulation, production of surrounding phonemes and rateofspeecheffecttheperformanceofcontinuousspeech recognition. Recognizer with continuous speech capabilities are some of the most difficult to create because they utilize special methods to determine utterance boundaries[2][7]. It allows user to speak naturally, where the computer will examine the content there are special methods used to determine utterance boundariesandvariousdifficultiesoccurredinit[3].
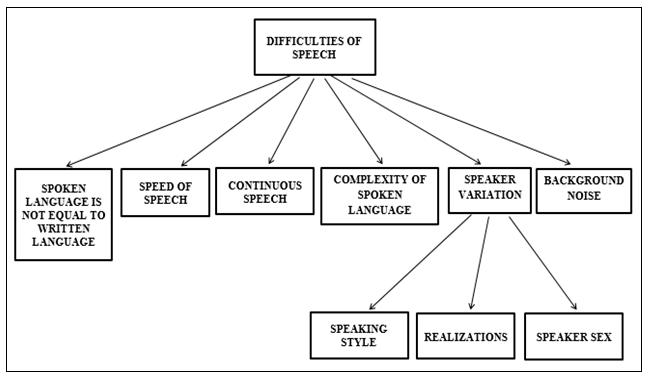
Following are the some of the difficulties/problems faced byspeechrecognition:
i.Spokenlanguageisnotequaltowrittenlanguage:
Spokenlanguageformanyyearsbeenviewedjustasaless complicated version of written language, with the main difference that spoken language is grammatically less complex and humans make more errors while speaking. Anyways, it has become clear in the last few years that spoken language is different from written language. In speech recognition system, we have to identify and note downthesedifferences.Inspokenlanguage,thereisoften a radical reduction of morphemes and words in pronunciation.Thefrequenciesofwords,collocationsand grammatical constructions are highly different between spokenandwrittenlanguage[2].
Speech has no natural pauses between the word boundaries,thepausesmainlyappearonasyntacticlevel, such as after a phrase or a sentence. It introduces a difficult problems for speech recognition how should wetranslateawaveformintoasequenceofwords?Aftera first stage of recognition of phones and phone categories, we have to group them into words. Even if we disregard word boundary ambiguity, this is still a difficult problem. The only way to simplify this process is to give clear pauses between the words. This works for short command like communication, but as the possible length ofutterancesincreases,clearpausesgetinefficient[2].
Wespeakindifferentspeed,atdifferenttimes.Forexample, if we are stressed, we tend to speak faster, and if we are tired, the speed tends to decrease. We also speak in different speeds if we talk about something known or unknown[2].
Volume: 09 Issue:
www.irjet.net
Technology (IRJET)
e ISSN: 2395 0056
ISSN: 2395 0072
In English, few words have different meanings which depends on the context for example, “red” and “read” soundsthesamebuthavedifferentmeanings[7].
Identifying the speech from the background noise is very difficult.Thisisspecificallytrueifthebackgroundnoiseis alsospeech(sayataparty)[7].
Human speak distinctively. The voices are not only differentbetweenspeakersbutalsowidevariationwithin one specific speaker. Some voice variations are given below
All speakers speak distinctively due to their unique personality. They have a different ways to pronounce words. The way of speaking differs in different situations. We don't speak the same way in public area, with our teachers or friends. Humans also express emotions while speakingi.ehappy,sad,fear,surpriseoranger[2].
If same words were pronounced again and again, the resultofspeechsignal won'tbesame.There will besmall differences in the acoustic wave produced. Speech realizationchangesovertime[2].
Male and Female have different tone. Female have short vocal tract than male. That's why, generally they say, the pitchoffemalevoiceisroughlytwicethanmale[2].
It is one of the significant part of speech recognition systems it detects and analyze the given sample data. It improves the speech signal to enable to get cataloging of sounds.The rawspeechdata obtainsa lotoffactsbesides the linguistics information. Sometime these facts are very bulk in quantity and variable in nature. It becomes very difficult to categories and analyze that raw data. The featureextractionveryimportanttoextractsilentfeatures with nominal variability from this raw data That is importantforclassificationofsounds,itgivesthedirection to verify the jest of information. Many feature extraction techniquesarepresentbutvoicegivesbetterresult[7].
Attheinitialstate,theuserinputstheaudiothroughmic. Then,thesystemrecognizestheaudioformat.
Ifthesystemdoesn’trecognizesoranyerror,it’lltakeyou tothefinalstate
After audio recognition, language specification is given to whichspecificlanguageitshouldbeconverted.
Converting and translating process happens using the languagespecificationandgivestheoutput.
Theconvertedtextwillbecalledtranscripthere.
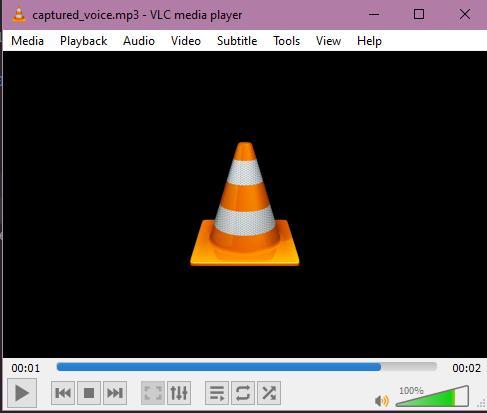
At the final state, the user can view the translated transcript and also have the feature to listen to the transcriptthroughtheplayer.
Speech Recognition is the procedure and the related innovation for changing over the discourse signal into its comparing grouping of words or other semantic substances.
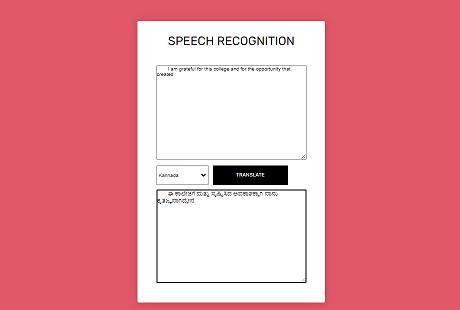
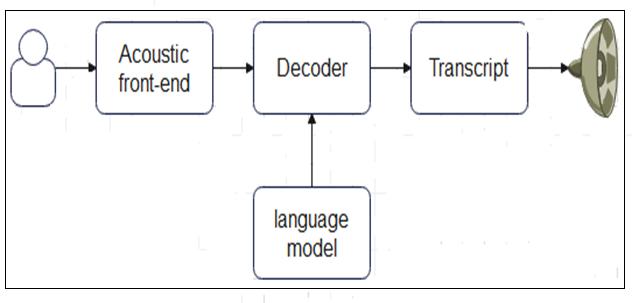
Asaresultofspeechrecognitioninthisproject,wecan abletosaythesentencewhichisneededtobetranslated tothespecifiedlanguageanddisplaytheconvertedtextas theoutput.Alsowecanlistentotheconvertedtextforthe properpronunciationinthatlanguagespecified.
Fig6:
From the problems faced by the speech recognition, speechrecognitionsystemsinordertobewidelyusedstill have a lot of areas for improvement. However, it is foreseeable in the near future that, with the voice recognition technology continues to progress, the speech recognition system will be more in depth, the application of speech recognition systems will be more extensive. A variety of speech recognition systems will appear in the market, people will adjust their speech patterns to adapt to a variety of recognition system Human beings in the short term is also impossible to create a people comparable to the speech recognition system, to build similar system is still a challenge towards humanity, we can only forward step by step direction to improve the speechrecognitionsystem[1].
[1] J. Meng, J. Zhang and H. Zhao, "Overview of the Speech Recognition Technology," 2012 Fourth International Conference on Computational and Information Sciences, 2012, pp. 199 202, doi: 10.1109/ICCIS.2012.202.M. M. Zoltán Balogh, “Motion Detection and Face Recognition using Raspberry Pi, as a Part of, the Internet of Things,” Acta Polytechnica Hungarica,vol.16,no.3,2019,pp.112 120.
[2] Forsberg, Markus. (2003). Why is speech recognitiondifficult.
[3] Gupta, Shikha, A. Pathak, and A. Saraf. "A study on speech recognition system: a literature review." International Journal of Science, Engineering andTechnologyResearch 3.8(2014):2192 2196.
(IRJET)
e ISSN: 2395
[4] Besacier, Laurent, et al. "Automatic speech recognition for under resourced languages: A survey." Speechcommunication 56(2014):85 100.
[5] N. M and A. S. Ponraj, "Speech Recognition with Gender Identification and Speaker Diarization," 2020 IEEE International Conference for Innovation in Technology (INOCON), 2020, pp. 1 4, doi: 10.1109/INOCON50539.2020.9298241.
[6] Zwass, Vladimir. "speech recognition". Encyclopedia Britannica, 10 Feb. 2016, [7] Arora, Shipra J., and Rishi Pal Singh. "Automatic speech recognition: a review." International Journal of ComputerApplications 60.9(2012).
[7]A.P.Singh,R.NathandS.Kumar,"ASurvey:Speech Recognition Approaches and Techniques," 2018 5th IEEE Uttar Pradesh Section International Conference on Electrical, Electronics and Computer Engineering (UPCON), 2018, pp. 1 4, doi: 10.1109/UPCON.2018.8596954.
[8] Chaudhary, Parvati J., and Kinjal M. Vagadia. "A Review Article on Speaker Recognition with Feature Extraction." International Journal of Emerging TechnologyandAdvancedEngineering 5, no. 2 (2015): 94 97.