ISSN: 2395 0056
ISSN: 2395 0072

ISSN: 2395 0056
ISSN: 2395 0072
1,2,3Student, Department of Information Technology, Shah & Anchor Kutchhi Engineering College, Mumbai, India
4 Professor, Department of Information Technology, Shah & Anchor Kutchhi Engineering College, Mumbai, India

***
Abstract Due to the advancements in the domain of Artificial Intelligence and Data Science, its utilization is becoming more common in every possible domain. Nowadays, the majority of the industries make use of AI and its applications in some or the other way. Taking the advantage of the field of Data Science results in creating effective and modern applications, products irrespective of the domain. One of the industries where theapplication of AI and Data Science is proving to be effective is the Finance Industry commonly known as the Banking Sector. Banks face severe losses due to the loan defaults made by the client and hence to overcome this problem, there lies a need to create a credit risk scoring model which can analyze and predict the loan defaults. Hence, with the help of Machine Learning, weaim to createa Loan Default Analysis model which could predict the loan defaults and integrate the model into a web application for theuser for easy usability.
Key Words: Loan Default, Machine Learning, data mining, prediction, web application.
Due to the Covid 19 Pandemic, there is a huge loss of capitalcausedtothebankingsector,financialinstitutions, smallscalefinancecompanies,etc.Nearlyayearandahalf, everythinghasbeenshutdowntherebyleavingpeoplewith no source of income. Due to this reason, there has been a significantincreaseintheloandefaultsmadebytheclient. Now,inthisnewnormal,thereisaneedespeciallyforthe banks to strengthen their loan sanctioning system. Since banksmayfacehugelossesduetothedefaultsmadebytheir clients which increases the rejection rate of the loan applicants.Thisaffectsthebank'soverallreputationandalso atthesametime,duetotherejectionofnewloanapplicants it causes huge financial loss to the bank since, the most common type of unsecured loans are debt consolidation, credit cardloans,studentloans,andpersonalloans[1].
The LoanAnalysisPredictingDefaulters(LAPD)isan attemptatcreatingabettercreditriskscoringmodelwhich cancorrectlyidentifywhichapplicantwillbeadefaulterin thefuture.Thisisdone by analyzingthehistoricdata and identifyingthepatterns.Suchamodelwouldminimizecredit riskandpreventtheclientswhoarecapableofrepayment
fromgettingrejected.Variousclassificationalgorithmssuch asLogistic Regression, Decision Tree, RandomForest, etc. have been applied to build various models and compare them to find out the best accuracy [4]. The source of the datasetisKagglewhichisahighlyimbalanceddataset.Data BalancingtechniquessuchasSMOTE,SMOTEENNhavebeen implementedtobalancethedataset.Importantfeaturessuch asloan_amount,term,home_ownership,issue_date_year,etc havebeenextractedonwhichthetargetattributedepends forprediction.Oncethemodelcreationandcomparisonare done, the model which gives better accuracy is integrated intothewebsitefortheend user
Banksmaysuffersignificantlossesasaresultofcustomer defaults,whichraisestherejectionrateofloanapplications. Toaddressthisissue,werequireamoreaccuratecreditrisk assessmentalgorithmthatcanpredictwhichapplicantswill defaultinthefuture.Thiswillbeaccomplishedbyanalyzing previous data and discovering trends. This methodology wouldreducecreditriskandpreventclientswhoarecapable ofrepaymentfrombeingturneddown[3].
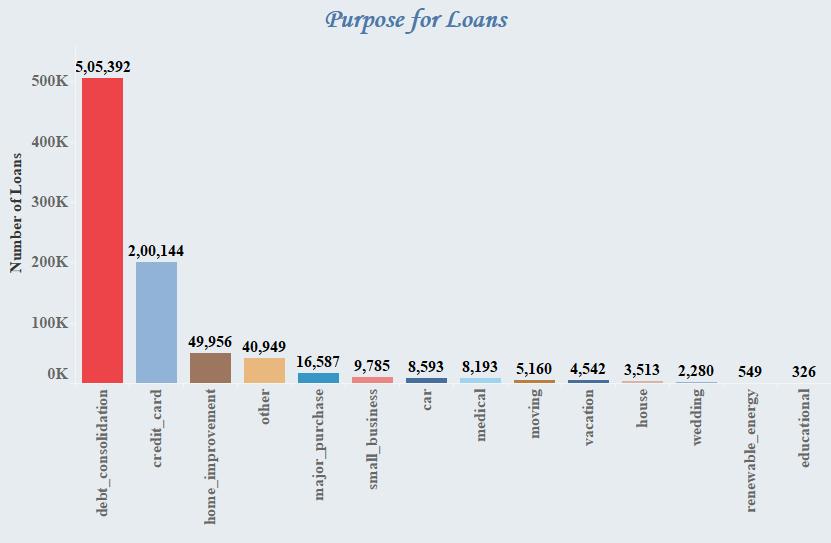
TheData SetwastakenfromKaggleThedatasetincludes entire loan data for all loans granted between 2007 and 2015,includingcurrentloanstatus(Current,Late,FullyPaid,
Research Journal of Engineering and Technology (IRJET)
Volume: 09 Issue: 04 | Apr 2022 www.irjet.net
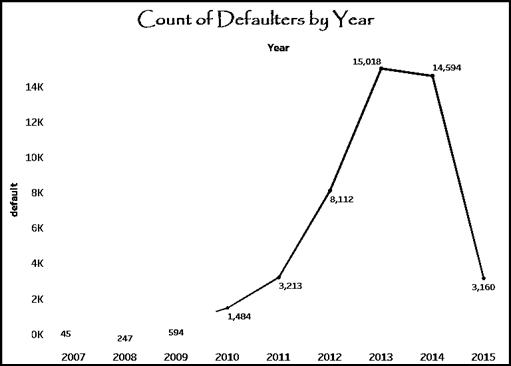
etc.) and most recent payment information. There are 8,55,969itemsinourdataset,with73attributesincluding the target variable. Furthermore, the dataset is extremely imbalanced,with46467entriesoffailedloans.Thisdataset containsavarietyofattributes,includingcategory,numeric, and date data. The number of defaulters increased significantly between 2012 and 2014, with the LIBOR Scandal,HurricaneSandy,andHostessFilesforBankruptcy beingsomeoftheprimaryfactors.Themajorreasonfora borrower's request for a loan is the loan purpose. Debt consolidation isthe mostcommon reasonfortakingout a loan,followedbycreditcarddebt.
•loan_amnt Amountofmoneyrequestedbytheborrower.
•int_rate Theinterestrateontheloan.
•grade LoangradewithcategoriesA,B,C,D,E,F,G.
•annual_inc Borrowersannualincome.
•purpose Theprimarypurposeofborrowing.
•installments Monthly amount payments for the opted loan.
•term durationoftheloanuntilit’spaidoff
•to theratioof your gross monthlyincomethat goesto payingyourmonthlydebtpayments[6].
'<1year' >0;
e ISSN: 2395 0056
p ISSN: 2395 0072
Thedatawereinspected,cleaned,andpreparedasfollows beforedata miningmodelanalysis:Changingthenamesof thevariables Wechangedthenamesofthevariablesto suitourneedsanddomainexpertise.Retrievedthevaluesof variablessuchasemplengthandterm,whichhadvaluesina stringfromwhichweextractedthenumericcomponent.
E.g.: '10+years' >10;
'2years' >2; '1year' >1;
2022,
Wedidthesamethingforthetermwithstringvalues.
Forexample: 36months >36 60months >60
Valuesfromonevariablearereplacedwithvaluesfrom anothervariable.Basedontheapplicationtype,theincome valueoftheborrowerisreplacedwiththeincomevalueof theco borrower.IftheapplicationtypeisINDIVIDUAL,the borrower'sincomewillbepreserved,butiftheapplication typeisJOINT,thecurrentvalueoftheborrower'sincomewill be substituted with jointincome. while jointincomeisthe sumoftheborrower'sandco income.borrower'sDti/ratio incexpborroweranddtijoint/ratioincexpjointfollowthe sametechnique.
TheLabel Encoderisa methodforconvertingcategory data to numeric variables. We used the Label encoder approachtocategorizetheaforementionedvariables,which arecategorical.Wehavetwofunctionsinthistechnique:fit andtransform.
1. Obtainingtheone of a kindvalues
2. Puttingtheminascendingorderisagoodidea.
3. Startingwith0,1,2,andsoon,mappingthevalues.
4. All three processes will be completed by the Fit function.
5. Thedatavaluesinthedataframewillbereplacedby thetransformfunction.
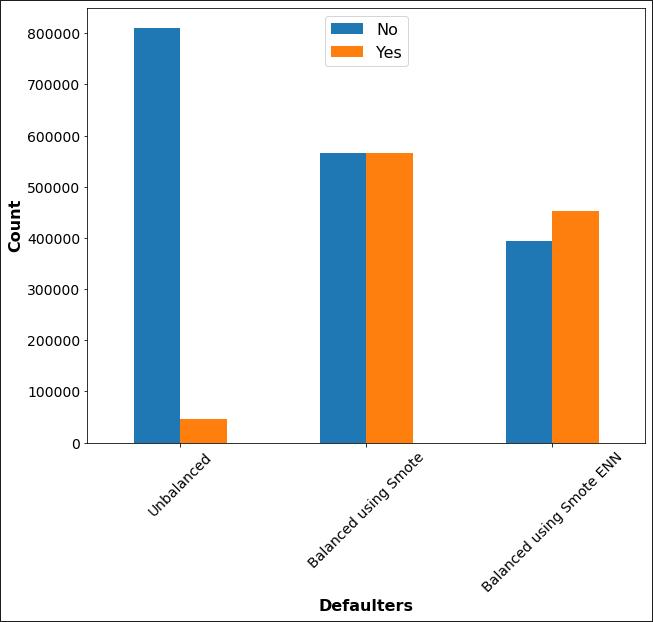
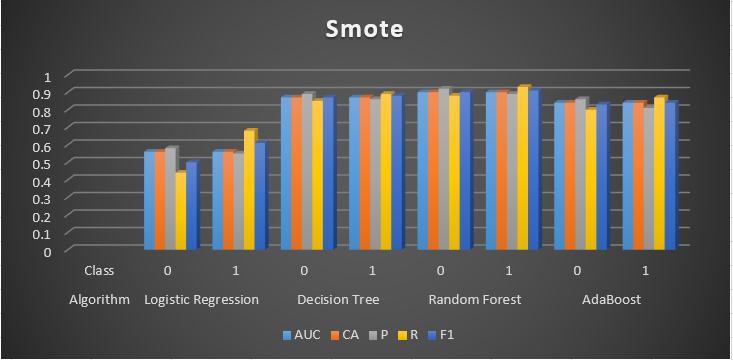
Splittingthedataintotrainandtestintheratio7:3wherethe training part contains 70 % of the data and Testing part contains30%ofthedataTrainSize 598978recordswith8 features Test Size 256991 records with 8 features. The Dataset was highly Imbalanced with variable 0 (Non Defaulters)=809502and1(Defaulters)=46467.Inorder, thebalancethisdayoutwehaveusedtwotechniqueswhich areSmoteandSmoteENN[3].
Imbalancedclassificationentailscreatingpredictionmodels for datasets with a significant class imbalance. When workingwithunbalanceddatasets,thedifficultyisthatmost machine learning approaches will overlook the minority class, resulting in poor performance, even though performance on the minority class is often the most
Factor value: 7.529 | ISO 9001:2008 Certified
Volume: 09 Issue:
| Apr 2022 www.irjet.net
significant. Oversampling the minority class is one way to dealwithunbalanceddatasets.Duplicatinginstancesinthe minorityclassistheeasiestway,buttheseexamplesdon't provideanynewinformationtothemodel[7].Instead,new instances may be created by synthesizing old ones. The SyntheticMinorityOversamplingTechnique,orSMOTEfor short, is a kind of data augmentation for the minority population. Imbalanced classification entails creating prediction models for datasets with a significant class imbalance. When working with unbalanced datasets, the difficulty is that most machine learning approaches will overlooktheminorityclass,resultinginpoorperformance, eventhoughperformanceontheminorityclassisoftenthe mostsignificant.Oversamplingtheminorityclassisoneway todeal withunbalanceddatasets.Duplicatinginstances in the minority class is the easiest way, but these examples don't provide any new information to the model. Instead, newinstancesmaybecreatedbysynthesizingoldones.The SyntheticMinorityOversamplingTechnique,orSMOTEfor short, is a kind of data augmentation for the minority population.
Thismethod,developedbyBatistaetal.(2004),combines the ability of SMOTE to generate synthetic examples for minority classes with the ability of ENN to delete some observationsfrombothclassesthatareidentifiedashaving differentclassesbetweentheobservation'sclassanditsK nearest neighbor majority class. The following is a descriptionoftheSMOTE ENNprocedure.
(SMOTE begins) Select data at random from the minority class. Calculate the distance between the randomly generateddataandthekclosestneighbors.Addtheresultto theminorityclassasasyntheticsamplebymultiplyingthe differencebyarandomvaluebetween0and1.Repeatsteps 2 3untiltherequiredminorityclassproportionisachieved. (SMOTEcomestoanend)(ENNbegins)CalculateKtobethe numberofclosestneighbors.IfKcan'tbedetermined,it'llbe 3. Find the observation's K nearest neighbor from the dataset'sotherobservations,thenreturnthemajorityclass fromtheK nearestneighbor.Iftheobservation'sclassand itsK nearestneighbor'smajorityclassarenotthesame,the observationanditsK nearestneighborareremovedfrom the dataset. Repeat steps 2 and 3 until each class has the requiredproportionofstudents.(TheENNcomestoaclose.) [3].
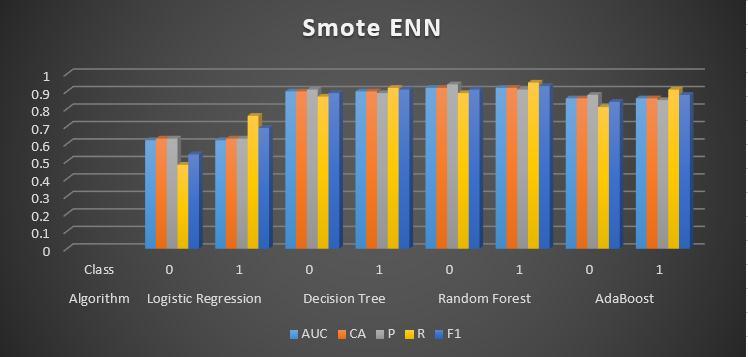
Afterusingthetechniquesthedatawasbalancedwithequal partsusingsmoteandintheratio6:4byusingsmoteENN.
e ISSN: 2395 0056
ISSN: 2395 0072
Themethodofmodelingthelikelihoodofadiscreteresult givenaninputvariableisknownaslogisticregression.The most frequent logistic regression models have a binary result,whichmightbetrueorfalse,yesorno,andsoforth. Multinomial logistic regression can be used to model situationswithmorethantwodiscreteoutcomes.Logistic regression is a handy analytical tool for determining if a freshsamplefitsbestintoacategoryinclassificationtasks. Because components of cyber security, such as threat detection, are classification issues, logistic regression is a valuableanalytictool[2].
Forclassificationandregression,DecisionTrees(DTs)area non parametricsupervisedlearningapproach.Theobjective is to learn basic decision rules from data attributes to developamodelthatpredictsthevalueofatargetvariable. Atreeisanapproximationofapiecewiseconstant.Decision Treesarea formofsupervisedmachinelearninginwhich thedataiscontinuallysplitaccordingtoaparameter(you describewhattheinputisandwhattherelatedoutputisin thetrainingdata).Twoentities,decisionnodes,andleaves can be used to explain the tree. The decisions or ultimate outcomes are represented by the leaves. And the data is separated at the decision nodes. At first, we consider the entiretrainingsettobetheroot.Categoricalfeaturevalues are desired. If the values are continuous, they must be discretized before the model can be built. Records are distributedrecursivelybasedonattributevalues.Astheroot oftheinternalnode,weapplystatisticalapproachestorank characteristics.
The AdaBoost algorithm, short for Adaptive Boosting, is a BoostingapproachusedinMachineLearningasanEnsemble Method.Theweightsarere allocatedtoeachinstance,with larger weights applied to improperly identified instances. This is termed Adaptive Boosting. In supervised learning, boostisusedtodecreasebiasandvariation.Itisbasedon thenotionofsuccessivelearning.Eachsucceedingstudent, exceptthefirst,isproducedfrompreviouslygrownlearners. Inotherwords,weakstudentsaretransformedintostrong students[6].Withalittlemodification,theAdaBoostmethod operatesonthesameideaasboosting.AdaptiveBoostingis aneffectiveensembleapproachforbothclassificationand regression issues. It is most commonly used to solve categorizationdifficulties.Itoutperformsallothermodelsin terms of model correctness, which can be verified by following the steps in order. To apply the boost and implementAdaBoost,onecanstartwithdecisiontreesand thenmoveontorandomforests.Asweprogressthroughthe steps outlined above, accuracy improves. The weight assigningapproachusedaftereachiterationdistinguishes theAdaBoostalgorithmfromallotherboostingalgorithms, whichisitsstrongestfeature.
Randomforestisasupervisedmachinelearningalgorithm thatiscommonlyusedtosolveclassificationandregression issues.Itcreatesdecisiontreesfromseveralsamples,using the majority vote for classification and the average for regression.Oneofthemostessential characteristicsofthe RandomForestAlgorithmisthatitcanhandledatasetswith bothcontinuousandcategoricalvariables,asinregression andclassification.Forclassificationdifficulties,itproduces superiorresults.RandomForestAlgorithmCharacteristics
1) It outperforms the decision tree algorithm in terms of accuracy.
2) Itisausefultoolfordealingwithmissingdata.
3) Withouthyper parameteradjustment,itcanprovideafair forecast.
4) Itovercomestheproblemofdecisiontreeoverfitting.
5) Atthenode'ssplittingpointineveryrandomforesttree,a subsetofcharacteristicsischosenatrandom.
Forserializingandde serializingaPythonobjectstructure, thePythonpicklepackageisutilized.Picklinganobject in Pythonallowsittobestoredonadisc[3].Pickleworksby first"serializing"theitembeforewritingittofile.Picklingis aPythonfunctionthatconvertsalist,dict,orotherPython objectintoacharacterstream.Theassumptionisthatthis characterstreamprovidesallofthedatarequiredtorecreate theobjectinanotherPythonfunction.
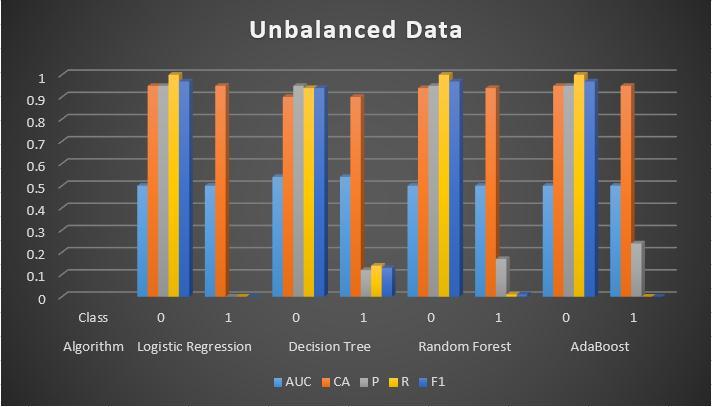
Fig.4.2ComparisonofAccuracyofUnbalancedData Fig.4.3ComparisonofAccuracyofBalancedDatausing Smote Fig.4.4ComparisonofAccuracyofBalancedDatausing SmoteENNVolume: 09 Issue:
2022 www.irjet.net
and Technology (IRJET)
e ISSN: 2395 0056
ISSN: 2395 0072
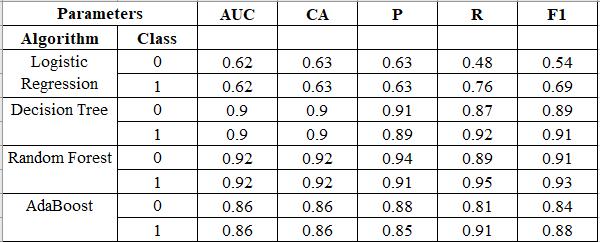
Afterapplyingthesealgorithms,wewereableanachievean accuracyof92%whichwasgivenbyRandomForestusing SmoteENNmethodafterwhichweusedthepicklelibraryto storethemodelandflasktointegrateitwithourwebpage.
Forourfront endpart,wehaveusedaPythonframework called Flask which is used to make a webpage. For our project,weintegratedourMLmodelintoawebsitewhichis usedtogetrichoutputandvisualization.
5.1 Flask:
Flask is a Python based web application framework. The WerkzeugWSGItoolkitandtheJinja2templateengineare thefoundationsofFlask.BotharePoccoinitiatives.
Andforthedatabasepart,wehaveusedMySQLandalsowe usedthesessiontoauthenticateourloginsystemwithbank users.
MySQL is a quick, easy to use relational database managementsystem(RDBMS)thatisutilizedbymanysmall and large enterprises. MySQL AB, a Swedish business, is responsibleforitsdevelopment,marketing,andsupport.
For our ML learning model, we used the Pickle python libraryforintegrationwiththeflaskwebpagealsoweshow thegraphsgeneratedfromtheMLmodelintoourwebpage forEasytounderstandourusers.
Normally Flask is used HTML templates to render the webpageandforCSSwehaveusedbootstrapandtailwind CSSforvalidationJSfunction.Also,inthefooter,wemention ourcontributors’details.Total4webpagesarethereonour websitewhichisHome,Login,Register,andPredict.
Screens on our website:
Home Page:
Onthispage,wemakeabasicwebpagewhichisconsistof Navbar,Body,andFooter.
Factor value:
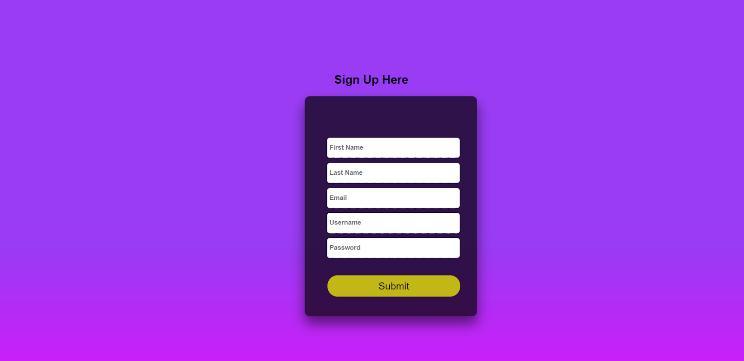
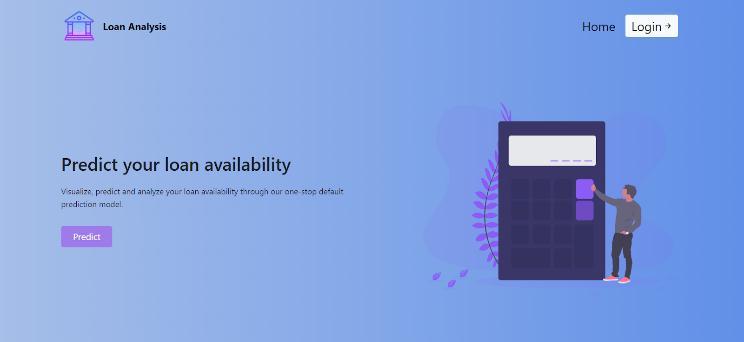
Fig.5.1HomePage
On this page for successful login, users have to give their perfectcredentialsaspertheregistration.Aftersuccessful loginbankuserscanusepredictcalculatororMLmodelfor theirclient/customers.
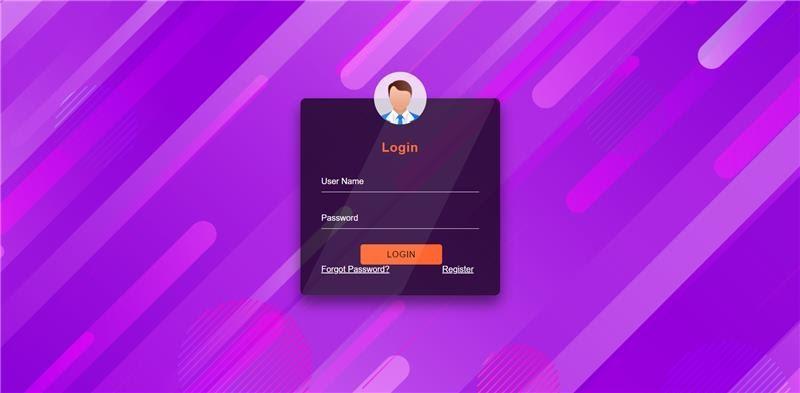
Fig.5.2LoginPage
Onthispage,weaskforBasicdetailsofusersforregistration withthedatabase.
Fig.5.3RegistrationPage
Onthispagewemadeonepredictingcalculatorfieldforour MLmodel.
AfterfillingallinputfieldswegivetheoutputaspertheML modelresultsandAccuracy.
9001:2008
(IRJET)
e ISSN: 2395 0056
ISSN: 2395 0072
[1] AhmadAl qerem,GhaziAl Naymat,MaysAlhasan,“Loan Default Prediction Model Improvement through ComprehensivePreprocessingandFeaturesSelection”, published.
[2] P. Maheswari, CH. V. Narayana, “Predictions of Loan Defaulter ADataSciencePerspective”,published.
[3] LinZhua,DafengQiua,DajiErgua,CaiYinga,KuiyiLiub, “Astudyonpredictingloandefaultbasedontherandom forestalgorithm”,published.
Sincethedomainoftheproject(LAPD)revolvesarounddata scienceandmachinelearning,itispossibletoaddNatural Language Processing (NLP) based chat bot which would maketheprojectmoreinteractiveandwouldhelptheuser innavigatingthewebsiteorwould recommendorresolve queriesregardingtheusageoftheapplication.Thechat bot can be integrated either by using python language or by using the Dialogflow platform powered by Google. In our project(LAPD)wehavedevelopedafull fledgedwebsitefor theend usertopredicttheloandefault.Analternativetothe website can be a mobile application which would prove much handier for the user. Cross Platform technology frameworkssuchasFlutterwhichisalsobackedbyGoogle can be brought into consideration for developing the application[4].Apartfromthis,currently,thedatasetwhich wehaveusedisrestrictedtoaparticularorganization.Ifitis possibletocollectawiderrangeofdata,itwouldnotonlyact asaknowledgebaseforthemodelbutalsohelpthemodelin understanding and predicting the loan default correctly indirectlyresultingingettingbetteraccuracy
DuetoasuddenhaltcausedbytheCOVID 19pandemic,it has affected almost every possible business of industries thusleadingtoafinancialdip.Manyfinancialandbanking firmsbothlargescaleandsmallscalearetheprimesectors where the pandemic has largely impacted. The loan defaultersraterosehighbecauseofthelockdownandnot manywereabletopayback.Hence,thisinvokedtheneedof developingasystemforpredictingtheloandefaultsthereby strengtheningtheloansanctioningprocess.
ThisLAPDisthusanattempttodesignanddevelop acreditriskscoringmodelwhichcouldanalyzeandpredict the possibility of the loan default and thus reduce the rejection rate of the new loan applicants and capital loss faced by the bank which they would have made by sanctioningtheloantotheclients
[4] HafizIlyasTariqAziz,AsimSohail,UzairAslam,“Loan DefaultPredictionModelUsingSample,Explore,Modify, Model,andAssess(SEMMA)”,published.
[5] Mehul Madaan, Aniket Kumar, Chirag Keshri, Rachna JainandPreetiNagrath,“Loandefaultpredictionusing decisiontreesandrandomforest:Acomparativestudy”, published.
[6] HarishPuvvada,VamsiMohanRamineedi,“LoanDefault Prediction”,published.
[7] Haotian Chen, Ziyuan Chen, Tianyu Xiang, Yang Zhou, “DataMiningonLoanDefaultPrediction”,published.
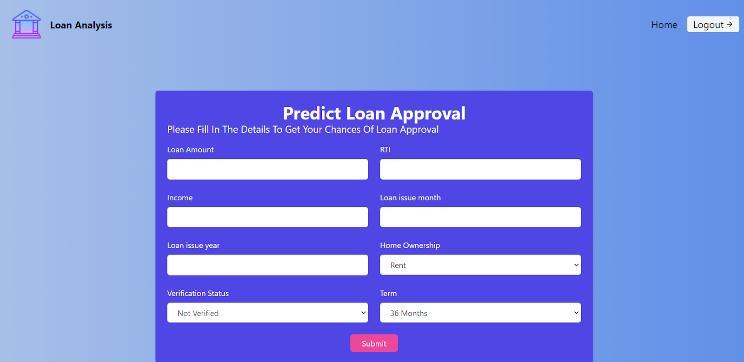 Fig.
Predict