
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Nandgowli Akhil, Palle Avidesh, Sundale Jhansi, Mussam Rajesh Reddy, Nalla Chaitanya
Department of Computer Science Joginpally B.R Engineering College
Department of Computer Science Joginpally B.R Engineering College
Department of Computer Science Joginpally B.R Engineering College
Department of Computer Science Joginpally B.R Engineering College
Department of Computer science Joginpally B.R Engineering College
Abstract - The most significant thing that can be done with kids who have end-stage heart failure is heart surgery, though there remains a huge issue of death one year after the transplant. This is a highly significant calculation of this mortality risk to be precise so that the donors and recipients can be better matched and patient outcomes enhanced. In this piece of work, we apply the ICU heart transplant expiration dataset to the determination of the risk of death of pediatric heart transplant patients after one year. We propose an innovative approach that involves methods of advanced feature selection and group to generate more precise predictions. The method includes using Chi-squared tests to select the most important traits and use more than one classifier to make the correct predictions. The results show that the suggested Voting Classifier, which uses both Boosted Decision Tree and ExtraTree models, works very well, as it gets 100% of the votes right. This is a fast and precise technique of estimating the probability of mortality within one year. It provides physicians with valuable data to enhance patient treatment and the most appropriate fit between the donor and recipient during pediatric heart transplants.
Key Words - Machinelearningalgorithms,deeplearning, classification,sleepdisorder,Votingalgorithm”.
Heart transplantation (HTx) has become a procedure that can help to save the lives of children with serious heart failure. Although they constitute approximately 10%ofthetotal numberofhearttransplantsperformed annually, there has been a gradual increase over recent decades in the number of cases of pediatric HTx. Over 450ofthesesurgerieswillbeperformedinUnitedStates alone in the year 2020. This has increased with the advancement in medical technology and surgical procedures.However,therearestillproblems,especially when it comes to lowering the death rate one year after transplantation, which is still very high [7]. Even more difficult, there are not many good organs that can be donated to support pediatric HTx. This adds to the serious problem of people dying while they are on the
waiting list. Many pediatric heart donors get discarded as it is difficult to determine whether the organs are qualityandwhethertherecipientswillmatch[7].Thatis anindicationofthenecessitytoimprovethestrategiesof donationutilization.
To achieve improved outcomes in pediatric HTx, individualshavebeenseekingtounderstandwhatmakes a transplant successful and develop instruments of data visualization to aid physicians to arrive at a decision. Despiteall theseefforts,the processofmatchingdonors and recipients remains highly subjective and relies on numerous various factors on both sides including medical, physiological and demographic factors [4, 10]. Therefore, to enhance the systems of organ allocation andaiddoctorstomakeimproveddecisions,itisneeded to create reliable prediction models to look at what happensafteratransplant[19].
The models of prediction have been of great assistance when making a decision regarding heart transplants. A stepthatiscommonlyappliedintheallocationprocessis the HTSS, created by the UNOS in the US. The HTSS considers factors such as the age of the individual, the illness, the degree of functionality and any other health issuesthattheindividualmighthavesuchasdiabetesor kidney disease. It further examines other aspects of the donorsuchastheirage,causeofdeathandcompatibility oftheir bloodtypewiththerecipient.Thisscoreassigns anumericalvaluetotheprobabilityofsurvivalfollowing transplantandassistsdonationcenterstodeterminethe typeofpatientsonwaitingliststhatitshouldassistfirst [13].
Another tool that is established by the Eurotransplant International Foundation is the Eurotransplant Donor Risk Index(ET-DRI),which examines boththefactorsof the donor and the person receiving the transplant to help them make a choice on whether they should have one. Predictive analytics have been demonstrated to be significant in heart surgery, based on models such as HTSS and ET-DRI. These models aren't perfect, though, because they might not take into account all the factors
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
that affect how well a transplant works. To enhance the survival rate of recipients, better utilization of organs, and addressing the issues that continue to emerge in pediatric heart transplantation [2], estimates using currentdata-drivendevicesmustbemoreprecise. Machine learning can help us make the right judgement about the merits of the donors in kidney heart transplants. This simplifies a lot the prediction of the outcomeofthetransplant.Thisapproachisasolutionto the issue that arises in organ donation as it makes the process more effective and increases the number of patientswhosurvive[20].
Heart transplantation has emerged as a life-saving procedure to children with end-stage heart failure, yet there are still issues such as allocation of organs and post-transplant death. These issues have attracted the attentionofMLmethodssincetheycanassistadoctorto makedecisions and achieve better outcomes by offering predictivemodels.
Ashfaq et al. [1] used ML to look at the UNOS database and predict the death rate one year after a pediatric heart donation. They found that ML models could potentially be more effective at outcome prediction comparedtoconventionalstatisticalapproachesbecause of the fact that they consider a large number of donor and recipient variables. Miller et al. [15] also employed ML techniques including the use of RFs and Neural Networks to enhance prediction of death in pediatric heart transplantation. They demonstrated that ML systems were capable of making more accurate predictions compared to conventional scoring systems. This implies that we ought to abandon the traditional modelstousedata-drivenmodelstoassistdoctorsmake decisions.
Killian et al. [12] examined the national registry data to speculate the outcome of kids who received heart transplants.Theiranalysisdemonstratedthesignificance ofpreprocessingdata,selectingtheappropriatefeatures, and tuning the model to achieve the correct predictions by comparing the methods of ML. The paper also indicatedthatMLmodelsarecapableofadjustingtonew data at a fast rate thus suitable to alter clinical circumstances. Gotlieb et al. [9] expanded on this conceptanddiscussedthepotentialofhavingMLinsolid organ transplants, including heart transplantation. They examinedthewaysmachinelearningmodelscanbeused to assist in patient selection, organ matching, and postoperative care. They identified certain mechanisms through which ML can reduce the variability in clinical decision-makingandenhanceoutcomes. Chebli et al. [6] investigated the application of semisupervised learning to medicine, and how this can be
applied to heart transplants. Their solution addressed theissueofunlabeleddatascarcityinhealthcarethrough semi-supervised learning methods that provide a good teacher to prediction models. It is particularly effective whendoingkidhearttransplantsasaccesstothedatais difficult. The more the models are able to discover meaningful patterns in both labeled and unlabeled data, the higher the chances that they will be consistent and applicableintherealworld.
Miller et al. [16] looked into how the accuracy of ML models in predicting heart transplant results changes over time. They claimed that overtime, ML models become incapable of forecasting the future due to the changing clinical practices, patient populations and organsupply.Theirresearchimpliedthatmodelshaveto be continuously re-trained with new information to ensure that the performance remains high. This finding is highly significant to the heart transplants that are performed in the pediatrics, as the rapid advancements in healthcare systems and alteration in the mode of giving out the organs would render the older ones useless.
A single method to interpret statements made by ML models is SHAP (SHapley Additive Explanations), developed by Lundberg and Lee [14]. This approach is particularly effective in medical contexts, such as pediatric heart transplants, where it is useful to doctors to understand how various characteristics can influence the outcomes so that they can make good decisions. SHAPassistsphysiciansincomprehendingthemannerin whichMLpredictionswereproducedbyprovidingthem witheasytointerpretandconsistentfeatureimportance values.Thisdevelopstrustandopenness.Themethodis widelyusedinareaswhereinterpretabilityisimportant. Itgetsridofoneofthemainproblemsthatmakesithard to use complex ML models successfully in clinical practice.
Naruka et al. [17] did a systematic study that showed how ML and AI can be used in heart transplants. They conductedastudyexaminingthevariousMLtechniques, such as supervised learning and unsupervised learning, and their usefulness in predicting the outcome of transplants, finding the optimal match between the donor and recipient, and determining the quality of organs.TheauthorsemphasizedthatMLcancorrectthe issues of existing allocation techniques and improve in the long-run. Nevertheless, they also identified such issues as the standardization of data and ethical issues. In order to reap the full benefits of ML in the area of cardiac transplantation, they urged physicians and data scientiststocollaborate.
Yang et al. [18] conducted an extensive review of deep semi-supervisedlearning,andtheauthorsareinterested incomprehendinghowitcouldbeappliedinthecaseof
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
limited amounts of labeled data, such as infant heart transplantation. They discussed new techniques, including generative models and consistency regularization, which can improve the training on both labeled and unlabeled data. This is particularly effective inthemedicalenvironmentwheretaggeddataisdifficult tolocate and expensiveto access.Deep semi-supervised learning has the potential to enhance performance and generalization of a model by using unlabeled data well. Thisrendersitapromisingapproachtowardsenhancing MLapplicationsinhealthcare.
Our methodis more sophisticatedand consists ofa new combination of ML and feature selection to predict whether a child will die one year after heart transplantation or not. The ICU heart transplant expiration dataset will be used by the system to find important factors that raise the risk of death after donation. Chi-squared (Chi2) method will be used to weed out irrelevant traits and ensure the model concentratesonthemostsignificantpredictors.Thiswill enhance our predictions. To make predictions, we will then apply some ML techniques, including KNN [11], LR [8], and RF [3]. We shall also consider ensemble techniques particularly the Voting Classifier, which combines the strengths of the Boosted Decision Trees and ExtraTree in order to make the system perform better through the combination of their strengths. A big part of the suggested system will be using semisupervisedlearningmethods.Thefalsificationofcasesin these techniques consists of pairing donors and recipientsinamannerthatresemblesrealcasesgreatly. Thiswillallowthesystemtoutilizethedatathathasnot been labeled and thus will be more accurate in making correct guesses. The proposed approach will enhance clinicaloutcomesandensureeasierfindingofeachother bythedonorsandrecipients.
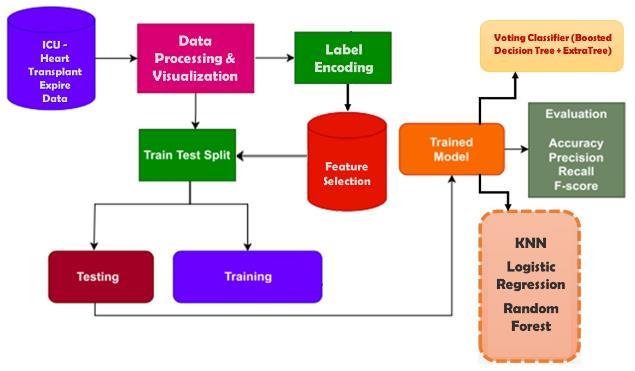
Intheimage(Fig.1),thereisaMLapproachtopredicting thataheartdonationwillnotbeeffectiveanymore.This beginswithICUdata,which isprocessedandpresented. The data is subsequently split into training and testing
set.Featuresarefirstselected,thenencoded.Thedatais sent to different models, such as RF [3], KNN [11], and Logistic Regression [11]. Their guesses are put together by a vote classifier. Metrics like F1-score, accuracy, precision,andrecallareusedtojudgethemodel.
The data used in this research is the [5] ICU - Heart Transplant end data, which contains varying clinical information of individuals that underwent heart transplants.Itincludessuchinformationastheageofthe patient on admission, vital signs (heart rate, blood pressure, breathing rate), laboratory findings (glucose, lactateandpotassiumlevels),anddataaboutthepatient him/herself,suchasBMI,gender,andintubationornonintubation. The goal variable is hospital_expire_flag, which displays the survivability/death of the patient. This dataset has many traits that can be used to model and predict the risk of death one year after transplantation, which is important for finding the best matchbetweendonorandrecipient.
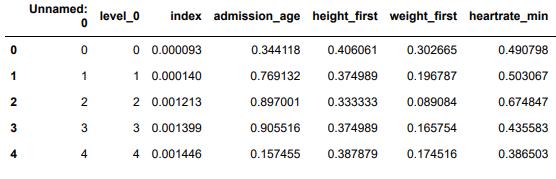
Fig-2: DatasetCollectionTable
In the pre-processing stage, we focus on preparing the dataset to model. This includes data cleaning, visualization of meaningful relationships, coding nominal values, and use of feature selection to ensure themodelhasthebestinput.
a) Data Processing: The purification of the dataset, which includes the removal of extraneous columns and the null values, is the first part of the data processing stage, which guarantees the data consistency and readiness to be analyzed. Any missing values are removed to prevent distortions in the model. This step ensuresthatthedatasetisstructuredinsucha waythat it is further manageable with minimal likelihood of errors in the modeling process and a higher quality of dataingeneral.
b) Data Visualization: To understand how the data is related to each other, you need to be able to see it. A correlation table has strong and weak links between features and this provides you with an impression of whatvariablescanpredictthegoalvariable.Resultsofa sample are also plotted in a manner that allows
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
comparison of data trends. This makes it easier to see important patterns or outliers. This is a very important step to be able to tell how the dataset is structured and howitisinterrelated.
c) Label Encoding: It is called label encoding and is a method of storing categorical data using numbers, and this makes it ideal in machine learning techniques. This stepassignsuniquenumberstoeachgroup,enablingthe data to be viewed using models. It makes sure that categorical factors are shown in a way that doesn't damage the dataset, which makes training and testing models better. The label encoding is particularly applicableinnon-numberdatainclassificationtasks.
d) Feature Selection: ThismethodusestheChi2filterto pickoutthemostimportanttraitsthatwillbeusedinthe predictive model. This method figures out how each attributeisrelatedtothegoalvariableandthengetsrid of the ones that aren't important. By concentrating on the most significant features, the model will perform better, become easier, and reduce the chances of overfitting. This measure will ensure that the model is influencedbythemostsignificantfactorsonlywhichwill makeitmoreaccurateanduseful.
Two-fifthsofthedataistrainingandtheothertwo-fifths aretesting.Trainingthemodelconsumeseightypercent of the data and assists it when discovering the fundamental patterns and correlation of the characteristics with the objective variable. One can observe the effectiveness of the model with respect to the bizarre data since the remaining 20% are the case tests. This division ensures that the model is applicable to other scenarios and capable of estimating new real world of data. This prevents the model being over fitted andmakesitopentohealthyappraisal.
iv) Algorithms:
Thisis a basicinstance basedlearning algorithmknown as K-Nearest Neighbors (KNN) which is employed to address classification and regression problems. It determineswhattodobasedondistancemeasuressuch asEuclideandistancetomakecomparisonsofa pieceof data with similar pieces in the training set. It classifies thedatapointsintoclustersaccordingtothelabelthatis mostpopularaspertheKNN[11].KNNisalsosimpleto comprehend and can be used on small datasets. Nevertheless, it may be difficult to work with large datasetssinceitconsumesalotofcomputingpower.
Logistic Regression is a statistical modeling to address two-choice problems. It approximates the probability of apieceofdatainagivengroupusingthelogisticfunction
on a linear combination of factors of input. The model assigns probabilities in between 0 to 1 and thus can be appliedtobothtrueandfalseresults.Logisticregression isstraightforward,understandable,andapplicablewhen thereisastraightlinethatthedatacanbedividedinto.
Thesimplelinearregressionline,
^y=a+bxy^=a+bx (1)
canbetakentomean:
Where y is the expected value of y, a is the intercept (where the regression line crossing the y-axis), and b is thechangeinyperunitchangeinx.
Random Forest is an ensemble algorithm, which combines many decision trees to increase the accuracy of classification and reduce overfitting. It works on the principle of creating multiple decision trees in the training stage, where each tree is independent in its forecast. The ultimate output is ascertained by consolidatingtheforecastsofalltrees,generallythrough majority vote. 3 RF is efficient in working with large datasetsandprovidinghighperformance,particularlyin workingwithcomplexdata.
The Voting Classifier is a composite of many models that are used to enhance the overall accuracy and strength. This method uses both Boosted DT that improve the performance of the model by progressively correcting the errors of the previous trees, and ExtraTrees that increase the diversity of the model by using random feature subsets. Such an ensemble approach enjoys the benefits of various models, providing increased accuracy and reliability in predictions.
Accuracy:Accuracy of a test is the ability of a test to distinguish between patients and healthy individuals. In order to measure the accuracy of tests, calculate the proportions of true positive and true negative results of all the instances that are tested. This would be mathematicallyexpressedas:
Precision:Precision is a measure of the percentage of recognised positive cases or samples. The formula used todetermineprecisionis:
International
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net
Recall:ML recall is the measure of how well a model determines all relevant examples of a category. It illustrates the effectiveness of a model in summarizing the cases of a class by accurately relating the expected positivecaseswiththenumberofpositivesintotal.
F1-Score:TheF1scoreisusedtodeterminetheaccuracy of a ML model. Combining model accuracy and recall.
Table.1: PerformanceEvaluationMetricsofclassification
The accuracy measure determines the number of accuratepredictionsthatamodelmakesoveradataset.
Table 1 shows the performance measures of accuracy, precision, recall and F1-score evaluated against each algorithm. The Voting Classifier scores best, with all at 100%. Alternative method metrics are also given to compare.
Fig-3: ComparisonGraphsofClassification
Accuracy,precision,F1-Score,andrecallarerepresented in light green, blue, light yellow, and green, respectively in Graph 1. The Voting Classifier outperforms all the other algorithms in all settings, and has the best values compared to the other models. These features can be graphicallydisplayedinthegraphabove.
The research is a distinctive semi-supervised type of learning that focuses on improving the accuracy of the one-year death predictions after the heart transplantation in children. To enhance the reliability
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
and stability of the model, we incorporated synthetic examples that are designed based on hypothetic donorrecipient pairings that are as close to real-world scenarios as possible. Our algorithm involves the use of unlabeled data within a self-training system, which significantly boosts prediction accuracy. The results confirm the effectiveness of thisapproach,asthe Voting Classifier (Boosted Decision Tree + ExtraTree) has achieved an impressive accuracy of 100%. This algorithm shows the effectiveness of semi-supervised learning coupled with synthetic data to improve predictive models in clinical settings. This plan will improve the prediction accuracy, which is of great help in decision-making in the field of pediatric heart transplantation, therefore, the optimal matching of the donor and recipient and the improved outcomes of patients.
Future studies will explore how to optimize parameters such as the definition of gain ( ) and the kind of base learner in self-training models. Additionally, novel clusteringalgorithmswillbeinvestigatedtoenhancethe production of synthetic observation sets, which are crucial in enhancing semi-supervised learning effectiveness. These advances aim at improving the methodology and ensuring good results particularly in cases where there is limited labelled data so that the techniques can be more effectively applied in a wide rangeofdisciplines.
[1] A. Ashfaq, G. M. Gray, J. Carapellucci, E. K. Amankwah, L. M. Ahumada, M. Rehman, J. A. Quintessenza,andA.Asante-Korang,‘‘Predictingone yearmortalityusingmachinelearningafterpediatric heart transplantation: Analysis of the united networkoforgansharing(UNOS)database,’’J.Heart Lung Transplantation, vol. 41, no. 4, p. S152, Apr. 2022.
[2] A. E. Braat, J. J. Blok, H. Putter, R. Adam, A. K. Burroughs,A.O.Rahmel,R.J.Porte,X.Rogiers,andJ. Ringers, ‘‘The eurotransplant donor risk index in liver transplantation: ET-DRI,’’ Amer. J. Transplantation,vol.12,no.10,pp.2789–2796,Oct. 2012.
[3] L. Breiman, ‘‘Random forests,’’ Mach. Learn., vol. 45, pp.5–32,Oct.2001.
[4] J.Bullock,M.Grieco,Y.Liu,I.Pedersen,W.Roberson, G. Wright, P. Alonzi, M. A. McCulloch, and M. D. Porter, ‘‘Determining factors of heart quality and donor acceptance in pediatric heart transplants,’’ in Proc.Syst.Inf.Eng.DesignSymp.(SIEDS),Apr.2021, pp.1–6.
[5] [Online].Available:http://optn.transplant.hrsa.gov
[6] A. Chebli, A. Djebbar, and H. F. Marouani, ‘‘Semisupervised learning for medical application: A survey,’’inProc.Int.Conf.Appl.SmartSyst.(ICASS), Nov.2018,pp.1–9.
[7] M. Colvin, J. M. Smith, Y. Ahn, M. A. Skeans, E. Messick, K. Bradbrook, K. Gauntt, A. K. Israni, J. J.
Snyder,andB.L.Kasiske,‘‘OPTN/SRTR2020annual datareport:Heart,’’Amer.J.Transplantation,vol.22, pp.350–437,Mar.2022.
[8] A. I. Dipchand, ‘‘Current state of pediatric cardiac transplantation,’’ ASVIDE, vol. 5, pp. 1–116, Feb. 2018.
[9] N.Gotlieb, A.Azhie, D. Sharma,A. Spann, N.-J. Suo, J. Tran,A.Orchanian-Cheff,B.Wang,A.Goldenberg,M. Chassé, H. Cardinal, J. P. Cohen, A. Lodi, M. Dieude, and M. Bhat, ‘‘The promise of machine learning applications in solid organ transplantation,’’ NPJ Digit.Med.,vol.5,no.1,pp.1–13,Jul.2022
[10] C. Hyldahl, O. Kaczmarskyj, J. Laruffa, A. Miller, L. Snavely, A. Wan, and S. L. Riggs, ‘‘Designing a dashboard to streamline pediatric heart transplant decision making,’’ in Proc. Syst. Inf. Eng. Design Symp.(SIEDS),Apr.2023,pp.237–242.
[11] J.M.G.Taylor,‘‘Randomsurvivalforests,’’J.Thoracic Oncol.,vol.6,no.12,pp.1974–1975,Dec.2011.
[12] M. O. Killian, S. Tian, A. Xing, D. Hughes, D. Gupta, X. Wang,andZ.He,‘‘Predictionofoutcomesafterheart transplantation in pediatric patients using national registry data: Evaluation of machine learning approaches,’’ JMIR Cardio, vol. 7, Jun. 2023, Art. no. e45352.
[13] J. K. Kirklin, D. C. Naftel, R. L. Kormos, L. W. Stevenson, F. D. Pagani, M. A. Miller, J. T. Baldwin, and J. B. Young, ‘‘The fourth INTERMACS annual report: 4,000 implants and counting,’’ J. Heart Lung Transplantation, vol. 31, no. 2, pp. 117–126, Feb. 2012.
[14] S. M. Lundberg and S.-I. Lee, ‘‘A unified approach to interpretingmodelpredictions,’’inProc.Adv.Neural Inf.Process.Syst.,2017,pp.1–11.
[15] R. Miller, D. Tumin, J. Cooper, D. Hayes, and J. D. Tobias, ‘‘Prediction of mortality following pediatric hearttransplantusingmachinelearningalgorithms,’’ Pediatric Transplantation, vol. 23, no. 3, May 2019, Art.no.e13360.
[16] R.J.H.Miller,F.Sabovčik,N.Cauwenberghs,C.Vens, K. K. Khush, P. A. Heidenreich, F. Haddad, and T. Kuznetsova, ‘‘Temporal shift and predictive performance of machine learning for heart transplantoutcomes,’’J.HeartLungTransplantation, vol.41,no.7,pp.928–936,Jul.2022.
[17] V. Naruka, A. Arjomandi Rad, H. Subbiah Ponniah, J. Francis,R.Vardanyan,P.Tasoudis,D.E.Magouliotis, G. L. Lazopoulos, M. Y. Salmasi, and T. Athanasiou, ‘‘Machine learning and artificial intelligence in cardiac transplantation: A systematic review,’’ Artif. Organs,vol.46,no.9,pp.1741–1753,Sep.2022.
[18] X.Yang,Z.Song,I.King,andZ.Xu,‘‘Asurveyondeep semi-supervised learning,’’ IEEE Trans. Knowl. Data Eng.,vol.109,no.2,pp.1–20,Aug.2022.
[19] R. J. Williams, M. Lu, L. A. Sleeper, E. D. Blume, P. Esteso, F. Fynn-Thompson, C. J. Vanderpluym, S. Urbach, and K. P. Daly, ‘‘Pediatric heart transplant waiting times in the United States since the 2016 allocation policy change,’’ Amer. J. Transplantation, vol.22,no.3,pp.833–842,Mar.2022.
[20] Porter, M. D., Sharff, J. R., Dixon, R., Haregu, F., & McCulloch, M. (2024). Using Machine Learning to AssessthePredictivePowerofDonorCharacteristics inPediatricHeartTransplantOutcomes.TheJournal ofHeartandLungTransplantation,43(4),S622.