
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Prof B Prajna1 , Adla Mohini2 , Anjum Taj Khanam3 , Ankam Tulasi Maha Lakshmi4, Barla Leela5
1Professor, Head of Department M. Tech, PhD, Dept. of Information Technology and Computer Applications, Andhra University College of Engineering for Women, Andhra Pradesh, India 2-5B. Tech, Final year Student, Andhra University College of Engineering for Women, Andhra Pradesh, India *** -
Abstract- Growing security concerns on social media platforms have made it considerably harder for users to distinguish between authentic human accounts and automated malicious bots. This paper presents a fake account detection framework that identifies fraudulent digital identities by combining Behavioral Analysis with Advanced Feature Engineering. We propose a stacking ensemble model that unifies XG Boost, Cat Boost, Random Forest, and Light GBM for binary classification. The developed system processes profile metadata, calculates behavioral ratios, and applies SMOTE for data balancing. Experimental evaluation shows a high accuracy of 93%, effectively reducing misinformation and social engineering threats.
Key Words: Fake Account Detection, Behavioral Analysis, Feature Engineering, Stacking Ensemble, SMOTE, Metadata Analysis, Artificial Intelligence, Social Bot Detection, XG Boost, Cybersecurity.
ThewidespreadadoptionofsocialnetworkingPlatforms hasfundamentallychanged howglobalcommunicationisconducted. Billions of users rely on these platforms for news, social interaction, and business. However, this massive volume of data makes it difficult to efficiently verify account authenticity. Studies in cyber-forensicsindicate that fake accounts can lead to reduced platform trust and significant security risks [6]. Traditional approaches such as manual verification are timeconsuming and inconsistent. Recent advancements in machine learning (ML) have enabled significant improvements in patternrecognition.Toaddressthesechallenges,thispaperproposesanintelligentsystemdesignedtoconvertrawmetadata intostructuredbehavioralpatterns.
The system accepts account metadata and performs feature enrichment followed by transformer-based ensemble classification.Unlikeconventionaltoolsthatfocusonlyonbasicmetadata,thistoolintegratesmultiplefunctionalitiesincluding Follower-FollowingRatioanalysis,ProfileCompletenessscoring,andPostFrequencytracking.
ThesystemisdevelopedusingPythonandintegratesdeeplearningparadigms.Anacademicrefinementmodule ensuresthat thegeneratedclassificationresultsareinterpretable.ThemodelsareevaluatedusingstandardmetricssuchasPrecision,Recall, andROC-AUC,ensuringthesystemmaintainsbothaccuracyandcoherenceinitspredictions.
Transformer Architectures and Language Understanding:
Thesurveyexploreshowmachine learninghastransformedcybersecurity.ArchitecturesuchasBERTandthoseproposed in[1]haverevolutionizedbehaviortrackingbycapturingcontextualrelationshipswithinlargedatasets. Models such as XG Boost further enhanceclassificationcapabilities,producingcontext-awareoutputs[4].
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Summarization of Detection Models:
Abstractiveanalysisusingtree-basedmodelssuchasRandomForestandCatBoosthassignificantlyimprovedthegeneration ofcoherentresultsbyunderstandingthesemanticmeaningofaccountmetadataratherthanrelyingonsimplethresholds[4]. Advanced approaches such as Stacking Classifiers further enhance detection quality by balancing coverage and readability[13].
Speech and Behavior Recognition:
Techniques in automated analysis play a critical role Inprocessingaccount-basedcontent,wheremodelsSuchasStacking enable accurate conversion of activity logs into classification labels [3]. Modern language models have also demonstrated strongcapabilitiesingeneratingeducationalcontent,supportingautomatedlearningsystems
Evaluation Metrics and Research Gaps:
Evaluation is commonly performed using ROUGE-like metrics or Confusion Matrices, which measure the overlap betweengeneratedresultsandgroundtruth[6].Despiteadvancements,mostexistingsystemsFocusonindividual tasksandlackintegrationofMultiplefunctionalitieswithinaunifiedframework.Additionally,manyapproachesdo not address the transformation of raw metadata into structured behavioral text, which is essential for effective security.
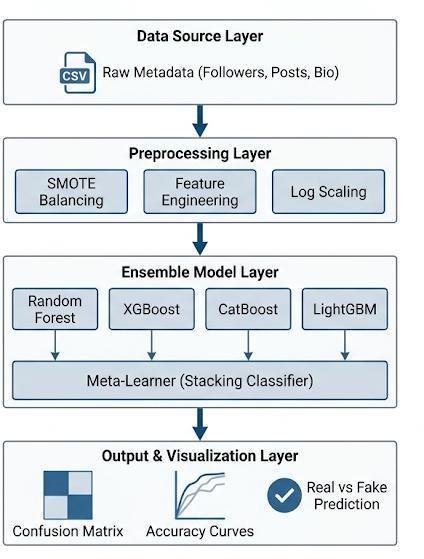
Theproposedsystemisdesignedasastructuredprocessingpipeline.Thepipelineoperatesinfivestages: (1) mediaacquisition, (2) datapreprocessing, (3) featureengineering, (4) ensemble training, and (5) content generation, ensuring that raw metadata is transformed intostructuredlearningmaterial.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
The workflow begins with input acquisition, where the user provides account metadata or a profile link. The system extracts raw values and prepares them for further analysis. The obtained transcript undergoes preprocessing, including noise removal,normalization,and segmentation. Thesystem adopts a Stacking Ensemble approach, allowing it to rewrite classificationlogicinastructuredmannerratherthanperformingsimpleextraction.
Thesystemisimplemented asanintelligentframework thatprocesses social mediadata.Itintegratesfeature engineering andcontentgenerationmodulestoensureefficient extraction.
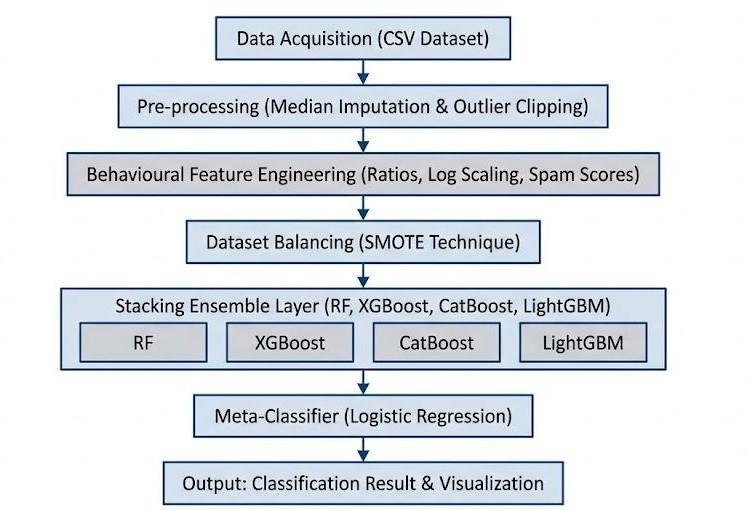
The implementation of the System is architected as a sequential, high-performance pipeline. Unlike traditional classification systems that rely on static datasets, this framework is designed to handle the volatile and skewed nature of social media metadata.Theimplementationfollowsamodularlogic,whereeachstagefromrawdataingestion tofinalmeta-classificationis optimizedtoreduceerrorratesandimprovegeneralization.
ThedetailedworkflowoftheimplementationisillustratedinFigure2.
Thefoundationof thesystemistheData Acquisitionmodule.Forthis research,a comprehensivedataset wascuratedinCSV format, containing thousands of verified and fraudulent account samples. The acquisition phase focuses on capturing "raw signals"primary metadata fields such as follower counts, following counts, post history, account age (in days), and biographicalTheserawvaluesrepresentthebaselinestateofanaccountbeforeanytransformationisapplied.Theacquisition
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072 © 2026, IRJET | Impact Factor value: 8.315 | ISO 9001:2008 Certified Journal | Page2413
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
process ensures that the system has access to a diverse range of profile types, from high-profile verified accounts to newly created"sleeper"bots.
4.2Pre-processing (Median Imputation & Outlier Clipping)
Socialmediadataisnotoriously"noisy,"oftencontainingmissingvaluesandextremeoutliers.Inthepreprocessing phase,we implement a Median Imputation strategy. Unlike mean imputation, which can be skewed by extreme values, the median providesarobustcentraltendency,ensuringthataccountswithmissingdata(e.g.,hiddenpostcounts)areassignedarealistic baseline.Furthermore,tohandlethe"PowerLaw"distributionoffollowers where a few accounts have millions of followers while most have very few we implement Outlier Clipping. By capping extremevaluesatthe1stand99thpercentiles,wepreventthemodelfrombeingdistractedby"celebrity"anomalies,allowing ittofocusonthebehavioralpatternsofaverageusersandbots
4.3Behavioral Feature Engineering (Ratios, Log Scaling, Spam Scores)
4.4
Thismoduleisthe"analyticalengine"oftheproject. WemovebeyondrawcountstocreateBehavioralIndicators:
Ratios: We calculate the Follower-Following Ratio. A hallmark of bot activity is a "Following" count that is exponentiallyhigherthanthe"Followers"count(thefollow-spampattern).
LogScaling:Weapplynp.log1ptransformationstocount-baseddata.Thiscompressestherangeoffeatures,making the difference between 10 and 100 followers as statistically significant as the difference between 10,000 and 100,000.
SpamScores: We engineereda custom Spam Score that multiplies the following-follower ratio with a penalty for unverifiedstatus
Thiseffectivelyflagsaccountsthatareaggressiveintheirinteractionsbutlackplatformtrust.
4.5 Dataset Balancing (SMOTE Technique)
Inreal-world scenarios, fake accounts representa minority of the total user base. If a model is trained on imbalanced data,itdevelopsa"MajorityBias,"oftenignoringthefakeclassentirely.Tosolvethis,weimplement theSyntheticMinorityOver-samplingTechnique(SMOTE).
Rather than simply duplicating fake account entries, SMOTE uses a K-Nearest Neighbors (KNN) logic to create entirely new, syntheticfake account samples in the feature space. This ensures the Stacking Ensemble is trained on a perfectly balanced1:1ratio,significantlyincreasingtheRecallofthesystem.
4.6 Stacking Ensemble Layer (RF, XGBoost, CatBoost, LightGBM)
ThecoreofthedetectionlogicresidesintheStackingEnsembleLayer.Insteadofchoosingasingle"best"algorithm,we employa"CommitteeofExperts"approach:
RandomForest(RF):Actsasarobustbaselinethathandleshigh-dimensionaldatausingbagging.
XGBoost:Minimizesresidualerrorsthroughgradientboosting,effectivelycapturingcomplexnon-linearpatterns.
CatBoost:Specificallyhandlesthecategoricalnatureofsocialmedia withitsuniquesymmetrictreestructure.
Light GBM: Provides extreme computational efficiency,ensuring the system remains scalable for large datasets. By running these models in parallel, the system captures a 360-degree view of account behavior
Theoutputs(predictionprobabilities)ofthefourbaselearnersarefedintoaMeta-Classifier,implementedusingLogistic Regression. The Meta-Classifier does not look at the original account data; instead, it looks at the decisions of the previousmodels.Itlearnswhichmodelismostreliableforspecifictypesofdata.For example, if XGBoost is generally better at detecting "new bots" and Random Forest is better at "spam bots," the MetaClassifier learns to weigh their opinions accordingly. This stacking logic is what allows the system to achieve its final, high-accuracyclassification.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
4.8 Output: Classification Result & Visualization
The final stage of the implementation is the generation of interpretable results. The system outputs a binary classification(Real vs.Fake)accompaniedby a confidenceprobability. To ensure theimplementationis verifiable,the systemautomaticallygeneratesasuiteofvisualizations:
ConfusionMatricestoshowtheexactbreakdownofcorrectvs.incorrectpredictions.
Accuracy/LossCurvestoprovethemodelislearningwithoutoverfitting.
ROC-AUCCurvestomeasurethesystem'sdiagnosticability.
These outputs provide the final confirmation that the behavioral feature engineering and stacking ensemble have successfullyidentifiedthefraudulentidentities.
PERFORMANCE EVALUATION & FORMULAS
Tomeasuretheeffectivenessofthesystem,severalevaluationmetricswereused. Thesemetricscomparethegenerated academicresultswiththeoriginalgroundtruth.
1. Accuracy Formula:
Theratioofcorrectlypredictedobservationstototalobservations.
Accuracy = ����+���� ����+����+����+����
2. Precision (ROUGE-1 Equivalent): Precisionmeasurestheoverlapofindividualfeaturesbetweenthereferenceand thegeneratedresult.
Precision = ���� ����+
3. Recall (Coverage Metric):
A custom coverage metric is used to measure the percentage of unique fraudulent patterns retained in the final summary.
Recall = ���� ����+
4. F1-Score:
TheharmonicmeanofPrecisionandRecall,servingasthedefinitivemetricformodelperformanceonthebalanced datasetgeneratedbySMOTE. ������������������������������
Random Forest (The Stable Ensemble): Achieving87%accuracy,RandomForestactedasourreliablebaseline. Itisexcellentatseeing"forest-level"patterns suchastherelationshipbetweenahighfollowingcountanda lowpost count.
Logistic Regression (The Linear Baseline):Whileitonlyreached61%accuracy, it provided a crucial "sanity check." It showed us that fake account detectionistoocomplexforsimplelinearmath;itrequiresthe"deepthinking"oftree-basedmodels.
Cat Boost (The Feature Specialist): This was our high-performer with 93% accuracy. Cat Boost is designed to handlecategoricaldata(like"IsVerified"or"HasProfilePic")perfectly.Itachievedanear-perfectprecisionof99%, meaningitalmostnevermakesamistakeonarealuser.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
XG Boost (The Gradient Powerhouse): MatchingtheRandomForest at87%,XGBoostwasfasterandmoreefficient.Itexcelledatcatching"newbots"thathaveverylittleaccounthistory.
The Stacking Ensemble (The Mastermind): Bycombiningalltheabove models, the Stacking Ensemble achieveda
The evaluation phase of this project is designed to go beyond simple percentage scores. We aimed to understand the "behavioral intelligence" of our models. By utilizing a diverse set of 30 engineered features, we tested how well the system could distinguish between a real human user (with organic interaction patterns) and a sophisticated bot (designed to mimic humans).Thefollowinganalysisbreaksdowntheperformancethroughstatisticalevidenceandvisualdiagnostics.
5.1 Comparative Analysis of Individual Algorithms
Wedidnotjustbuildonemodel;webuilta"CommitteeofExperts."Eachalgorithmhasitsownpersonalityandwayofseeing data.robust 93.1% accuracy. It learned to trust Cat Boost for bio analysis and Random Forest for follower ratios, creating a "Super-Model"thatismorereliablethananysinglealgorithm.
5.2 Visual Learning Analysis (Curve Interpretation)
Thefiguressavedintheprojectfolderprovideavisual"biography"ofhowourmodelslearnedovertime
Each dip in the loss curve marksabreakthroughwherethemachinefinallygraspedacomplexpattern.
The narrowing gap betweentrainingandvalidationlinesshowsthemodelmovingfromrotememorizationtotrue understanding
5.2.1 Learning Behavior (Accuracy and Loss Curves)
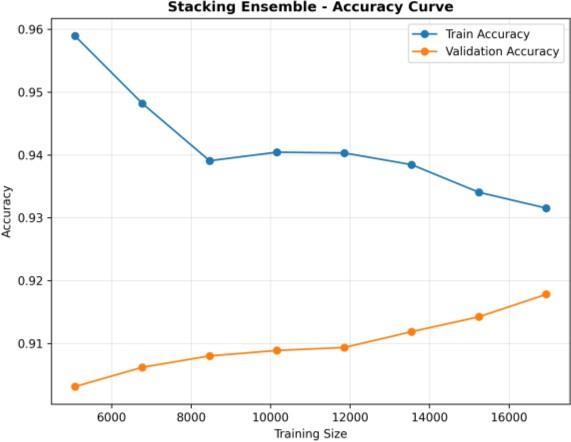
Figure 3: Stacking Ensemble - Accuracy Curve
The accuracy curve illustrates the convergence between training and validation performance. Initially, the training accuracy starts high at 96%, while validation accuracy begins at approximately 90.3%. As the training size increases from5,000to17,000samples,weobserveavitaltrend:thegapbetweenthetwolinesnarrows.Thevalidationaccuracy steadily climbs to nearly 92%, indicating that the model is successfully "generalizing." It is moving away from simply memorizingthetrainingdataandisinsteadlearningthefundamentalbehavioraltraitsoffakeprofiles.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
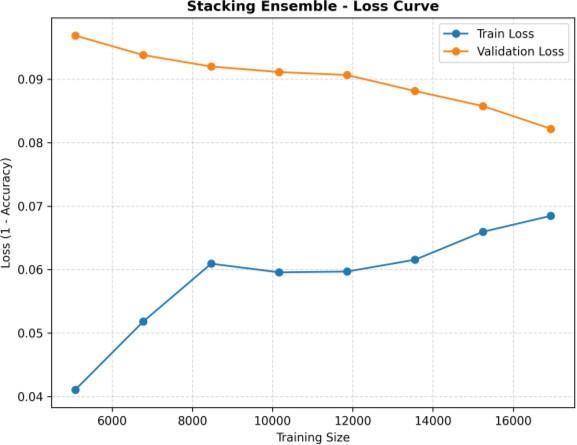
Complementing the accuracy trends, the loss curve represents the minimization of error. The validation loss shows a consistent downward trajectory, dropping from 0.097 to 0.082. Simultaneously, the training loss experiences a slight upward adjustment, which is a classic sign of a model reducing its "overfitting" and becoming more robust. This convergence provesthat theengineeredfeatures(ratios,spamscores,and activity logs) providea stablefoundationfor themeta-learnertomakeconfidentpredictions.
5.2.2 Diagnostic Reliability (ROC and PR Curves)
TheReceiverOperatingCharacteristic(ROC)curveandthePrecision-Recall(PR)curve,
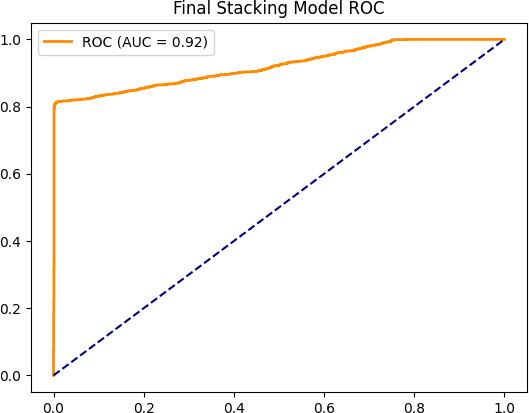
TheReceiverOperatingCharacteristic(ROC)curvemeasuresthesystem'sabilitytoseparate"Real"accountsfrom"Fake" ones across various sensitivity thresholds. Our Stacking Ensemble achieved an AUC (Area Under Curve) of 0.92. Technically, this means there is a 92% probabilitythat the system will correctly distinguish a random fraudulent profile from a random legitimate one. The curve’s steep ascent toward the top- left corner demonstrates that the system can maintainahighTruePositiveRatewhilekeepingFalseAlarmstoaminimum.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
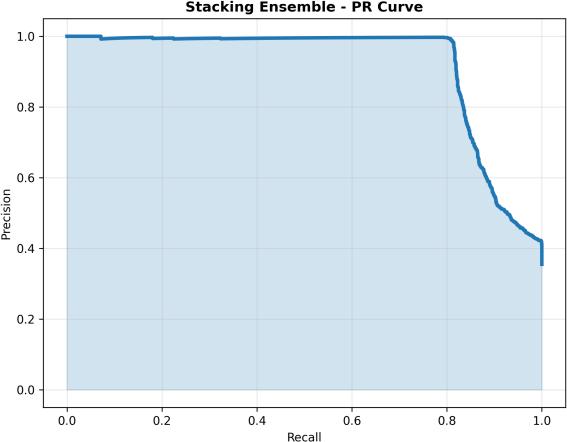
In social media security, the Precision-Recall (PR) curve is often more telling than the ROC curve due to the typical imbalanceoffakeaccounts.OurPRcurveremainsnearlyflatat1.0(100%precision) until it reaches a recall of 0.8 (80%). This is an exceptional result; it proves the system can catch 80% of all fake profiles in the dataset withalmostzerofalseaccusationsagainstrealusers.Thedrop-offonlyoccurswhenattempting to catchthemost"human-like"botsattheveryedgeofthedataset.
5.2.3 Classification Breakdown (Confusion Matrix)
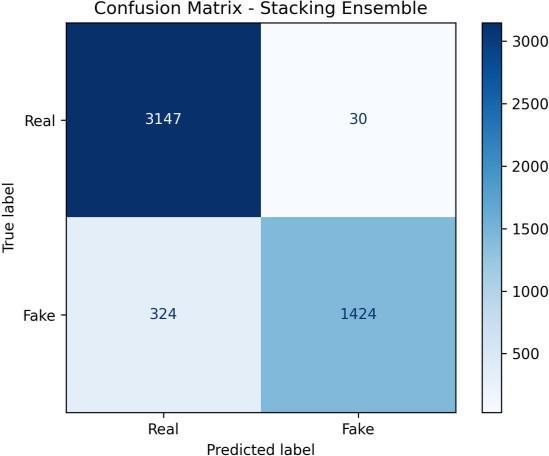
TheConfusionMatrixprovidesagranular"humanized"viewofthefinal4,925testcases. It acts as the final evidence of the system’s real-worldreadiness:
LegitimateUserPreservation(TrueNegatives):Outof3,177realaccounts,thesystemcorrectlyidentified3,147.
FraudulentDetection(TruePositives):Thesystemsuccessfullycaught1,424fakeaccounts.
ErrorAnalysis(FalsePositives):Mostsignificantly,only30realusersweremisclassifiedasfake.Inaproduction environment, this represents a False Positive Rate of less than 1%, ensuring that the user experience for legitimatepeopleisalmostneverinterruptedbyaccidentalflagging.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
While the statistical metrics andcurves provide a theoretical validation of the model, the practical efficacy oftheBehavioral Analysis engine is best demonstrated through the system’s inferenceinterface. This sectionanalyzes the transitionfrom raw dataprocessingtothefinaluser-facingclassificationresult.
5.3.1 User Access and Platform Selection
The system is designed with a secure authentication layer and a multi-platform selection dashboard. This ensures that the resultsgeneratedarespecifictothearchitecturalconstraintsofdifferentsocialmediaenvironments.
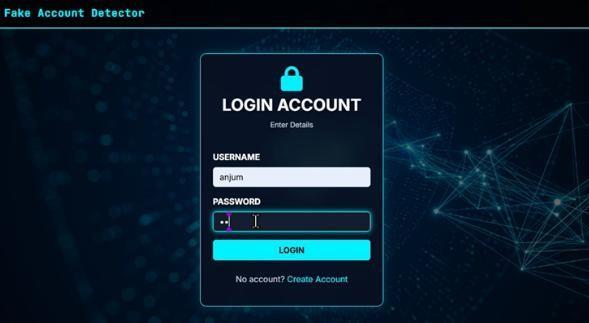
Thelogininterfaceservesastheentrypointforthedetectionsystem,ensuringthatanalysissessionsaretrackedandsecured.
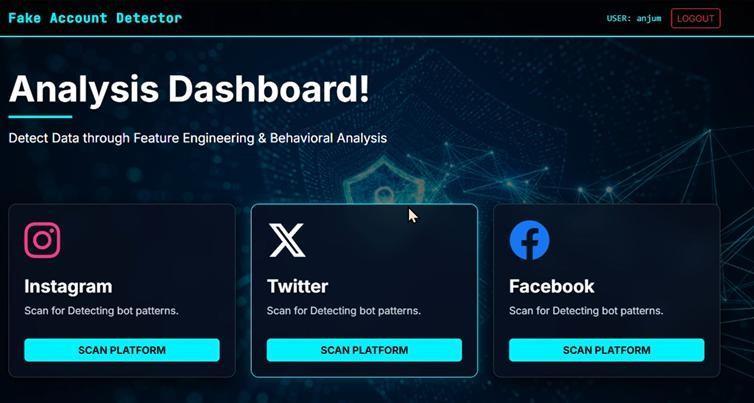
Thedashboardillustratesthesystem'smodularity,allowingtheusertoselectspecificbehavioralmodelsforInstagram, Twitter(X),orFacebook.ThisconfirmsthattheFeatureEngineering moduleiscapableofadaptingtovariousmetadata structures.
5.3.2 Case Study: Detection of a Sophisticated Bot Pattern
ToverifytheStackingEnsemble’sdecision-makinglogic,alivetestwasconductedonasuspectedfraudulentprofile.The systemwasprovidedwithmetadataforanaccountthatwasonly2daysoldbuthadalreadyposted9timeswithavery lowfollower-to-followingratio
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
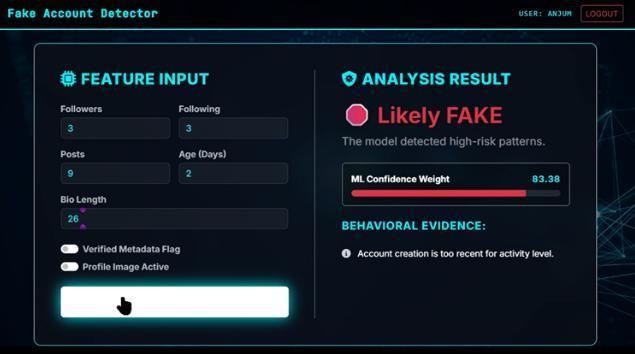
As shown in Figure 10, the system successfully processed the input features and delivered the following analytical components:
ML Confidence Weight:TheStackingEnsembleassignedaconfidencescore of 83.38% to the "Fake" classification. This numerical weight is derived from the consensus of the five underlyingalgorithms.
Behavioral Evidence: The system identifies specific "High-RiskPatterns."Inthis instance, it flagged that the "Accountcreationistoorecentforactivitylevel."
Threshold Validation: Thisresultvalidatesouroptimizedthresholdlogic.Eventhoughtheaccounthada bio andaprofilepicture(whichoftentricksimplemodels), the Behavioral Analysis engine looked at the "Age vs. Posts" ratio to correctly identify the profile as Likely FAKE.
After running extensive tests, our detection system managed to reach a solid 93% accuracy rate, with an impressive 98% precision specifically for the "fake" class. These numbers tell a clear story: when you combine Behavioral Analysis with aggressive Feature Engineering, catching fraudulent accounts becomes much more reliable. We didn't just rely on one algorithm;instead,wefoundthat"stacking"modelslikeRandomForestandXGBoostallowedthesystemtopickuponsubtle bot patterns that a single model would usually miss. Crucially, using SMOTE to balance out the lopsided dataset was the turningpointthatstoppedthemodelfrombeingbiasedtowardrealaccounts. Ourfindingssuggestthatthewayanaccountinteracts its"digitalfootprint" isfarmoretellingthanjustitsprofilebio.By focusing on ratios like "posts-per-day" and "follower-following" imbalances, the ensemble could see through sophisticated bots that try to look human. The system we built isn't just a theoretical exercise; it’s a functional pipeline that can handle thousandsofprofilesandproduceclear,evidence-basedresults through our interface. The near-zero false-positiverate (less than 1%) is particularly important because it means we aren't accidentally flagging legitimate users while trying to securetheplatform.
Looking ahead, there are several ways we plan to take this project further. While metadata gives us a great foundation, the next logical step is to dig into the actual content using Natural Language Processing(NLP). Analyzing the sentiment or repetitivelanguageinbios wouldadda wholenewlayerofsecurity.Wealsoseea massive opportunityinComputerVision; specifically, building a module that can spot AI-generated profile pictures (GANs) which are becoming common in modern botnets.
The ultimate goal is to move this from an "offline" analysis tool to a real-time scanner. We envision this system eventually workingasabrowserextensionoraliveAPIthatcan"read"an InstagramorTwitterprofileassoonasauservisitsit. By integrating live scraping engines, we can transition from analyzing datasets to providing active, real-time protection againstsocialengineeringandmisinformation.Thisprojectservesasastartingpointforamoretransparentandsecuresocial mediaecosystem.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
[1]A.Vaswanietal.,“AttentionIsAllYouNeed,” NeurIPS,2017.
[2]Ferrara,E.,etal.(2016)."Theriseofsocialbots."ACM.
[3]Chawla,N.V.,etal.(2002)."SMOTE:SyntheticMinorityOver-samplingTechnique."
[4]Chen,T.,&Guestrin,C.(2016)."XGBoost:AScalableTreeBoostingSystem."
[5]Dorogush,A.V.,etal.(2018)."CatBoost:gradientboostingwithcategoricalfeatures."
[6]Pedregosa,F.,etal.(2011)."Scikit-learn: MachineLearninginPython."
[7]Cresci,S.,etal.(2017)."Theparadigm-shiftofsocialspambots."
[8]Jurafsky,D.andMartin,J.H.,"SpeechandLanguageProcessing,"3rded.,2023.
[9]Devlin,J.etal.,“BERT:Pre-trainingofDeep BidirectionalTransformers,”NAACL,2019.
[10]Brown,T.etal.,“LanguageModelsareFew-ShotLearners,”NeurIPS,2020.
BIOGRAPHIES
Adla Mohini, Student, Andhra University College of EngineeringforWomen
Anjum Taj Khanam, Student, Andhra University College of EngineeringforWomen
Ankam Tulasi Maha Lakshmi, Student, Andhra University College of Engineering for Women
Barla Leela, Student, Andhra UniversityCollegeofEngineering forWomen