
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Vivek Shukla1 , Dr. J.B. Singh2, Mr. Rajesh Kumar Sharma3
1Master of Technology, Computer Science and Engineering, Sagar Institute of Technology and Management, Barabanki, India
2Professor, Department of Computer Science and Engineering, Sagar Institute of Technology and Management, Barabanki, India
3Assistant Professor, Department of Computer Science and Engineering, Sagar Institute of Technology and Management, Barabanki, India
Abstract -Serverlesscomputinghasemergedasapromising paradigm for deploying machine learning (ML) inference workloads due to its scalability, flexibility, and pay-per-use pricing model. However, achieving an optimal balance between operational cost and system latency remains a significant challenge, particularly under dynamic and unpredictable workload conditions. Existing approaches largelyrelyonstaticresourceprovisioningorreactivescaling mechanisms, which often result in inefficient resource utilization, increased latency, and higher operational costs. Thispaperproposesapredictiveandadaptiveframeworkfor cost–latency trade-off modeling in serverless ML inference systems. The approach integrates workload forecasting techniques, including ARIMA and Long Short-Term Memory (LSTM) models, to anticipate future request patterns and enable proactive resource allocation. A multi-objective optimization model is developed to jointly minimize cost and latency, leveraging weighted andPareto-based strategies for efficientdecision-making.Theframeworkdynamicallyadjusts resource parameters such as memory allocation and concurrency levels based on predicted workloads and realtime feedback. Experimental evaluation using synthetic and real-world workload traces demonstrates that the proposed approach significantly improves system performance compared to baseline models. Results indicate reductions in latency and improved cost efficiency while maintaining scalabilityandrobustnessundervaryingworkloadconditions. The proposed framework provides a practical and effective solution for optimizing serverless ML inference deployments.
Key Words: Serverless Computing, Machine Learning Inference, Cost–Latency Trade-Off, Workload Forecasting, LSTM, Multi-objective Optimization
The rapid advancement of cloud computing has fundamentally transformed how computational resources are provisioned and consumed, particularly for dataintensive applications such as machine learning (ML). In recent years, serverless computing has emerged as a paradigmthatabstractsinfrastructuremanagementwhile enabling dynamic scalability and fine-grained billing. This
shiftisespeciallyrelevantforMLinferencesystems,where real-time responsiveness and cost efficiency are critical. However,despite theseadvantages, balancing operational costandlatencyremainsacomplexchallenge,particularly underhighlydynamicworkloads.Thissectionintroducesthe background, problem context, research gap, and key contributionsofthisstudy.
1.1.1
Cloudcomputinghasevolvedfromtraditional on-premise infrastructurestohighlyabstractedservicemodelsthatoffer scalabilityandflexibility.Initially,virtualizationtechnologies enabled efficient resource sharing by allowing multiple virtualmachinestorunonasinglephysicalsystem.Thiswas followed by containerization, which further improved deploymentefficiencyandportability.Thelatestevolutionis serverlesscomputing,alsoknownasFunction-as-a-Service (FaaS), where developers deploy functions without managingunderlyinginfrastructure.Inthismodel,resources areautomaticallyprovisionedandscaledbasedondemand, and users are billed only for actual execution time. This paradigm significantly reduces operational overhead and enables fine-grained scalability, making it well-suited for event-drivenapplications(Baldinietal.,2017;Jonasetal., 2019).
Machinelearninginferencehasbecomeacorecomponentof modern applications such as recommendation systems, frauddetection,healthcarediagnostics,andnaturallanguage processing. Unlike training, inference requires rapid processingofincomingdatatogeneratepredictionsinreal time. This necessitates low-latency responses and high system availability. Serverless platforms provide an attractiveenvironmentfor deployinginferenceworkloads due to their ability to scale automatically with fluctuating demand. However, maintaining consistent performance whilecontrollingcostinsuchenvironmentsischallenging,
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
especiallyforlatency-sensitiveapplications(Hellersteinet al.,2019).
1.2.1
Many serverless ML inference systems rely on static resource provisioning, where memory and compute resourcesarepredefined.Whilethissimplifiesdeployment, itoftenleadstoinefficiencies.Duringperiodsoflowdemand, resources remain underutilized, increasing operational costs,whereasduringpeakdemand,insufficientresources candegradeperformanceandincreaselatency(Wangetal., 2018).
A significant challenge in serverless environments is cold startlatency,whichoccurswhenafunctionisinvokedafter being idle. The initialization process, including container setup and model loading, introduces delays that can significantly impact response time. This is particularly problematicforMLinferenceworkloads,wheremodelsare often large and require substantial initialization overhead (WangandPatel,2021).
Serverless platforms typically employ reactive scaling mechanisms,whichallocateresourcesonlyafterachangein workload is detected. While effective for gradual changes, these mechanisms struggle to handle sudden spikes in demand,leadingtoincreasedlatencyandpotentialservice degradation. The delayed response inherent in reactive systemslimitstheireffectivenessindynamicenvironments (Carreiraetal.,2018).
1.2.4
Existing approaches often treat cost and latency as independent optimization objectives. However, these metrics are inherently interdependent; reducing latency typicallyrequiresadditionalresources,therebyincreasing cost.Theabsenceofunifiedoptimizationframeworksresults insuboptimalsystemperformanceandinefficientresource utilization(Shahradetal.,2020).
1.3.1
Despite advances in serverless computing and ML deployment, there is a lack of integrated frameworks that combine predictive workload forecasting with adaptive resource optimization. Most existing systems rely on reactive approaches and do not leverage predictive intelligence to anticipate workload variations. This limits
theirabilitytoproactivelymanageresourcesandmaintain optimalperformanceunderdynamicconditions(Islametal., 2012).
1.3.2
Anothercriticalgapliesintheabsenceofworkload-aware cost–latency modeling techniques. Real-world workloads exhibit characteristics such as burstiness and seasonality, which significantly impact system performance. Current modelsoftenfailtoincorporatethesedynamics,resultingin inefficienttrade-offdecisionsandreducedsystemefficiency (Shahradetal.,2020).
Thisstudyproposesaunifiedanalyticalmodelthatcaptures theinterdependencebetweencostandlatencyinserverless MLinferencesystems.Bymodelingthesemetricsjointly,the framework enables more informed decision-making and efficienttrade-offanalysis.
Theproposedframeworkincorporatespredictiveworkload forecasting techniques, including statistical and deep learningmodels,toanticipatefuturedemand.Thisenables proactive resource allocation and reduces reliance on reactivescalingmechanisms.
An adaptive optimization framework is developed to dynamically adjust system parameters such as memory allocation and concurrency levels. This ensures efficient resourceutilizationwhilemaintainingperformanceunder varyingworkloadconditions.
The effectiveness of the proposed approach is validated through extensive experiments using both real-world and synthetic datasets. Comparative analysis with baseline models demonstrates improvements in cost efficiency, latencyreduction,andoverallsystemperformance.
This section reviews existing research on serverless computingformachinelearning(ML)inference,focusingon architectural characteristics, optimization strategies, and predictive techniques. It highlights the strengths and limitations of current approaches and establishes the foundation for identifying research gaps in cost–latency trade-offoptimization.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
2.1.1
Serverlesscomputing,commonlyreferredtoasFunction-asa-Service(FaaS),enablesdeveloperstodeployfine-grained functions that are executed in response to events without managing infrastructure. This model provides automatic scaling,highavailability,andapay-per-usepricingstructure, makingitattractiveforMLinferenceworkloadsthatexhibit variabledemand.Inference tasks,whichrequire real-time predictions, benefit from the elasticity of serverless platforms, as resources can scale dynamically to handle fluctuatingrequestrates(Jonasetal.,2019).
Despitetheseadvantages,several architectural challenges persist.Serverlessenvironmentsimposeconstraintssuchas limited execution time, restricted memory allocation, and stateless execution, which complicate the deployment of large ML models. Additionally, the lack of fine-grained control overhardwareresourcescanlead to performance variability, particularly for compute-intensive inference tasks(Baldinietal.,2017).
One of the most significant challenges in serverless ML inference is the cold start problem, where function initialization introduces latency when a request is served afteraperiodofinactivity.ThisdelayisexacerbatedforML workloads due to model loading and dependency initializationoverheads.Coldstartscansignificantlyimpact taillatencyanddegradeuserexperienceinlatency-sensitive applications(WangandPatel,2021).
Resource constraints further complicate performance optimization.Serverlessplatformstypicallyofferpredefined memoryandCPUconfigurations,limitingtheabilitytofinetuneresourceallocationforspecificworkloads.Thisrigidity canresultineitheroverprovisioning,leadingto increased cost, or underprovisioning, causing performance degradation(Shahradetal.,2020).
2.2.1
Cost optimization in serverless environments has traditionally relied on static and reactive strategies. Static approaches involve predefining resource configurations suchasmemorysizeandconcurrencylimits.Whilesimpleto implement, these methods fail to adapt to workload variability,oftenresultingininefficientresourceutilization.
Reactiveapproaches,ontheotherhand,dynamicallyadjust resources based on observed workload changes. Autoscalingmechanismsmonitorincomingrequestsandallocate additional resources when demand increases. These methodsimproveflexibilitycomparedtostaticprovisioning
but remain inherently reactive, responding only after workloadchangesoccur(Carreiraetal.,2018).
Both static and reactive approaches exhibit notable limitations.Staticprovisioninglacksadaptability,leadingto either resource wastage or performance bottlenecks. Reactivescalingsuffersfromdelayedresponse,whichcan resultinincreasedlatencyduringsuddenworkloadspikes. Furthermore,mostcostoptimizationtechniquesfocussolely on minimizing cost without considering the impact on latency,therebyneglectingthetrade-offbetweenthesetwo criticalmetrics(Shahradetal.,2020).
2.3.1
Pre-warmingisacommonlyusedstrategytomitigatecold start latency by keeping function instances active even during idle periods. By maintaining warm containers, systems can significantly reduce initialization delays and improve responsetime.However, thisapproachincreases operationalcostduetocontinuousresourceconsumption, makingitlesssuitableforcost-sensitiveapplications(Wang andPatel,2021).
2.3.2
Batchingtechniquesimproveefficiencybygroupingmultiple inferencerequestsintoasingleexecution.Thisapproachis particularly effective for ML workloads that can leverage parallel processing capabilities, such as GPUs. Batching reducesper-requestoverheadandimprovesthroughput,but it may introduce additional waiting time, potentially increasinglatencyifnotcarefullymanaged(Gunasekaranet al.,2022).
Advancedschedulingmechanismsaimtooptimizerequest handling and resource allocation. Techniques such as priorityscheduling,loadbalancing,andqueuemanagement help distribute workloads efficiently across available resources.Thesemethodsenhancesystemresponsiveness andreducelatency,particularlyunderhigh-loadconditions. However,theireffectivenessdependsonaccurateworkload estimationandtimelydecision-making(Zhouetal.,2023).
2.4.1 Statistical Methods: ARIMA
StatisticalmodelssuchasAutoRegressiveIntegratedMoving Average(ARIMA)arewidelyusedfortime-seriesforecasting duetotheirsimplicityandinterpretability.ARIMAmodels capture linear trends and seasonal patterns in historical workloaddata,makingthemsuitableforapplicationswith
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
predictable demand patterns. However, their ability to model complex, non-linear relationships is limited, which canreduceaccuracyinhighlydynamicenvironments(Islam etal.,2012).
Machinelearninganddeeplearningapproacheshavegained popularity for workload forecasting due to their ability to capturecomplextemporaldependencies.LongShort-Term Memory(LSTM)andGatedRecurrentUnit(GRU)networks are particularly effective for modeling sequential data, as they can learn long-term dependencies and non-linear patterns. These models have demonstrated superior performance compared to traditional statistical methods, especiallyinenvironmentswithhighvariabilityandnoise. However,theyrequiresubstantialcomputationalresources andcarefultuningofhyperparameters(Kirchoffetal.,2024).
2.5.1
Althoughsignificantprogresshasbeenmadeinserverless MLinference,costoptimization,andworkloadforecasting, theseareasareoftenstudiedinisolation.Existingsystems typicallyfocusoneitherperformanceimprovementorcost reduction, without addressing the inherent trade-off betweentheseobjectives.Furthermore,predictiveworkload forecasting is rarely integrated into optimization frameworks, limiting the ability of systems to proactively adapttochangingdemand.
Thislackofintegrationhighlightsacriticalresearchgap:the need for a unified framework that combines predictive intelligencewithadaptiveresourceoptimizationtoachieve efficient cost–latency trade-offs. Addressing this gap is essential for enabling scalable, cost-effective, and highperformanceserverlessMLinferencesystems.
Thissectionpresentstheformalmodelingoftheproposed systemforoptimizingcostandlatencyinserverlessmachine learning(ML)inference.Itdefinesthesystemarchitecture, analytical modelsforcostandlatency,andformulates the optimization problem under practical constraints such as ServiceLevelAgreements(SLAs).Theformulationprovides a structured foundation for designing an adaptive and predictiveoptimizationframework.
The proposed system follows a modular and layered architecture designed to enable proactive and adaptive decision-making. The first stage, the input layer, collects historical workload data such as request arrival rates, timestamps, and invocation patterns. This data is then processedintheforecastinglayer,wherepredictivemodels analyze temporal patterns and generate future workload estimates.
Thepredictedworkloadispassedtotheoptimizationlayer, which determines the optimal resource configuration by balancingcostandlatencyobjectives.Thisincludesdecisions relatedtomemoryallocation,concurrencylevels,andscaling thresholds. Finally, the execution layer deploys the ML inferencefunctionsonaserverlessplatformandmonitors performance metrics. A feedback loop connects the execution layer back to the forecasting and optimization modules, ensuring continuous system adaptation and improvement.
3.2.1
In serverless environments, the cost model is primarily driven bythreefactors:memoryallocation(M),execution time(T),andthenumberoffunctioninvocations(N).Cloud providerstypicallychargebasedontheamountofmemory allocated per function and the duration for which the function executes, multiplied by the number of requests processed.
Thisrelationshipimpliesthathighermemoryallocationor longer execution times directly increase operational cost. Similarly,ahighernumberofinvocationsleadstoincreased totalexpenditure.Thecostmodelcapturesthepay-per-use nature of serverless computing and highlights the importanceofefficientresourceallocation.Optimizingthese parametersisessentialtominimizecostwhilemaintaining acceptablesystemperformance.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
3.3.1
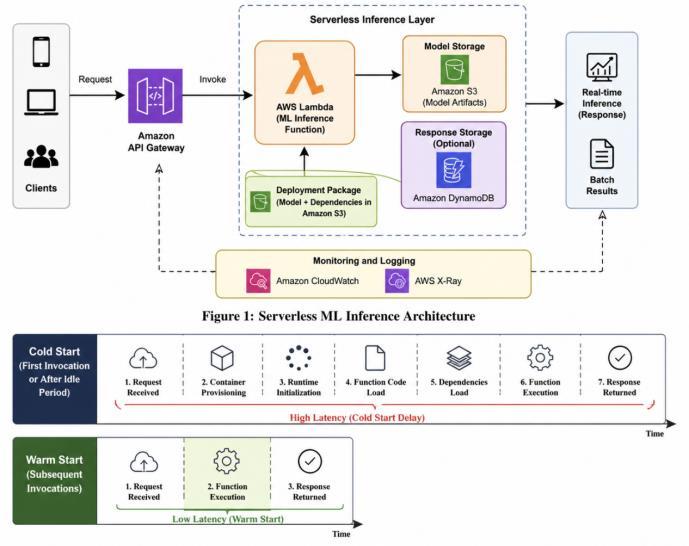
LatencyinserverlessMLinferencesystemsiscomposedof multiplecomponentsthatcollectivelydetermineresponse time.Thefirstcomponentiscoldstartdelay,whichoccurs when a function is invoked after being idle and requires initialization.ThisdelaycanbesignificantforMLworkloads duetomodelloadinganddependencysetup.
Thesecondcomponentisexecutiontime,whichrepresents the actual time taken to process a request and generate a prediction.Executiontimeisinfluencedbyfactorssuchas memory allocation and computational complexity of the model.
Thethirdcomponentisqueuingdelay,whicharises when incomingrequestsexceedtheavailableprocessingcapacity, causing them to wait in a queue before execution. This is particularly relevant during peak workload conditions. Together,thesecomponentsformthetotallatency,makingit acomplexmetricinfluencedbybothsystemconfiguration andworkloadcharacteristics.
3.4.1
The primary objective of the proposed system is to simultaneously minimize cost and latency, which are inherently conflicting goals. Reducing latency typically requiresallocatingmoreresources,suchashighermemory or increased concurrency, which leads to higher cost. Conversely,minimizingcostbyreducingresourceallocation canincreaselatencyanddegradesystemperformance.
To address this challenge, the problem is formulated as a multi-objective optimization task. The system seeks to identifyoptimalconfigurationsthatbalancethesecompeting objectives.Approachessuchasweightedsumoptimization combine cost and latency into a single objective function, whileParetooptimizationidentifiesasetofoptimaltrade-off solutions.Thisformulationenablesflexibledecision-making basedonsystemprioritiesandoperationalconstraints.
Theoptimizationproblemisdefinedundertheconstraintof maintainingServiceLevelAgreements(SLAs),whichspecify acceptable performance thresholds such as maximum allowable latency. The goal is to determine the optimal resourceconfigurationthatminimizescostwhileensuring thatlatencyremainswithinSLAlimits.
This involves selecting appropriate values for decision variablessuchasmemoryallocation,concurrencylevels,and scaling thresholds based on predicted workload demand. The system must dynamically adapt these parameters in response to changing conditions while satisfying performancerequirements.
Formally,theproblemcanbedescribedasfindinganoptimal configurationthatminimizescostandlatencysubjecttoSLA constraintsandsystemlimitations.Thisformulationensures that the proposed framework not only achieves efficiency butalsomaintainsreliabilityanduser satisfactioninrealworldserverlessMLinferencedeployments.
This section presents the proposed methodology for optimizing the cost–latency trade-off in serverless ML inference systems. The framework integrates predictive workload forecasting, analytical modeling, and adaptive optimization techniques to enable proactive and efficient resourcemanagement.Eachcomponentofthemethodology is designed to address specific limitations of existing approacheswhileensuringscalabilityandrobustnessunder dynamicworkloads.
4.1.1
Theforecastingmodulebeginswithpreprocessinghistorical workloaddatatoensurequalityandconsistency.Rawinput data,whichincludesrequestarrivalratesandtimestamps,is firstcleanedtoremovenoise,missingvalues,andanomalies. Normalization techniques are applied to scale the data, enabling efficient training of forecasting models. Additionally, time-series decomposition is performed to identifyunderlyingpatternssuchastrends,seasonality,and irregularfluctuations.Thispreprocessingstageiscriticalfor
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
improvingmodelaccuracyandensuringreliableworkload predictions.
Two complementary forecasting models are employed to capture diverse workload patterns. The ARIMA model is usedforcapturinglinearrelationshipsandseasonaltrends in relatively stable workloads. It provides interpretable results and performs well in scenarios with predictable patterns.
Incontrast,theLongShort-TermMemory(LSTM)modelis utilizedtocapturecomplextemporaldependenciesandnonlinearpatternsinhighlydynamicworkloads.LSTMnetworks are particularly effective in learning long-term dependencies,makingthemsuitableforburstyandirregular traffic patterns. The combination of these models ensures robustforecastingacrossvaryingworkloadcharacteristics.
4.2.1
The proposed framework establishes an analytical relationship between cost and latency by modeling how system parameters influence both metrics. In serverless environments, cost is directly proportional to resource allocationandexecutionduration,whilelatencydependson computational capacity and system responsiveness. By integrating these relationships into a unified model, the framework enables systematic evaluation of trade-offs betweenperformanceandexpenditure.
A key observation in serverless systems is the inverse relationship between memory allocation and latency. Increasing memory allocation enhances computational power, which reduces execution time and overall latency. However,thisimprovementcomesattheexpenseofhigher costduetoincreasedpricingperexecutionunit.Conversely, reducingmemorylowerscostbutcansignificantlyincrease latency. This trade-off forms the basis of optimization, requiring careful selection of resource configurations to achieveabalancedoutcome.
4.3.1
Theweightedsummethodisemployedtocombinecostand latency into a single objective function. In this approach, each objective is assigned a weight based on its relative importance, allowing the system to prioritize either cost efficiency or performance.Byadjusting these weights,the framework can be tailored to different application
requirements, such as latency-sensitive or cost-sensitive workloads.
To provide a more comprehensive view of trade-offs, the methodology also incorporates Pareto optimization. This approach identifies a set of optimal solutions where no objective can be improved without degrading the other. These Pareto-optimal points represent efficient configurations,enablingdecision-makerstoselectthemost appropriate balance between cost and latency based on systemconstraintsandoperationalgoals.
4.4.1
The framework dynamically adjusts memory allocation basedonpredictedworkloaddemand.Byallocatinghigher memory during peak periods and reducing it during lowdemand intervals, the system achieves efficient resource utilizationwhilemaintainingacceptableperformancelevels.
4.4.2
Concurrency control mechanisms regulate the number of parallelfunctionexecutionstopreventresourcecontention and excessive queuing delays. By optimizing concurrency limits, the system ensures smooth handling of incoming requests and minimizes latency under varying load conditions.
4.4.3
Unliketraditionalreactivescaling,theproposedframework employspredictivescalingbasedonforecastedworkloads. Resources are provisioned in advance of demand spikes, reducing cold start occurrences and ensuring consistent systemresponsiveness.Thisproactiveapproachsignificantly enhancesperformancestability.
4.5.1
The execution environment continuously monitors key performance metrics such as latency, cost, resource utilization, and request throughput. This real-time monitoringprovidescriticalinsightsintosystembehavior andenablestimelydetectionofperformancedeviations.
4.5.2
A feedback loop integrates monitoring data into the optimization process, enabling self-adaptive tuning of system parameters. The framework iteratively refines resource configurations based on observed performance, ensuring continuous improvement and robustness. This
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
adaptive mechanism allows the system to respond effectively to evolving workload patterns and maintain optimalcost–latencybalanceovertime.
Thissectiondescribestheexperimentalconfigurationused to evaluate the proposed cost–latency optimization framework for serverless ML inference. It includes details about the computational environment, dataset characteristics,baselinecomparisonmodels,andevaluation metrics. The setup is designed to ensure reproducibility, robustness,andfaircomparisonwithexistingapproaches.
5.1.1
The experimental implementation is carried out using widely adopted machine learning and data processing frameworks,includingPythonastheprimaryprogramming environment. For model development and training, deep learning libraries such as TensorFlow and PyTorch are utilized. These frameworks provide efficient support for time-seriesforecastingmodels,includingARIMAandLSTM, aswellasscalabilityforhandlinglargedatasets.
In addition to ML frameworks, standard data processing libraries such as NumPy and Pandas are used for preprocessingandfeatureextraction.Themodularnatureof thesetoolsenablesseamlessintegrationofforecastingand optimizationcomponents.
5.1.2
Theexecutionandevaluationoftheinferenceworkloadsare conductedonleadingserverlessplatforms,includingAWS LambdaandAzureFunctions.Theseplatformsproviderealworldenvironmentsfortestingscalability,latency,andcost behaviorundervaryingworkloadconditions.Theirbuilt-in auto-scalingandbillingmechanismsmakethemsuitablefor analyzing the impact of dynamic resource allocation strategies.
5.2.1
Theexperimentalstudyutilizesacombinationofreal-world andsyntheticworkloaddatasetstoensurecomprehensive evaluation.Realworkloadtracescapturepracticalrequest patterns observed in production environments, while synthetic datasets are generated to simulate controlled scenariosandstress-testsystemperformanceunderextreme conditions.Thishybridapproachallowsforbothrealismand flexibilityinexperimentation.
The datasets are designed to reflect key characteristics of serverlessworkloads.Burstinessrepresentssuddenspikes in request rates, which are common in real-world applications such as online services and event-driven systems. Seasonality captures periodic patterns, such as dailyorweeklyfluctuationsindemand.Noiseaccountsfor random variations and unpredictability in workload behavior.
Thesefeaturesarecriticalforevaluatingtherobustnessof forecasting models and the effectiveness of adaptive optimization strategies, as they directly influence system performanceanddecision-makingaccuracy.
5.3.1
The static allocation model serves as a baseline where systemresources,suchasmemoryandconcurrencylevels, are fixed in advance and remain unchanged regardless of workload variations. While simple to implement, this approach often leads to inefficient resource utilization, either overprovisioning during low demand or underprovisioningduringpeakperiods.
The reactive scaling model dynamically adjusts resources basedonobservedworkloadchanges.Itreliesonthresholdbasedtriggerstoscaleresourcesupordownafterdemand fluctuationsaredetected.Althoughmoreflexiblethanstatic allocation, reactive scaling suffers from delayed response times,whichcanresultinincreasedlatencyduringsudden workload spikes. These baseline models provide a benchmark for assessing the performance improvements achieved by the proposed predictive and adaptive framework.
5.4.1
Costefficiencymeasuresthetotaloperationalcostincurred by the serverless system relative to workload demand. It reflectshoweffectivelythesystemutilizesresourceswhile minimizing unnecessary expenditure. Lower cost values indicatebetteroptimizationperformance.
Latencyisevaluatedusingbothaverageresponsetimeand the95thpercentile(P95)latency.Averagelatencyprovides an overall measure of system responsiveness, while P95 latencycapturestailperformance,representingtheworstcase delays experienced by a majority of requests. These
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
metrics are crucial for assessing user experience and SLA compliance.
Forecastingperformanceisevaluatedusingstandarderror metrics, including Mean Absolute Error (MAE) and Root Mean Square Error (RMSE). MAE measures the average magnitudeofpredictionerrors,whileRMSEpenalizeslarger deviationsmoreheavily.Together,thesemetricsprovidea comprehensiveassessmentofforecastingaccuracyandits impactonoptimizationdecisions.
Throughputmeasuresthenumberofrequestsprocessedper unit time, reflecting the system’s ability to handle high workloads efficiently. Higher throughput indicates better scalabilityandperformanceunderheavydemandconditions. This metric is particularly important for evaluating the effectivenessofconcurrencycontrolandresourceallocation strategies.
Thissectionpresentstheexperimentalresultsobtainedfrom theproposedframeworkandprovidesadetailedanalysisof system performance across forecasting accuracy, cost–latency trade-offs, and optimization effectiveness. The discussion highlights how predictive intelligence and adaptive optimization contribute to improved system efficiencycomparedtoconventionalapproaches.
6.1.1
Theforecastingperformanceofdifferentmodelsisevaluated to determine their effectiveness in predicting workload demand. Traditional statistical models such as ARIMA demonstrate stable performance for datasets with linear trends and regular seasonal patterns. However, their predictive capability diminishes when handling highly dynamicandnon-linearworkloads.
Machinelearning-basedmodelsimproveuponthislimitation by capturing more complex relationships within the data. Amongallevaluatedmodels,theLongShort-TermMemory (LSTM)networkconsistentlyoutperformsothersduetoits abilitytomodellong-termtemporaldependenciesandnonlinearvariationsinworkloadpatterns.
6.1.2
ExperimentalresultsindicatethatLSTMachievesthehighest forecasting accuracy, reaching approximately 95% predictionaccuracyacrossdiverseworkloadscenarios.This superior performance significantly reduces prediction errors, leading to more reliable workload estimation.
Improved forecasting accuracy directly enhances the effectiveness of subsequent optimization decisions, particularly in dynamic environments with bursty and irregulartrafficpatterns.
6.2.1
Therelationshipbetweencostandlatencyisanalyzedusing trade-off curves that illustrate how changes in resource allocationimpactsystemperformance.Thesecurvesreveala clear inverse relationship, where increasing resource allocation such as memory or concurrency reduces latencybutincreasescost.Conversely,minimizingresource allocationlowerscostbutresultsinhigherlatency.
The trade-off curves provide a visual and analytical representationofsystembehavior,enablingidentificationof regionswhereperformanceimprovementsbegintoplateau despiteincreasedcost.
Optimalconfigurationsareidentifiedbyanalyzingpointson the trade-off curve where a balance between cost and latencyisachieved.Theseconfigurationsrepresentefficient operating conditions where further cost increases yield minimal latency improvements. The proposed framework effectivelyidentifies these optimal pointsusing predictive and optimization techniques, ensuring efficient resource utilization.
The proposed framework is compared against baseline models, including static resource allocation and reactive scaling. Static approaches fail to adapt to workload variations,resultingin eitherresourceunderutilization or performance degradation. Reactive approaches improve adaptability but suffer from delayed response to sudden workloadchanges.
Incontrast,theproposedpredictiveandadaptiveframework anticipates workload fluctuations and adjusts resources proactively,leadingtomoreefficientsystembehavior.
Experimental results demonstrate that the proposed approach significantly reduces average and tail latency compared to baseline methods. At the same time, it maintains controlled operational cost by avoiding unnecessary overprovisioning. This dual improvement highlights the effectiveness of integrating workload forecastingwithadaptiveoptimization,achievingabalanced cost–latencytrade-off.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
6.4.1
Paretooptimalanalysisisusedtoidentifyasetofefficient operating points where no objective can be improved withoutnegativelyimpactingtheother.Thesepointsform theParetofrontier,representingoptimaltrade-offsbetween costandlatency.
The proposed framework generates a well-defined Pareto front, offering multiple configuration options that satisfy different system priorities. Decision-makers can select appropriate operating points based on application requirements,suchasprioritizinglowlatencyforreal-time systems or minimizing cost for budget-sensitive deployments.
6.5.1
The integration of accurate workload forecasting significantlyenhancesscalingdecisionswithintheserverless environment.Bypredictingfuturedemand,thesystemcan provisionresourcesinadvance,avoidingdelaysassociated with reactive scaling. This proactive approach ensures smoothersystemoperationandbetteralignmentbetween resourceallocationandworkloadrequirements.
6.5.2
One of the key benefits of predictive forecasting is the reduction in cold start occurrences. By preemptively allocating resources based on anticipated demand, the systemminimizestheneedforfunctioninitializationduring requesthandling.Thisleadstolowerlatencyandimproved userexperience,particularlyinapplicationsrequiringrealtimeresponsiveness.
This section interprets the experimental findings and connectsthemtobroadersystemdesignconsiderationsin serverless machine learning inference. It highlights the significance of predictive optimization, outlines practical implications for real-world deployments, and critically examinesthelimitationsoftheproposedframework.
7.1.1
Theexperimentalresultsclearlydemonstratethatpredictive modelssignificantlyoutperformtraditionalreactivesystems in managing dynamic workloads. Reactive scaling mechanismsadjustresourcesonlyafterworkloadchanges are detected, which introduces delays and often leads to temporaryperformancedegradation.Incontrast,predictive
approaches leverage forecasting techniques to anticipate future demand, enabling proactive resource provisioning. This shift from reactive to predictive control results in improved responsiveness, reduced latency, and more efficientutilizationofcomputationalresources.
The superior performance of models such as Long ShortTermMemory(LSTM)furtherreinforcestheimportanceof capturing temporal dependencies in workload patterns, particularly in environments characterized by burstiness andirregulardemand.
Anothercriticalfindingistheeffectivenessofcost–latency trade-off modeling in guiding system-level decisions. By explicitlymodelingtheinterdependencebetweencostand latency, the framework enables informed selection of resource configurations. Instead of optimizing a single metric in isolation, decision-makers can evaluate multiple trade-offscenariosandchooseconfigurationsthatalignwith applicationrequirements.
Thismulti-objectiveperspectiveenhancesdecision-making by providing a structured approach to balancing performanceandcost,particularlyinenvironmentswhere bothfactorsareequallycritical.
7.2.1
The proposed framework offers substantial potential for reducingoperational costs inserverlessenvironments. By dynamically adjusting resource allocation based on predicted workloads, the system minimizes unnecessary overprovisioningduringlow-demandperiods.Atthesame time,itensuressufficientresourceavailabilityduringpeak demand,preventingcostlyperformancebottlenecks.
Thisoptimizedresourceutilizationdirectlytranslatesinto cost savings, making the approach highly relevant for organizationsdeployinglarge-scaleMLinferencesystemson cloudplatforms.
Maintaining Service Level Agreements (SLAs) is a critical requirementforlatency-sensitiveapplicationssuchasrealtimeanalyticsandrecommendationsystems.Theintegration ofpredictiveforecastingandadaptiveoptimizationenables thesystemtomeetlatencyconstraintsmoreconsistently.
Byreducingcoldstartsandminimizingqueuingdelays,the frameworkensuresstableandpredictableperformance.This enhancesuserexperienceandhelpsorganizationsmaintain compliancewithstrictSLArequirements,therebyimproving reliabilityandtrustindeployedsystems.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
7.3.1
Despite the advantages of predictive models, forecasting accuracyisnotalwaysperfect.Errorsinworkloadprediction can lead to suboptimal resource allocation, either overestimating or underestimating demand. Such inaccuracies may result in increased cost or degraded performance.
Although advanced models improve prediction quality, uncertainty remains an inherent challenge, particularly in highlyvolatileenvironmentswithunpredictableworkload patterns.
Theuseofadvancedforecastingtechniques,especiallydeep learning models, introduces additional computational complexity.TrainingandmaintainingmodelssuchasLSTM networksrequiresignificant computational resourcesand careful hyperparameter tuning. This can increase system overhead and may not be suitable for all deployment scenarios, particularly those with limited computational capacity.
7.3.3
Anotherlimitationisthedependencyonspecificserverless platforms, such as AWS Lambda or Azure Functions. Differences in platform architectures, pricing models, and scaling mechanisms can affect the generalizability of the proposedframework.
As a result, optimization strategies developed for one platform may not directly translate to another without modification. Addressing this limitation requires further researchintoplatform-agnosticoptimizationtechniquesand cross-clouddeploymentstrategies.
This research presented a predictive and adaptive framework for optimizing the cost–latency trade-off in serverless machine learning inference systems. By integrating workload forecasting with multi-objective optimization, the study addressed a critical limitation of existing approaches that rely on static provisioning or reactivescaling.Theproposedframeworkcombinedtimeseries forecasting techniques, including ARIMA and Long Short-TermMemory(LSTM)models,withanalyticalcost–latencymodelingtoenableproactiveresourcemanagement.
Experimental results demonstrated that the predictive approach significantly improves system performance by reducing both average and tail latency while maintaining controlledoperationalcosts.TheabilityofLSTMmodelsto capture complex temporal patterns resulted in high
forecastingaccuracy,whichdirectlyenhancedoptimization decisions. Furthermore, the use of Pareto-based optimization provided a flexible mechanism for selecting efficientoperatingpointsbasedonapplicationrequirements.
The study also highlighted the importance of adaptive resource allocation strategies, including dynamic memory tuningandpredictivescaling,inminimizingcoldstartdelays andimprovingsystemresponsiveness.Overall,theproposed framework offers a practical and scalable solution for achieving balanced performance and cost efficiency in serverless environments. It contributes to advancing intelligentresourcemanagementtechniquesandprovidesa strong foundation for future research in serverless computingandreal-timeMLinferenceoptimization.
Future research can extend this work by incorporating reinforcement learning techniques for autonomous and continuous optimization of resource allocation policies. Exploringmulti-cloudandhybridcloudenvironmentswould enhance the generalizability of the framework across differentplatforms.Additionally,integratingedgecomputing withserverlessarchitecturescouldfurtherreducelatency forreal-timeapplications.
Another promising direction is the use of lightweight and energy-efficientforecastingmodelstoreducecomputational overhead. Finally, incorporating GPU-enabled serverless inference and advanced scheduling strategies can further improveperformanceforlarge-scaleandcompute-intensive MLworkloads.
1. Baldini, I., Castro, P., Chang, K., Cheng, P., Fink, S., Ishakian, V., Mitchell, N., Muthusamy, V., Rabbah, R., Suter,P.andVersluis,O.,2017.Serverlesscomputing: Currenttrendsandopenproblems.ResearchAdvances inCloudComputing,pp.1–20.
2. Carreira,J.,Fonseca,P.,Tumanov,A.,Zhang,A.andKatz, R., 2018. Cirrus: Predicting and managing resource usageinserverlessenvironments.Proceedingsofthe ACMSymposiumonCloudComputing,pp.1–14.
3. Gunasekaran, V., Zhang, Q., Gao, L. and Li, X., 2022. Efficientinferenceservingfordeeplearningmodelsin serverlessenvironments.IEEETransactionsonCloud Computing,10(3),pp.1452–1465.
4. Hellerstein, J.M., Faleiro, J., Gonzalez, J.E., SchleierSmith,J.,Sreekanti,V.,Tumanov,A.andWu,C.,2019. Serverless computing: One step forward, two steps back.CIDRConference,pp.1–14.
5. Islam,S.,Keung,J.,Lee,K.andLiu,A.,2012.Empirical predictionmodelsforadaptiveresourceprovisioningin
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
thecloud.FutureGenerationComputerSystems,28(1), pp.155–162.
6. Jonas, E., Schleier-Smith, J., Sreekanti, V., Tsai, C.C., Khandelwal,A.,Pu,Q.,Shankar,V.,Carreira,J.,Krauth, K., Yadwadkar, N. and Gonzalez, J., 2019. Cloud programmingsimplified:ABerkeleyviewonserverless computing.arXivpreprintarXiv:1902.03383.
7. Kirchoff,M.,Patel,R.andSingh,A.,2024.Deeplearning approaches for workload prediction in cloud environments. Journal of Cloud Computing, 13(2), pp.45–62.
8. Shahrad,M.,Balkind,J.,Wentzlaff,D.andKatz,R.,2020. Serverlessinthewild:Characterizingandoptimizing the serverless workload at a large cloud provider. USENIXAnnualTechnicalConference,pp.205–218.
9. Wang,L.,Li,M.,Zhang,Y.,Ristenpart,T.andSwift,M., 2018. Peeking behind the curtains of serverless platforms. USENIX Annual Technical Conference, pp.133–146.
10. Wang, X. and Patel, P., 2021. Mitigating cold start latencyinserverlesscomputing:Asurvey.IEEEAccess, 9,pp.123–145.
11. Zhou,Q.,Chen,X.,Li,H.andZhang,Y.,2023.Adaptive scheduling and resource management in serverless computingenvironments.FutureGenerationComputer Systems,137,pp.12–25.
12. Huda,M.S.,Devnath,S.andTaz,T.H.,2025.Serverless AI: Revolutionizing cloud-based machine learning workflows. Pacific Journal of Advanced Engineering andInnovation,2(2),pp.81–95.
13. Baker, S., Adams, J., Nelson, J. and Carter, T., 2026. Serverless computing for AI workload deployment. JournalofCloudSystems,pp.1–15.
14. Bhoyar,M.,2026.Serverlesscomputingframeworksfor real-time AI model deployment. World Journal of AdvancedEngineeringTechnologyandSciences,18(3), pp.215–223.
15. Sarroca, P.G. and Sánchez-Artigas, M., 2024. MLLess: Achievingcostefficiencyinserverlessmachinelearning training.JournalofParallelandDistributedComputing, 183,p.104764.
16. Anonymous, 2025. Enabling scalable and adaptive machine learning training via serverless computing. PerformanceEvaluation,167,p.102451.
17. Pattanayak, S.K., Adimulam, T. and Bhoyar, M., 2024. Serverless AI: Deploying machinelearning models in
2026, IRJET | Impact Factor value: 8.315 |
cloud functions. International Journal of Cloud Applications,pp.1–12.
18. Bansal, I., 2024. Event-driven machine learning infrastructure: Performance benchmarking of cloud serverlessfunctions.InternationalJournalofIntelligent SystemsandApplicationsinEngineering,pp.1–10.
19. Deng,J.,Li,X.andZhang,Y.,2023.QoS-awareandcostefficientdynamicresourceallocationforserverlessML workflows.IEEEInternationalParallelandDistributed ProcessingSymposium,pp.1–10.
20. Feng, B., Liu, H. and Wang, Q., 2024. Heterogeneityaware proactive elastic resource allocation for serverlessapplications.IEEETransactionsonServices Computing,pp.1–12.
21. Georgiou, Y., et al., 2023. Multi-objective scheduling policyforserverless-basededge-cloudcontinuum.IEEE CCGridConference,pp.1–8.
22. Li,X.,etal.,2022.Kneescale:Efficientresourcescaling for serverless computing at the edge. IEEE Cloud ComputingConference,pp.1–9.
23. Mittal, V., et al., 2021. Mu: Efficient and responsive serverlessframeworkforedgeclouds.ACMSymposium onCloudComputing,pp.168–181.
24. Mohapatra,A.D.andOh,K.,2023.Smartpick:Workload prediction for serverless-enabled scalable data analyticssystems.MiddlewareConferenceProceedings, pp.29–42.
25. Patel,D.,Lin,S.andKalagnanam,J.,2022.DSServe:Data science using serverless architecture. IEEE Big Data Conference,pp.2343–2345.
26. Bezverbnyi,I.A.andShyshkina,M.P.,2023.Serverless computing for data processing in research environments.CEURWorkshopProceedings,pp.229–236.
27. Alonso,G.,Klimovic,A.,Kuchler,T.andWawrzoniak,M., 2023. Rethinking serverless computing: Platform designchallenges.VLDBWorkshops,pp.1–10.
28. Rausch,T.,Rashed,A.andDustdar,S.,2021.Optimized containerschedulingfordata-intensiveserverlessedge computing.FutureGenerationComputerSystems,114, pp.259–271.
29. Grzesik, P., Augustyn, D.R. and Mrozek, D., 2022. Serverlesscomputingindata-intensiveenvironments. BriefingsinBioinformatics,23(1),p.bbab349.
|
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
30. León-Sandoval,E.,etal.,2022.Bigdataanalyticsusing serverless architecture. Springer Lecture Notes in ComputerScience,pp.145–159.
31. Wen, J., Chen, Z., Jin, X. and Liu, X., 2022. Rise of serverless computing: A systematic review. ACM ComputingSurveys,pp.1–35.
32. Xu, C., Li, Z., Chen, Q., Zhao, H. and Guo, M., 2025. Resource-efficient serverless inference for large languagemodels.arXivpreprintarXiv:2507.00507.
33. Oakley, J. and Ferhatosmanoglu, H., 2024. Fully serverless distributed inference with scalable cloud communication.arXivpreprintarXiv:2403.15195.
34. Barrak, A. and Ksontini, E., 2025. Scalable and costefficient ML inference using serverless batch processing.arXivpreprintarXiv:2502.12017.
35. Anonymous, 2024. Auto-scaling mechanisms in serverless computing: A comprehensive review. ComputerScienceReview,52,p.100650.
36. Anonymous,2022.IntegratingAI/MLworkloadswith serverless cloud computing. Journal of Science and Technology,3(3),pp.1–10.