
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 01 | Jan 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 01 | Jan 2026 www.irjet.net p-ISSN: 2395-0072
A.
Dhanush1 , G. Amulya2 , D. Madhu3, S. Jakeerhussen4 , Madhumathi Thakur5
1234Department of Information Technology, TKR College of Engineering and Technology, Telangana, India 5 Assistant Professor, dept. of Information Technology ***
Abstract - While contemporary assistive technologies have made strides inbridging the gap betweensignlanguage users and the hearing world, most systems are strictly scoped to a single national sign language. This narrow focus overlooks a critical, oftenneglectedcommunication barrier:the linguistic divide among sign language users of different nationalities andethnicities. As signlanguages like IndianSignLanguage (ISL), American Sign Language (ASL), and Russian Sign Language (RSL) are distinct and mutually unintelligible, there is a pressing need for a unified environment that facilitates cross-lingual interaction. This project presents a proof-of-concept for an integratedsignlanguagetranslation system designed to bridge this multi-ethnic divide. Unlike conventional models, this system incorporates a multi-lingual framework featuring ISL, ASL, and RSL within a single interface. By providing a platform where diverse sign languages are recognized and translated into a common medium, the project demonstrates that technology can facilitate direct communication between sign language users from different parts of the world.
KeyWords:Proof-of-Concept,Cross-lingual communication, Indian Sign Language (ISL), American Sign Language (ASL), Russian Sign Language (RSL), Linguistic Diversity, Communication Barriers, Inclusive Design, Multi-ethnic Systems.
Communication is the fundamental bridge that connects individuals,yetforthedeafandhard-of-hearingcommunity, this bridge is often broken by the language barrier. Sign languageistheprimarymodeofcommunicationformillions of people worldwide, but the vast majority of the hearing population remains unfamiliar with it. This creates a significantgapinsocialinclusion,andinvolvementwiththe largerpopulation.
While there have been advancements in sign language recognition, most existing solutions focus on a single language,typicallyAmericanSignLanguage(ASL).However, signlanguagesarenotuniversal;theyvarysignificantlyby region.Forinstance,IndianSignLanguage(ISL)usestwohanded gestures for many alphabets, whereas ASL is predominantlysingle-handed.RussianSignLanguage(RSL) hasitsownuniquesyntaxandgestures.
Thisproject,the Multilingual Sign Language Recognizer, addresses this limitation by developing a deep learningbased system capable of interpreting gestures from three distinct sign languages: ASL, ISL, and RSL. By leveraging computervisionandneuralnetworks,thissystemtranslates hand gestures into text in real-time, facilitating smoother communicationacrossdifferentlinguisticregions.
Theprimaryobjectiveistodevelopamultilingualsystemby creating a unified platform that supports multiple sign languages (ASL, ISL, and RSL) within a single interface, thereby removing the need for separate applications for different regions. The project aims to implement real-time hand tracking using a robust mechanism based on Media Pipe, capable of detecting hand landmarks with high precision even in varying lighting conditions and backgrounds. Additionally, the system focuses on accurate classification by training and deploying specialized Convolutional Neural Network (CNN) models for each languagetoclassifystatichandgestures,suchasalphabets andnumbers,intotheircorrespondingtextoutput.Finally, the goal is to provide a user-friendly interface through a simple,intuitiveGraphicalUserInterface(GUI)thatallows users to easily switch between languages and view the translatedtextinstantly.
Theproblemofcommunicationbetweenthehearingandthe hearing-impaired communities is a significant societal challenge. A primary issue is the language barrier, as the majorityofthehearingpopulationdoesnotunderstandsign language,leadingtosocialisolationforthedeafcommunity. Furthermore,fragmentationincurrenttechnologyisevident, asexistingautomatedsolutionsfocusalmostexclusivelyon AmericanSignLanguage(ASL),resultinginadistinctlackof accessibletoolsforIndianSignLanguage(ISL)andRussian Sign Language (RSL). Technical limitations also hinder progress; many traditional recognition systems rely on intrusive or expensive equipment like colored gloves or depth sensors (such as Kinect). Consequently, there is a critical need for a solution that operates on standard consumer hardware, specifically webcams, without extra equipment.
Lastly,scalabilityposesaproblem,ascurrentsystemsoften struggle to accommodate multiple languages due to the
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 01 | Jan 2026 www.irjet.net p-ISSN: 2395-0072
complexityofmanagingdifferentgesturesetssuchassinglehanded versus double-handed signs, within a single architecture.
Theproposed Multilingual Sign Language Recognizer isa comprehensive software solution that uses a standard webcamtorecognizegesturesfromASL,ISL,andRSL. Thesystemcapturesvideoframes,processesthemtoisolate the hands, and uses a specialized Deep Learning model to predictthegesture.Itemploys MediaPipe forefficienthand tracking,ensuringthatthebackgroundisignoredandonly the hand geometry is analyzed. The system includes a language selector, allowing the user to switch models dynamically.
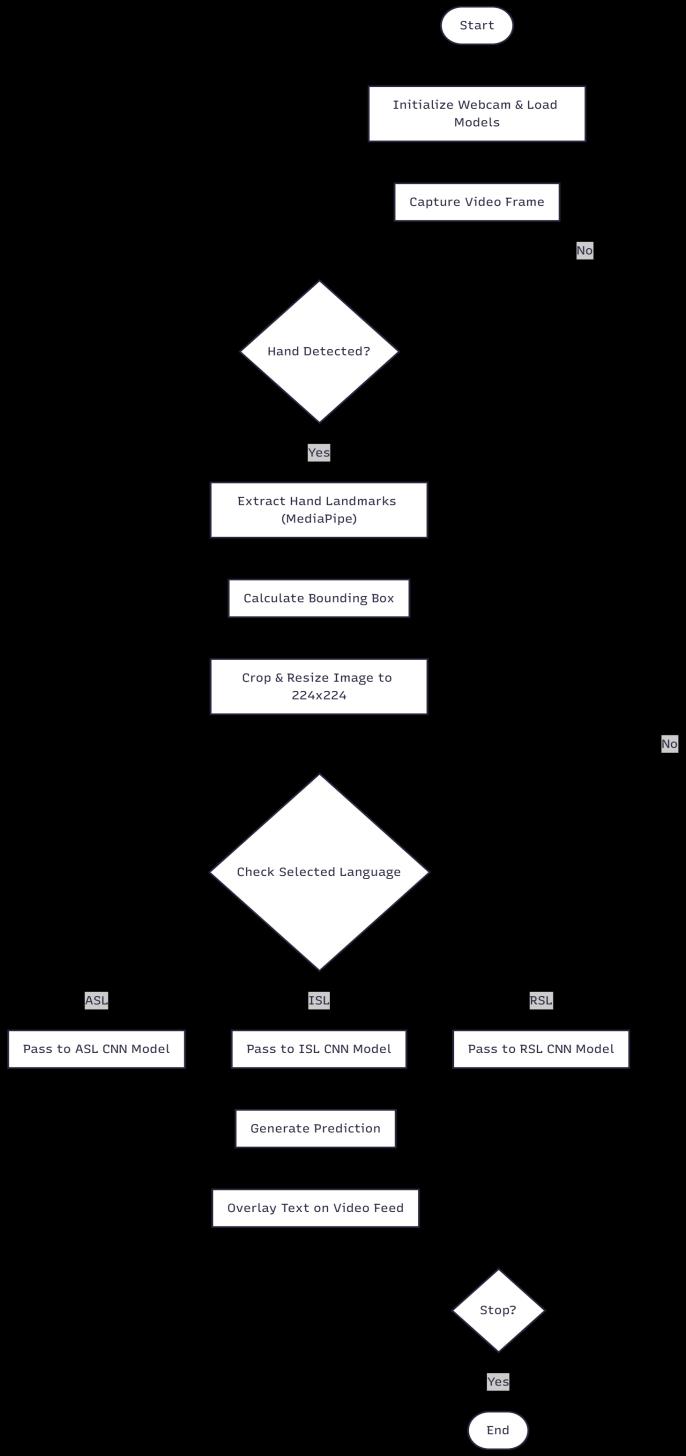
The proposed system functions as a continuous, real-time processingloopthatbeginsbyinitializingthewebcamand loadingdedicateddeeplearningmodelsforAmerican,Indian, and Russian Sign Languages. Once operational, thesystem capturesindividualvideoframesandchecksforthepresence of a hand; if a hand is detected, the architecture utilizes MediaPipetoextractspecificlandmarks,whicharethenused todefineaboundingboxandcroptheregionofinterestintoa standardized224x224pixelimage.Thispreprocessedinput is subsequently routed to a specific Convolutional Neural Network(CNN)correspondingtotheuser’sselectedlanguage toensureaccurateclassification.Theresultingpredictionis immediately generated and overlaid as text onto the live videofeed,providinginstanttranslationbeforethesystem loopsbacktoprocessthenextframeorterminatesupona stopsignal.
The core intelligence of the system relies on specialized Convolutional Neural Networks (CNN) trained for each language. The architecture is designed with a specific sequence of layers to optimize feature extraction and
classification.ItbeginswithConvolutionalLayers(Conv2D) toextractspatialfeaturesfromthehandimages,followedby Pooling Layers (MaxPooling2D) that reduce the dimensionalityofthefeaturemapsandcomputationalload. ThesearesucceededbyFlattenlayersthatconvertthe2D arraysinto1Dvector,whicharethenpassedthroughfully connected Dense layers for classification. To ensure the modelgeneralizeswelltonew,unseengestures,aDropout layer of 0.5 is included to prevent overfitting during the trainingphase
Sample paragraph Define abbreviations and acronyms the firsttimetheyareusedinthetext,evenaftertheyhavebeen definedintheabstract.AbbreviationssuchasIEEE,SI,MKS, CGS,sc, dc,and rms do nothave to be defined. Do not use abbreviations in the title or heads unless they are unavoidable.
Afterthetextedithasbeencompleted,thepaperisreadyfor thetemplate.DuplicatethetemplatefilebyusingtheSaveAs commandandusethenamingconventionprescribedbyyour conferenceforthenameofyourpaper.Inthisnewlycreated file,highlightall ofthecontentsandimportyourprepared textfile.Youarenowreadytostyleyourpaper.
Therecognitionprocessbeginswhenthewebcamcapturesa frame. Upon system startup, the Initialization Phase triggersthewebcamandloadsthepre-trainedConvolutional Neural Network (CNN) models for ASL, ISL, and RSL into memory. The system then enters its main execution loop, whereitcapturesarawvideoframe.
For every frame, a conditional check is performed to determine if a hand is present. If the hand detection algorithm (powered by Media Pipe) returns a negative result, the system discards the frame and loops back to capture the next one. However, if a hand is detected, the landmark extraction process begins,identifyingkeypoints on the hand to calculate a bounding box. This Region of Interest (ROI) is then cropped and resized to a standard 224x224pixelformattomatchtheinputlayerrequirements oftheCNNs.
Acriticalroutingstepfollows,wherethesystemchecksthe user'scurrentlyselectedlanguage.Basedonthisselection, thepre-processedimageisroutedtothespecificmodel(e.g., passing to the ASL CNN Model or RSL CNN Model). The selected model generates a prediction index, which is mappedtoacharacterlabel.Finally,thistextisoverlaidonto the live video feed, providing instant feedback. The loop continuesuntila"Stop"signalisreceived,atwhichpointthe resourcesarereleasedandtheprogramterminates.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 01 | Jan 2026 www.irjet.net p-ISSN: 2395-0072
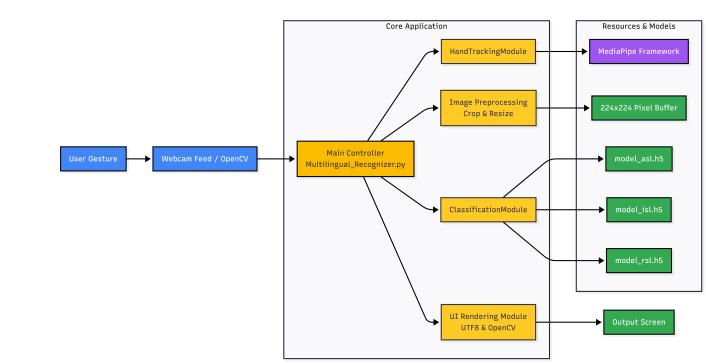
Theimplementationoftheproposedmultilingualsystemis carriedoutusingacombinationofPython,ComputerVision libraries, and Deep Learning frameworks. The implementation is divided into three main modules: Data Collection,ModelTraining,andReal-TimeRecognition.
Tracking layer is implemented using Google's Media Pipe framework.Specifically,theHandTrackingModule.pywraps MediaPipe'sfunctionalitytotrack213Dlandmarksofthe hand. This module provides the critical bounding box coordinatesrequiredtocropthehandfromthevideoframe effectively,ensuringthatthesubsequentclassificationmodel receives only relevant data. The use of skeletal tracking rather than raw pixel processing allows the system to remainrobustagainstcomplexbackgrounds.
ThelogiclayerishandledbyPythonscriptsthatmanagethe data flow. The ClassificationModule.py is responsible for loading the pre-trained Keras models (h5 files) and performinginference. Beforeinference,theimageundergoesstrictpreprocessing wherethehandregionisisolatedwithamargintoensure thefullgestureiscaptured,resizedto224x224pixels,and normalized to a range of 0 to 1 to improve model convergence.
ThefrontendisdevelopedusingOpenCVforrenderingthe visual output. The interface allows users to view the live feed, with bounding boxes and predicted text overlaid directlyonthescreen.ForRussianSignLanguage(RSL),a specific challengearisesas standard OpenCV functions do not support Cyrillic characters well. To address this, a UTF8ClassificationModule was implemented using the Python Imaging Library (PIL) to render Unicode text correctlybeforeconvertingitbacktoanOpenCVarrayfor display.
To ensure high accuracy, custom datasets were collected usingthedatacollection.pyscript.Thisscriptautomatesthe process of capturing and cropping hand gestures, saving them into labeled folders for training. The trained models arestoredasmodel_asl.h5,model_isl.h5,andmodel_rsl.h5, whichareloadedintomemoryduringsysteminitialization. Thismodularstorageallowsforeasyupdatesortheaddition of new languages without rewriting the core application logic.
Robustnessisacriticalaspectofthesystemimplementation. By using MediaPipe landmarks, the system handles slight variationsinlightingandhandorientationeffectively.The interfaceisdesignedtobeminimalandintuitive,requiring notechnicalknowledgetooperate.Additionally,thesystem
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 01 | Jan 2026 www.irjet.net p-ISSN: 2395-0072
provides real-time feedback, processing frames at a sufficientratetoensureasmoothuserexperience.
This section discusses the results obtained after implementing and testing the proposed Multilingual Sign LanguageRecognizer.Thesystemwastestedundervarious conditions to validate the correctness of gesture classificationandtheresponsivenessoftheinterface.
The classification performance was evaluated for each language module to ensure distinct accuracy across the linguistic spectrum. The ASL model demonstrates high accuracy,exceeding95%fordistinctstaticsignslike'A','B', 'C', 'L', and 'V'. For ISL, the system successfully detects double-handedgestures,a uniquefeatureofthelanguage, provided the user is positioned slightly further back to capturebothhandswithintheframe. Furthermore,theRSLmodelsuccessfullyidentifiesCyrillic gestures, distinguishing the system from standard recognizersthatfailtoprocessnon-Latinscripts.
The performance of the system was evaluated based on latency and frame rate. The system responds with low latency,updatingthecharacterinstantlyastheuserchanges theirhandshape.ThelightweightnatureoftheMediaPipe frameworkallowsthesystemtoruneffectivelyonstandard CPUswithoutrequiringhigh-endGPUs,ensuringitmeetsthe non-functionalrequirementofprocessingframesat15-20 FPSforasmoothexperience.
The cost and resource analysis highlights the economic benefits of the proposed solution. Unlike sensor-based systems that rely on expensive hardware like Microsoft KinectorCyberGloves,thissystemrequiresonlyastandard USB webcam or integrated laptop camera. This drastic reduction in hardware dependency makes the technology accessible to a wider demographic. Furthermore, the modular architecture ensures that adding new languages doesnotexponentiallyincreasecomputationaloverhead,as only the relevant model is loaded during execution.
The proposed Multilingual Sign Language Recognizer demonstrates an effective solution for bridging the communication gap across different linguistic regions. By integrating ASL, ISL, and RSL into a single platform, the
project moves beyond the fragmentation seen in existing systems.Theimplementationvalidatesthatcomputervision techniques,specificallyMediaPipeandCNNs,caneffectively interpretdiversegesturesets fromsingle-handedASLto double-handed ISL and Cyrillic RSL without specialized hardware.Thisproof-of-conceptservesasafoundationfora moreinclusiveglobalcommunicationtool.
Although the current implementation successfully demonstrates multilingual recognition, several enhancements can be considered in future work. Future iterations could move from static alphabet recognition to dynamic words and sentence recognition to enable fluid conversation.Additionally,developingamobileapplication wouldincreaseportabilityandaccessibilityforusersonthe go. There is also potential for integrating Large Language Models (LLMs) to refine the recognized text and provide context-awaresentenceconstruction,assuggestedbyrecent research. Finally, developing a multilingual output engine thattranslatesrecognizedgesturesintolocalizedspokentext would further bridge the gap between deaf and hearing communities.
Theauthorswouldliketoexpresstheirsinceregratitudeto Mrs. T. Madhumathi, Assistant Professor, for her constant guidance and moral support throughout the project. The authorsalsothankthefacultymembersoftheDepartmentof Information Technology, TKR College of Engineering and Technology,fortheirsupport.
[1] MediaPipe & CNN for ASL: "Enhancing Sign Language Detection through Mediapipe and Convolutional Neural Networks(CNN),"ResearchGate
[2]ISLRecognition:"IndianSignLanguageRecognitionusing ConvolutionalNeuralNetwork,"ITMWebofConferences
[3] RSL Datasets: "Slovo: Russian Sign Language Dataset," SberLabs
[4] General Methodology: "Real-Time Sign Language Recognition Using MediaPipe and Deep Learning Approaches,"JETIR.
[5] Kulkarni, A., Kariyal, A. V., Dhanush, V., & Singh, P. N. (2021).SpeechtoIndiansignlanguagetranslator.Atlantis Highlights in Computer Sciences/Atlantis Highlights in ComputerSciences
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 01 | Jan 2026 www.irjet.net p-ISSN: 2395-0072
[6] Najib, F. M. (2024). Sign language interpretation using machine learning and artificial intelligence.Neural ComputingandApplications.
[7] Indian sign language translator. (2022, December 1). IEEEConferencePublication|IEEEXplore.
[8]Papastratis,I.,Chatzikonstantinou,C.,Konstantinidis,D., Dimitropoulos,K.,&Daras,P.(2021).Artificialintelligence technologiesforsignlanguage.Sensors,21(17),5843.
2026, IRJET | Impact Factor value: 8.315 | ISO 9001:2008