
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Srushti Haware1, Sakshi Hiremath2, Sharayu Sanap3, Janhavi Inamdar4, Prof. Shweta Shah5
Dept. of Computer Engineering, Pune Institute of Computer Technology, Pune, India
Abstract - Software systems today are growing faster and getting morecomplex thantraditionaltestingworkflowscan handle. Converting requirement documents and UI designs into executable test cases still demands heavy manual effort, and the resulting coverage is often incomplete. While LLMs have opened new possibilities for automating parts of this work, most systems built on them treat test generation as a one-shot problem fire a prompt, get scenarios, done. There is no coordination across stages, no real handling of multimodal inputs, and no mechanism for the system to respond when a generated test actually fails. This paper describes an agentic AI framework built to address these gaps. The system chains four specialized agents into a pipeline: one handles multimodal input processing, one generates Gherkin-format test scenarios, one converts those scenarios into runnable Playwright/Pytest scripts, and a human-in-the-loop validation layer sits between generation and execution to catch problems early. When tests fail or reviewers reject scenarios, the system regenerates rather than moving on. Implemented using a hybrid local-cloud inference setup and evaluated on an employee shift management application, results showed meaningful gains in test coverage and a high proportion of directly executable scripts, with low manual effort overall.
Key Words: AgenticAI,AutomatedSoftwareTesting,Test Case Generation, Large Language Models, Multimodal Learning, Gherkin, Test Automation, Playwright, Humanin-the-Loop,SoftwareTestingFramework
Testingisoneofthosephasesinsoftwaredevelopmentthat everyoneagreesiscritical,yetitconsistentlyreceivesless attentionthanitdeserves partlybecauseitistedious,and partly because automating it well is genuinely hard. As systems grow larger and release cycles compress, manual testing becomes a bottleneck. Rule-based automation helps,butitrequiressignificantupfronteffortandtendsto breakwhenrequirementschange.Theresultisincomplete coverage,late-stagebugs,andexpensiverework.
Early AI approaches to this problem applied machine learningtogeneratetestcasesorpredictdefect-pronecode [1]–[4]. These methods worked reasonably well on structured inputs but struggled with unstructured requirements or dynamic interfaces. The arrival of Large Language Models changed what was possible LLMs can readnaturallanguagespecificationsandgenerateplausible test scenarios without task-specific training [5]. Liu et al., forinstance,showedthatGPT-basedmodelscouldperform zero-shotGUItestingonmobileapps,handlinginteractions that previously required human intuition [6]. Unit test
generationhasalsoseenpromisingresultsfromLLM-based approaches[7].
TheproblemisthatusinganLLMasastandalonestepdoes not actually solve testing automation it just moves the bottleneck. Without any coordination between stages, generated outputs pile up redundancies, contradict each other, and often cannot run without manual cleanup. CombiningarequirementsPDFwithUIscreenshotsinthe same analysis pass is rarely supported. And if a test fails during execution, there is nothing to close that loop: the failuresitsinareportandahumanhastodiagnoseit.
Agentic AI addresses these gaps by structuring the work across multiple coordinated agents, each with a welldefinedrole[8],[9].RatherthanoneLLMdoingeverything, the agents divide responsibilities one parses inputs, another reasonsabout what scenariosare needed,a third writesthescripts.Thisdecompositionmakesitmucheasier tointroducefeedbackateachhandoff[10]–[12],andinthe testing domain specifically, it allows the pipeline to validate, execute, and refine generated tests rather than justproducingthem.
Thecontributionsofthisworkareasfollows:
• Amulti-agentpipelineforautomatedsoftwaretesting, covering input processing, scenario reasoning, script generation,andexecution withina single coordinated workflow.
• A multimodal input processing approach that jointly handles requirement documents and UI screenshots ratherthantreatingthemseparately.
• Atraceabletransformationpathfromnaturallanguage requirementsthroughGherkinscenariostoexecutable Python scripts, with identifiers linking each artifact backtoitsorigin.
• A human-in-the-loop validation layer with a feedback mechanism that triggers regeneration of rejected or failedtestcases.
• Anevaluation on a real applicationcomparing results againstmanualtestingandsingle-stepLLMgeneration baselines.
ResearchonAI-assistedsoftwaretestinghasa reasonably long history at this point. Early work applied supervised learning to fault prediction and test case prioritization. Results were promising, but these methods depended heavily on structured and labeled input data [1]–[4] which meant they struggled the moment requirements were expressed informally or UIs changed without warning.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
LLMs shifted the conversation significantly. Wang et al. provideda broadsurveyofLLM-basedtestingtechniques, showing that models pretrained on code and natural language can interpret specifications and produce test cases without fine-tuning [5]. Liu et al.'s zero-shot mobile GUI testing work was particularly illustrative GPT-3 could simulate interactions on apps it had never seen duringtraining[6].UnittestgenerationwithLLMshasalso shown consistent gains [7]. But the pattern across all this work is the same: LLMs handle understanding and generation well. Orchestration is where they fall short managing multi-step flows, recovering from failures, and keepingupwithchangingrequirements.
AgenticAIhasemergedasthearchitecturalresponse.The premiseisstraightforward:decomposecomplextasksinto componentshandledbyspecializedagents,thencoordinate them [8], [9]. In testing, this has shown up in scriptless automation frameworks [11], [12] and in test-driven development pipelines [10]. LLM-driven unit test generationusingagenticsetupsisalsogainingtraction[7]. The gapsin current work,though,are real.Handling both text and images as inputs at the same time is largely unsupported most frameworks pick one or the other. Feedback based on actual execution outcomes is even rarer;atestfails,areportgetswritten,andthatistheend ofit.Scalability,traceabilityacross stages,androbustness indynamicenvironmentsalsoremainopenproblems[13]–[16].Thesearethegapsthisworksetsouttoaddress.
The system is built as a multi-agent, modular pipeline whereeachagentisresponsibleforexactlyonestageofthe workflow.Fig-1showstheoverallstructure.
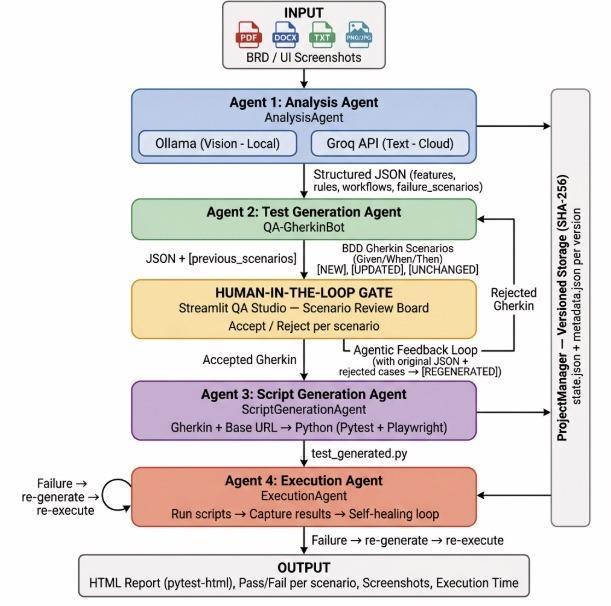
The pipeline beginswithrequirementdocuments(PDF or DOCX) and UI screenshots as inputs. The Analysis Agent processes both together and encodes the extracted information in a JSON format that captures features, workflow sequences, constraints, and anticipated failure modes.Keepingeverythinginastandardizedintermediate format means each downstream agent can be developed anddebuggedindependently.
The Test Generation Agent takes this JSON and produces BDD-styleGherkinscenarios.Generationisconstrainedso eachscenariocoversexactlyonelogicaloutcome,avoiding thecombinatorialexplosionthathappenswhenanLLMis givenfreereinoverconditions.Scenariosarealsotaggedas NEW, UPDATED, or UNCHANGED, allowing the system to handle evolving requirements incrementally without discardingpreviouslyvalidatedwork.
Before any script is written, generated scenarios go throughaHITLvalidationlayer.Thereviewercanaccepta scenario or send it back. The generator rarely produces outright wrong scenarios the failures tend to be subtle, the kind that would pass a quick reading but break at executiontime.Thereviewstepcatchesthose.
The Script Generation Agent converts accepted Gherkin scenarios into Python test scripts using Playwright and Pytest. Each scenario maps to a uniquely named test function,keepingrequirementsandexecutabletestslinked. Scripts cover both frontend interactions (via Playwright) andbackendstatechecks(viaAPIcalls).
TheExecutionAgentrunsthegeneratedscriptsandroutes failureinformationbackintothepipeline.Afailedtestdoes notjustproduceareport ittriggersregeneration.Astate management component handles versioning with hashbasedchangedetection,sorerunsonlyregeneratewhathas actuallychanged.
TheAnalysisAgentsitsattheentrypointofthepipeline.It takes multimodal inputs PDF or DOCX files for textual requirements, and screenshots for visual context and convertsthemintoastructuredJSONrepresentation.Text goesthroughacloud-basedLLM(GroqAPI);screenshotsgo throughalocallyhostedvisionmodelviaOllama.Thissplit is deliberate: cloud inference gives stronger language understanding, while running vision locally means screenshotsfromproprietaryUIsneverleavethemachine. The output JSON captures features, technical rules, workflow sequences, and failure scenarios. Forcing the analysisintothisformatsurfacesthingsthatrequirements documents leave implicit what should happen at a boundary value, what the system state looks like after an errorthatnoonebotheredtodocument.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
The TestGenerationAgent readsthe structured JSON and produces Gherkin scenarios. The prompt includes constraints arrived at through iteration: one outcome per scenario,nocross-productcombinationsofconditions,and explicitcoverageofnegativeandedgecasesalongsidethe functional ones. Without those constraints, early versions produced technically valid scenarios that were almost entirelyhappy-path.
Version-aware generation works by including previously acceptedscenariosinthepromptcontext.Theagentlabels eachnewoutputasnew,updated,orunchanged,lettingthe reviewerfocusonwhathasactuallyshiftedratherthanrereviewingeverything.
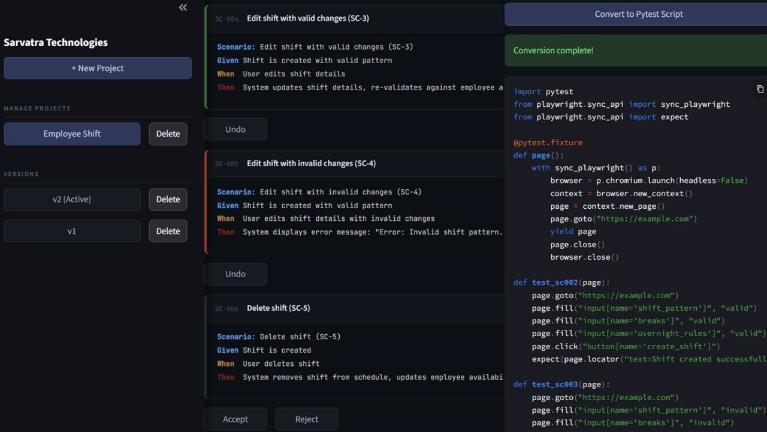
The HITL layer is a Streamlit interface. Each scenario is shown alongside the script it would produce so the reviewerseesnotjustwhatthetestchecks,buthowitplans to check it. Accepted scenarios move to script generation. RejectedonesgobacktotheTestGenerationAgent;ifthe reviewer left a comment explaining why, that comment is includedintheregenerationprompt.
Showing the script alongside the scenario was a design decision made after early testing showed reviewers missingexecution-levelissuesthatlookedfineinGherkin. Thetwo-panelviewsolvedthat.
The Script Generation Agent converts validated Gherkin scenarios into executable Python test scripts. Each Given/When/Then step maps to Playwright actions and assertions. The prompt enforces consistent patterns for navigation,forminteraction,andresponsevalidation,while stillleavingroomforscenario-specificbehavior.
After generation, a post-processing step scrubs the output stripping markdown artifacts, fixing indentation, and catching syntax issues. Scripts that fail this check are flaggedbeforetheyeverreachtheexecutor.
TheExecutionAgentcallsPytestviasubprocess,capturing stdout, stderr, and the structured JSON report from the pytest-htmlplugin.Foreachtestfunctionittrackspass/fail, errortraces,andexecutiontime.
Whentestsfail,theerrortracesgetparsedandsummarized before being sent back to the Script Generation Agent as additionalcontext.Failurestendedtofallintotwobuckets: timing issues (element not ready when the script tried to interact with it) and logic errors in the generated script itself. The feedback mechanism handled both for timing issues,theagentwouldaddexplicitwaits,whilelogicerrors sometimesneededafullregenerationofthescenario.
Every pipeline run produces a versioned snapshot: the input hash, the scenario JSON, the accepted subset, and
execution results. On subsequent runs, the system hashes inputs at the feature level and compares against the previoussnapshottoidentifywhatneedsregeneration.For large requirement sets these matters re-running the full pipeline from scratch every time would be prohibitively slow.
The framework is implemented in Python. Agents are independent modules sharing a data directory, which makesiteasytorestartthepipelinefromanystagewithout rerunningwhatalreadyworked.
A central coordinator manages stage transitions and handleserrorsbetweenagents.DataispassedviaJSONfiles on disk rather than in-memory between agents. The practical reason: at any point during development or debugging, the intermediate file can be opened to see exactlywhatoneagenthandedtothenext.Italsomadeit straightforwardtore-runasinglestageinisolation.
Text-basedrequirementdocumentsgototheGroqAPIfor structured extraction. Screenshots run through Ollama withavision-capablemodellocally.Oneissueencountered early: screenshots from different UI frameworks React, Angular, plain HTML can look very different even when they represent the same interaction. The model would sometimes misidentify elements or miss interactive components entirely. This was addressed by including explicit prompts about element identification, rather than letting the model infer semantics from visual appearance alone.
Text-based LLM inference runs through the Groq API. VisioninferencerunslocallyviaOllama.Playwrighthandles browserautomation;Pytestisthetestrunner;pytest-html generates structured execution reports. All model parameters, API endpoints, and timeout values live in a single YAML configuration file swapping models during experimentationwasjustamatterofeditingoneline.
The script generation prompt includes the Gherkin scenario,theapplication'sbaseURL,andasetofPlaywright conventions standardized over several iterations for example, always calling page.wait_for_selector before touching a dynamic element, and always checking API responses with page.expect_response. Getting theseconventionsrighttooktime.Earlyscriptspassedlocal testsbutbrokeinCIbecausetheyassumedelementswould be ready faster than they actually were in a headless environment.
International Research Journal of Engineering and Technology (IRJET) e-ISSN:
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Testfunctionnamesarederiveddeterministicallyfromthe scenario title, so traceability holds even when scripts are regenerated.
TheExecutionAgentrunsPytestasanexternalsubprocess rather than invoking it programmatically. Subprocess invocationgivescleanerexitcodesandavoidsstateleaking between test runs something that caused intermittent, hard-to-diagnose failures when the programmatic approachwastriedearlyon.
After each run, results are parsed into a summary (totals, pass/fail counts, per-test details) and written to the versioned state directory. The Streamlit interface also reflects these results so reviewers can see execution outcomeswithoutleavingthevalidationUI.
The Streamlit interface shows each scenario as a card: Gherkin on the left, the corresponding script on the right. Reviewerscanaccept,reject,ordefer.Rejectingascenario opens a comment field; the comment travels with the scenario back into regeneration. Once decisions are submitted, rejected scenarios queue immediately for regeneration while accepted ones move to the script generationstage.
6. RESULTS AND DISCUSSION
The framework was evaluated on an employee shift management application a system with non-trivial business logic around role-based access, schedule validation, and notification triggers. Input consisted of a requirements document (DOCX) and eight UI screenshots coveringthemainworkflows.Thesystemranonastandard developmentmachineusingGroqAPIfortextinferenceand LLaVAlocallyforvision.
The Analysis Agent extracted structured representations fromallinputs,includingseveralconstraintsthatwereonly implicit in the screenshots validation rules for shift overlaps and role permissions that the text document left underspecified.The Test Generation Agentthenproduced scenarios spanning four categories: functional, negative, boundary,andedgecases.
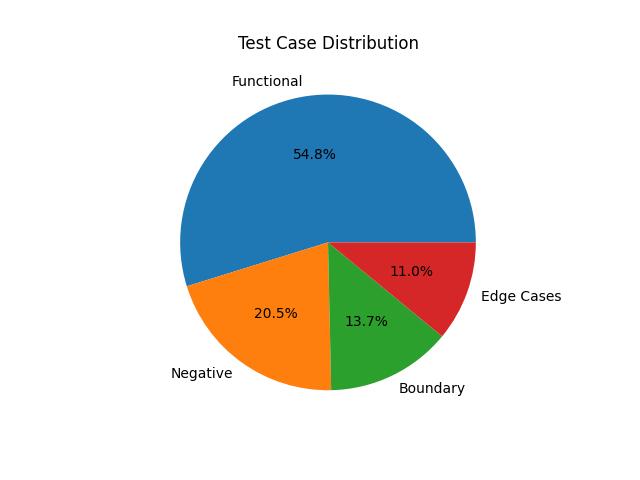
Fig -3: Distributionofgeneratedtestcasesacrossdifferent categories.
As Fig -3 shows, functional scenarios made up roughly 54.8% of the total expected, given the structure of the prompt. What was more notable was the proportion of negative (20.5%) and boundary (13.7%) cases generated without those categories being explicitly requested. They emerged from the constraints the Analysis Agent had encoded.Edgecasescameinat11%.Thesecategoriestend togetskippedorunderrepresentedinmanualplanning,so havingthemappearorganicallywasameaningfulresult.
C. Human-in-the-Loop Validation Results
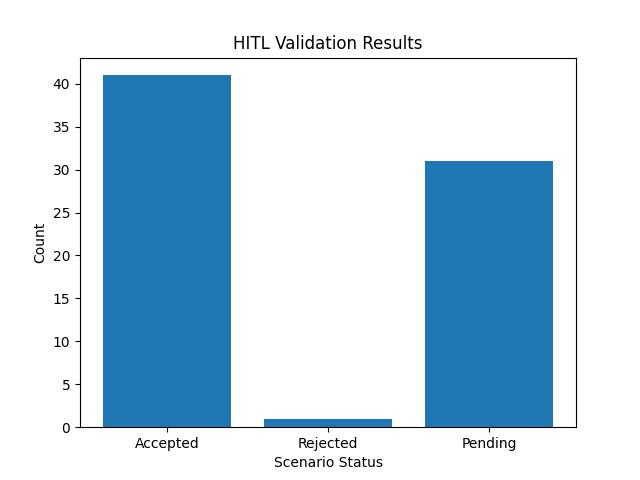
-4: Validationoutcomesofgeneratedtestscenarios usingtheHITLinterface.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Fig -4 shows how scenarios were categorized during review.Most were acceptedoutright.Rejectionsclustered around edge-case scenarios where the agent had filled in gaps with assumptions that did not match how the applicationactuallybehaved shiftscrossingmidnight,for instance, or permission checks on recently deactivated accounts. The side-by-side script view helped reviewers catch these quickly; without it, the Gherkin alone often looked reasonable. Scenarios that were rejected with reviewer comments almost always passed on the second generation.
AllacceptedGherkinscenariosweresuccessfullyconverted to executable Python scripts. Each test function carried a unique identifier traceable back to its source scenario. Scripts covered both frontend interactions and backend APIvalidationratherthanjustsimulatingUIclicks.
Table -1: EvaluationofGeneratedTestScripts Metric Observation Inference
TestCase Diversity High Coversmultiple categories
Script Generation Success Consistentlyhigh Reliable automation output
Manual Intervention Required Low Efficient automation
Traceability Maintained End-to-end mappingensured
Table -1 summarizes these results. The post-processing stepcaughtminorsyntaxissuesinroughly12%ofscripts beforetheyreachedtheexecutor mostlymarkdowncode fences left in the output, and occasional indentation problemsinnestedassertions.
Most scripts ran successfully on the first attempt. The failures that did occur split into two categories: timingsensitivescenarioswherePlaywrighttriedtointeractwith elementsbeforethepagehadfullyloaded,andahandfulof API validation steps where the expected response format hadquietlychanged.Thefeedbackloopcaughtbothtypes andtriggeredregenerationwiththerelevanterrorcontext attached to the prompt. Timing failures were resolved by the agent adding explicit waits; the API failures required regeneratingtheassertionlogic.
TheHTMLreportsproducedbypytest-htmlweregenuinely helpful during this phase. Having full error traces in line withthetestdescriptionmeantfailurescouldbediagnosed withoutre-runningtheframeworkinteractively.
Table -2: ComparisonwithExistingApproaches
Approach Automation Level Test Coverage Feedback Loop
Manual Testing Low Limited No
LLM-based Generation Medium Moderate No
Proposed Framework High Comprehensive Yes
Table -2 puts the system in context against the two most obvious alternatives. Manual testing is precise but slow, and scales poorly as requirements grow. Single-step LLM generationspeedsthingsupbutproducesoutputsthatstill needsignificanthumancleanupandoffernorecoverypath whentestsfail.Theproposedframeworkistheonlyoneof the three that treats execution outcomes as inputs to the generationprocessratherthanjustfinalresults.
Thecorebetofthiswork thatstructuringtestgeneration acrossspecializedagentsratherthanrunningasingleLLM would produce better results held up across the evaluation. The framework handled multimodal inputs in cases where the screenshots contained UI state that the requirements document had not described in text. The HITL layer intercepted failures that would have been invisibletoautomatedchecks.Andthefeedbackloop,while notfullyautonomous,reducedthemanualdebuggingeffort substantially.
Thatsaid,reallimitswereencountered.Thequalityofthe structuredJSONrepresentationdependsonhowclearlythe input requirements are written vague or contradictory requirements produce vague JSON, and those problems compound as the data moves through the pipeline. The feedbackloopalsocannotresolveinfrastructureissueson its own; when failures were caused by environmentspecific configuration (proxy settings, certificate issues in CI),theagentflaggedthemcorrectlybutcouldnotfixthem. Scale testing was also not performed large requirement setswouldputpressureonLLMcontextwindowsinways notyetcharacterized.
Future work should prioritize two areas: making the execution feedback more autonomous, and improving the vision model's robustness across a wider range of UI frameworksandinteractionpatterns.
This paper presented an agentic AI framework for automatedtestcasegenerationandexecution.Thesystem chains four specialized agents covering input analysis, scenario generation, script production, and execution feedback intoapipelinethattakesmultimodalinputsand
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
producesrunnablePytest/Playwrightscriptswithminimal manual effort. A HITL validation layer and closed-loop feedbackmechanismallowiterativeimprovementwithout restartingfromscratch.
Evaluationonarealshiftmanagementapplicationshowed strongtestcoverage,ahighrateofscriptexecutionsuccess, and meaningful reduction in manual effort compared to both manual testing and single-step LLM generation. The agentic design proved particularly valuable for the cases thatsingle-stepgenerationhandlespoorly:combinedtextand-image inputs, incremental requirement updates, and recoveryfromexecutionfailures.
Three directions for future work stand out. First, making the execution feedback more autonomous right now environment-specific failures are caught but not automatically fixed. Second, extending the vision model's capability to handle more complex UI patterns; degraded performance was observed on applications with heavy dynamicrenderingandcontext-dependentelementstates. Third, wiring the framework into CI pipelines so that test regeneration triggers automatically on requirement or code changes, removing the need for manual pipeline invocation.
[1] M.U.ShafiqueandM.A.Khan,"Asurveyontheimpact of AI in software testing," Journal of Software EngineeringResearchandDevelopment,vol.10,no.1, 2022.
[2] Y. Zhang and X. Zhao, "AI-based testing techniques: A systematic review and future directions," ACM ComputingSurveys,vol.54,no.3,2021.
[3] S.DeyandA.Gupta,"Enhancingsoftwaretestingwith artificial intelligence: A review," Software Quality Journal,vol.28,no.4,2020.
[4] Y. Liu and J. Wang, "Automated test case generation using deep learning techniques," Journal of Systems andSoftware,vol.203,2023.
[5] S.Wang,M.Zhou,L.Zhaoetal.,"Softwaretestingwith largelanguagemodels:Survey,landscape,andvision," arXivpreprintarXiv:2307.07221,2023.
[6] X. Liu, T. Wang, Y. Chen, J. Zhang, and Y. Li, "Chatting with GPT-3 for zero-shot human-like mobile automated GUI testing," arXiv preprint arXiv:2305.09434,2023.
[7] "LLM-drivenunittestcasegenerationusingagenticAI," IROJournals,2024.
[8] "Agentic AI: Autonomous intelligence for complex goals Acomprehensivesurvey,"IEEE,2024.
[9] "The rise of agentic AI: A review of definitions, frameworks, architectures, applications, evaluation metrics,andchallenges,"FutureInternet,vol.17,no.9, 2024.
[10] S.Hawareetal.,"Retailresilienceengine:Anagentic AIframeworkforbuildingreliableretailsystemswith
test-driven development approach," in IEEE Conference,2024.
[11] "Agentic AI-based test automation: A strategic leap forwardforenterprises,"ResearchGate,2024.
[12] "AIagenticscriptlessautomationinsoftwaretesting," International Journal of Computer Trends and Technology,vol.72,no.9,2023.
[13] P. Gokhale and S. Gokhale, "AI in software testing: A comprehensive review," Journal of Computer Languages,Systems&Structures,vol.62,2021.
[14] H. Kaur and S. Singh, "The role of AI in software testing: Current trends and future directions," International Journal of Software Engineering and Applications,vol.13,no.1,2022.
[15] T.MenziesandM.Pezze,"AIforsoftwareengineering: Aroadmap,"IEEESoftware,vol.37,no.5,2020.
[16] J.RojasandJ.A.Pino,"Thefutureofsoftwaretesting: AI and machine learning," Software Testing, VerificationandReliability,vol.31,no.8,2021.