
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072

International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
Aswathy K R1 , Ligi Achuthan2
1 Assistant Professor, Department of CSE, College of Engineering Munnar, Kerala ,India
2Assistant Professor, Department of CSE, College Of Engineering Munnar,Kerala,India
Abstract - Deep metric learning has emerged as a fundamental paradigm in modern computer vision and pattern recognition tasks, including content-based image retrieval (CBIR), facerecognition,personre-identification,and remote sensingimageanalysis.Amongvariousmetriclearning approaches, triplet loss has gained widespread adoption due to its ability to directly model relative similarity relationships between samples. Specifically, it enforces a constraint that ensures semantically similar samples are closer in the embeddingspace thandissimilar ones. However,conventional triplet loss relies on a fixed margin, which often leads to suboptimalperformance due tovariationsinsampledifficulty, intra-class variability, andcomplex data distributions. A fixed margincannot adapt todiversetrainingscenarios,resultingin inefficient learning and slow convergence. To address these limitations, recent research has focused on adaptive margin strategies, where the margin is dynamicallyadjustedbasedon samplecharacteristicssuchasdistancerelationships,semantic similarity, andgradient behavior [13], [14].Inparallel,several advanced loss functions, including N-pair loss [3], lifted structured loss [4], proxy-based loss [5], and circle loss [8], have been proposed to overcome the limitations of triplet sampling and improve convergence efficiency. These approaches provide more robust optimization frameworks and enhance embedding quality in large-scale and complex datasets. This survey presents a comprehensive review of adaptive margin strategies and triplet-based loss function variants. It analyzes their mathematical formulations, advantages, and limitations, and discusses their applications in CBIR and remote sensing domains [18]. Furthermore, key research challenges and future directions are identified, particularly in the context of multi-label learning and largescale metric learning systems
Key Words: Triplet Loss, Adaptive Margin, Metric Learning, Deep Learning, CBIR, Remote Sensing
Deepmetriclearningaimstolearnatransformationfunction thatmapsinputdataintoafeatureembeddingspacewhere semanticallysimilarsamplesarepositionedclosertogether, while dissimilar samples are pushed farther apart. This paradigmplaysacrucialroleinsimilarity-basedtaskssuch as image retrieval, face verification, visual search, and clustering. Among various metric learning approaches, triplet loss has emerged as one of the most influential techniques due to its ability to explicitly model relative similarity constraints. Triplet loss was popularized by the FaceNetframework[1],whereitdemonstratedremarkable performance in face recognition by learning highly discriminative embeddings. The triplet loss framework operates on triplets consisting of an anchor sample (a) ,a positivesample(p)belongingtothesameclass,anegative sample(n) belongingtoadifferentclassTheobjectiveisto enforceaconstraintsuch
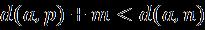

where is a distance metric and is the margin. This ensuresthattheanchorisclosertothepositivesamplethan tothenegativesamplebyatleastamargin.
Despiteitseffectiveness,traditionaltripletlosssuffersfrom severalinherentlimitationsthathinderitsperformancein complexandlarge-scaledatasets.
One of the most critical limitations is the use of a fixed margin.Aconstantmarginassumesthatalltripletsrequire the same degree of separation, which is unrealistic in practice.Real-worlddatasetsoftenexhibitvaryinglevelsof difficulty:Easysamplesarealreadywellseparated,requiring smallmarginsHardsamplesareoverlappingorambiguous, requiring larger margins Using a fixed margin leads to inefficient learning, as it cannot adapt to these variations.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
This results in slower convergence and suboptimal embeddingstructures[11].
Another major challenge is the dependence on triplet sampling.The numberofpossibletripletsgrowscubically withthedatasetsize,makingexhaustivetraininginfeasible. Therefore,selectinginformativetripletsbecomesessential. TripletscanbecategorizedasEasytripletsthatcontribute little to learning .Hard triplets may introduce noise and instability.Semi-hardtripletsprovidemeaningfulgradients FaceNet [1] introduced semi-hard mining, but identifying such triplets requires additional computational overhead. Improper sampling can significantly degrade model performance.
Infixed-margintripletloss,onceatripletsatisfiesthemargin constraint,itnolongercontributestotheloss.Thisresultsin alargenumberofinactivetriplets,reducingtheefficiencyof trainingandslowingdownconvergence[11].
1.1.4
Traditional triplet loss relies purely on distance-based relationships and does not consider higher-level semantic information.Thisbecomesamajorlimitationinmulti-label datasets ,remote sensing images ,complex visual scenes .Samples with partial semantic similarity are treated as completelydissimilar,leadingtopoorembeddingquality.
Toovercometheselimitations,recentresearchhasfocused onimprovingtripletlearningthroughtwomaindirections:
Adaptivemarginmethodsdynamicallyadjustthemargin basedonsamplecharacteristics.Forexample:Distancebasedadaptivemargin[13],Gradient-awareadaptive margin [14] Theseapproachesallowthemodeltohandle varyingsampledifficulty,improveconvergence and reducedependenceonsampling
Several loss functions have been proposed to address inefficiencies in triplet learning N-pair loss improves convergenceusingmultiplenegatives[3] Liftedstructured lossutilizesallpairwiserelationships[4] Proxy-basedloss
reducescomputationalcomplexity[5].Multi-similarityloss andcirclelossprovideunifiedoptimizationframeworks[7], [8] .These methods enhance scalability and embedding quality.
TripletlearninghasbeenwidelyadoptedinCBIRsystems, wherethegoalistoretrieveimagessimilartoaqueryimage. Inremotesensing,datasetsarelargeandcomplex,making metriclearningessential.Forinstance,theTLDCNNmodel proposedin[18]demonstrateshowtripletlosscanbeused to learn compact and discriminative features for remote sensingimageretrieval.
Thispaperprovidesacomprehensiveoverviewofadaptive margin strategies and loss function variants in triplet learning. The main contributions are detailed analysis of conventionaltripletlossanditslimitations,acomprehensive review of adaptive margin techniques [13]–[15] ,an overviewofadvancedlossfunctions[3]–[8],a discussionof applications in CBIR and remote sensing [18], [19] ,identificationofresearchgapsandfuturedirections
Tripletlossisdefinedas:
where , , and represent the anchor, positive, and negativesamples,respectively.Thegoalistoensure:
This constraint enforces a structured embedding space where intra-class distances are minimized and inter-class distancesaremaximized.
It does not adapt to sample difficulty, leads to inactive triplets ,slows down convergence ,ignores semantic relationships .These limitations motivate the need for adaptive margin strategies and advanced loss functions, whicharediscussedinthefollowingsections.
To address the limitations of fixed-margin triplet loss, adaptive margin strategies have been proposed as an effective enhancement in deep metric learning. Unlike conventionalapproachesthatemployaconstantmarginfor
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
alltriplets,adaptivemarginmethodsdynamicallyadjustthe margin based on sample characteristics such as distance relationships, semantic similarity, and gradient behavior. Thisenablesthemodeltobetterhandlevariationsindata distribution and sample difficulty, resulting in improved convergenceandembeddingquality.
Thecoremotivationbehindadaptivemarginlearningliesin theobservationthatdifferenttripletsrequiredifferentlevels ofseparation.Easytriplets,whicharealreadywellseparated in the embedding space, do not require large margins, whereas hard triplets with overlapping features require strongerconstraints.Bydynamicallyadjustingthemargin, adaptive methods provide a more flexible and efficient learningframework
Distance-basedadaptivemarginstrategiesadjustthemargin accordingtotherelativedistancesbetweenanchor,positive, and negative samples. The key idea is to assign larger margins to harder samples and smaller margins to easier ones, thereby enforcing appropriate separation in the embeddingspace.Arepresentativeapproachinthiscategory istheadaptivemargintripletlossproposedin[13].Inthis method, the margin is derived from the relative rating or similaritydifferencesbetweensamples.Insteadofenforcing auniformmargin,themodellearnsanembeddingspacethat reflectstheunderlyingsimilaritydistributionofthedata.One of the major advantages of this approach is its ability to preserverelativerelationshipsbetweensamplesratherthan enforcing strict binary constraints. This leads to more meaningful embeddings, especially in scenarios where similarityiscontinuousratherthandiscrete.Furthermore, as reported in [13], distance-based adaptive margin improves training stability and reduces the risk of model collapse,whichcan occur when the network converges to trivial solutions.Another important benefit is the reduced reliance on complex triplet mining strategies. Since the marginitselfencodesthedifficultyofeachtriplet,themodel caneffectivelyutilizealargerportionofthetrainingdata
Gradient-based adaptive margin strategies extend the concept of adaptive margin by incorporating gradient information into the learning process. One of the most notablemethodsinthiscategoryisAdaTriplet[14], which introduces a gradient-aware triplet loss framework. In AdaTriplet, the contribution of each triplet to the loss functionisdynamicallyadjustedbasedonitsdifficulty.Hard tripletsgeneratelargergradientsandthushaveastronger influenceonmodelupdates,whileeasytripletscontribute less.Thisadaptiveweightingmechanismallowsthemodelto focus on informative samples without requiring explicit tripletmining
Additionally, AdaTriplet introduces an AutoMargin mechanism that automatically adjusts the margin during training. This eliminates the need for manual hyperparameter tuning, which is often a challenging and time-consumingprocessintraditionaltripletlearning.
Theadvantagesofgradient-basedadaptivemargininclude fasterconvergence,improvedoptimizationstability,reduced dependencyonsamplingstrategiesandbetterhandlingof hard and semi-hard triplets .Experimental results in [14] demonstrate that this approach significantly improves performanceincomplexapplicationssuchasmedicalimage retrievalandlarge-scalevisualrecognition.
Traditionaltripletlossfocusesprimarilyonanchor-centric relationships,i.e.,thedistancesbetweenanchor-positiveand anchor-negative pairs. However, it does not explicitly consider the relationship between positive and negative samples.Thislimitationcanleadtosuboptimalembedding structures.Toaddressthisissue,symmetricmetriclearning with adaptive margin has been proposed in [15]. This approachincorporatesadditionalconstraintsthatconsider allpairwiserelationshipswithinatriplet,includingpositivenegativeinteractions.Byintroducingsymmetricconstraints, the model ensures consistent separation between all samples in the embedding space. The adaptive margin further enhances this process by adjusting the separation based on data characteristics and user-defined similarity measures. This approach is particularly beneficial in applicationssuchasrecommendationsystemsandranking tasks,whererelationshipsamongallsamplesplayacrucial role.Asshownin[15],symmetricadaptivemarginlearning improves feature discrimination and generalization performance.
Adaptive margin strategies have also been extended to domain adaptation scenarios, where the goal is to align featuredistributionsacrossdifferentdomains.Domainshifts are common in real-world applications, such as remote sensing images captured from different sensors or geographicalregions.In[17],tripletlossisintegratedintoa domain adaptation framework using a similarity-guided constraint.Thisapproachensuresthatsamplesbelongingto the same class but originating from different domains are mappedcloserintheembeddingspace,whilesamplesfrom different classes are separated. Adaptive margin plays a crucialroleinthisframeworkbydynamicallyadjustingthe separation constraints based on domain-specific characteristics. This allows the model to better handle variationsindatadistributionandimprovescross-domain generalization. Such methods highlight the flexibility of
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
Adaptive margin strategies provide significant improvements over traditional fixed-margin triplet loss. Their key advantages include dynamic adjustment of separationconstraints,improvedhandlingofhardandsemihard samples ,reduced dependency on complex triplet mining,enhancedconvergencespeedandtrainingstability ,bettergeneralizationacrossdifferentdatasetsanddomains. Most existing adaptive margin methods rely on heuristic measuressuchasdistanceorgradientinformation,which maynotfullycapturecomplexsemanticrelationships.This limitation becomes particularly significant in multi-label datasets, where samples may share partial similarities across multiple classes. Furthermore, designing optimal marginfunctionsthatgeneralizeacrossdifferenttasksand datasets remains an open research problem. Future work should focus on integrating semantic information, label correlations, and attention mechanisms into margin adaptation.
Although conventional triplet loss provides an effective framework for learning discriminative embeddings, its performance is often limited by issues such as inefficient sampling,slowconvergence,andlackofglobalcontext.To overcomethesechallenges,severalvariantsandextensions oftripletlosshavebeenproposed.Theseapproachesaimto enhancefeaturerepresentationbyincorporatingadditional relationships among samples, improving robustness, and increasingtrainingefficiency.
Onesignificantextensionofthestandardtripletframework isthedual-anchortripletloss,whichenhancesthelearning processbyincorporatingadditionalrelationalconstraints. Unlike conventional triplet loss that considers a single anchor,thisapproachutilizesmultipleanchorsorsymmetric relationships to better capture the structure of the embedding space.In [16], a dual-anchor triplet loss is introduced within a triplet nonlocal neural network for remote sensing image retrieval. The key idea is to exploit relationshipsnotonlybetweenanchor-positiveandanchornegativepairsbutalsoamongallsampleswithina triplet. This enables the model to utilize richer contextual informationduringtraining.
By introducing additional constraints, dual-anchor triplet loss improves feature discrimination and ensures more consistentseparationacrossdifferentclasses.Moreover,it
helps reduce intra-class variability while increasing interclassseparability,whichiscrucialforhigh-resolutionremote sensingdatasets.
However, the increased number of constraints also introduces additional computational complexity. Despite this, experimental results in [16] demonstrate significant improvementsinretrievalaccuracycomparedtotraditional tripletloss.
Another important extension of triplet learning is its applicationindomainadaptation,wherethegoalistoalign feature distributions across different domains. Domain shifts, such as variations in sensor types, environmental conditions, or imaging perspectives, can significantly degrademodelperformance.In[17],tripletlossisintegrated into a domain adaptation framework using a similarityguided constraint. This approach ensures that samples belonging to the same classbut originating from different domainsaremappedcloserintheembeddingspace,while maintaining separation from samples of different classes. Unliketraditionaldomainadaptationtechniquesthatfocus on global distribution alignment, this method emphasizes class-levelalignment.Byleveragingtripletrelationships,it enhances intra-class compactness and inter-class separability across domains. This approach is particularly beneficial in applications such as remote sensing and medicalimaging,wheredomainvariationsarecommon.The results in [17] show that incorporating triplet loss significantlyimprovescross-domaingeneralization.
High-dimensional embeddings often lead to increased computationalcostandmemoryrequirements,especiallyin large-scale retrieval systems. To address this issue, lowdimensional triplet learning approaches have been proposed.In[18],aTripletLow-DimensionalConvolutional NeuralNetwork(TLDCNN)isintroducedforremotesensing imageretrieval.Theprimaryobjectiveofthisapproachisto learn compact feature representations while preserving discriminative power.By combining triplet loss with dimensionality reduction techniques, TLDCNN achieves a balance between efficiency and accuracy. The resulting embeddingsarenotonlycomputationallyefficientbutalso effectiveforsimilarity-basedretrievaltasks.Thisapproachis particularly useful in large-scale CBIR systems, where storage and computation are critical constraints. Experimental results in [18] demonstrate that lowdimensional embeddings can achieve comparable or even superior performance compared to high-dimensional representations.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
While triplet loss and its variants have been widely used, theystillsufferfromlimitationssuchasslowconvergence and reliance on triplet sampling. To overcome these challenges, several alternative loss functions have been proposed. These methods aim to improve optimization efficiency,scalability,andembeddingquality.
Contrastive loss [2] is one of the earliest approaches in metriclearning.Itoperatesonpairsofsamplesratherthan triplets,minimizingthedistancebetweensimilarpairsand maximizingthedistancebetweendissimilarpairs.Although contrastive loss is simpler than triplet loss, it does not explicitly model relative relationships among multiple samples.Thislimitsitseffectivenessincomplexscenarios whererankingrelationshipsareimportant.
N-pair loss [3] extends the triplet loss framework by considering multiple negative samples simultaneously. Insteadofcomparingasinglenegativesample,itcompares one positive sample against multiple negatives within a batch. This formulation eliminates the need for explicit triplet mining and improves convergence speed. By leveragingmultiplenegativesamples,N-pairlossprovides strongersupervisionandmorestableoptimization
Liftedstructuredloss[4]furtherextendsmetriclearningby utilizing all pairwise relationships within a batch. This approach considers both positive and negative pairs simultaneously,providingamorecomprehensivelearning signal. By incorporating multiple relationships, lifted structuredlossimprovesembeddingqualityandreducesthe reliance on carefully selected triplets. However, the increasednumberofpairwisecomparisonsleadstohigher computationalcomplexity.
Proxy-based loss [5] introduces class representatives, knownasproxies,tosimplifythelearningprocess.Insteadof comparingindividualsamples,themodelcomparessamples withtheircorrespondingproxies.Thisapproachsignificantly reducescomputationalcomplexityandeliminatestheneed forexplicittripletorpairsampling.Asaresult,proxy-based methodsarehighlyscalableandsuitableforlargedatasets. However, the use of proxies may reduce fine-grained relationshipsbetweenindividualsamples,whichcanaffect performanceincertaintasks
Multi-similarity loss [7] combines multiple similarity measures into a unified framework. It assigns adaptive weightstodifferentsamplepairsbasedontheirimportance, allowing the model to focus on informative relationships. This approach improves training efficiency and provides betterperformancecomparedtotraditionallossfunctions.It alsoreducessensitivitytosamplingstrategies.
Circleloss[8]introducesaunifiedoptimizationframework thatassignsadaptiveweightingfactorstobothpositiveand negative pairs. Unlike traditional loss functions, it dynamically adjusts the importance of each pair based on similarity scores. This flexibility allows circle loss to effectively optimize similarity relationships in the embeddingspace,leadingtoimprovedperformanceacross varioustasks
Advanced loss functions offer several advantages over traditional triplet loss. Advantages are faster convergence andimprovedoptimization,reduceddependencyontriplet sampling ,better scalability for large datasets ,enhanced embedding discrimination .However, these methods often introduce additional hyperparameters and increased computational complexity. Selecting the appropriate loss function depends on the specific application and dataset characteristics.
Triplet learning and its variants have been extensively applied in content-based image retrieval (CBIR) systems, where the objective is to retrieve images that are semantically similar to a given query. By learning an embedding space that preserves similarity relationships, tripletlossenablesefficientandaccurateretrievalinlargescale datasets. In traditional CBIR systems, handcrafted features such as color histograms and texture descriptors werecommonlyused.However,thesefeaturesoftenfailto capture complex visual semantics. Deep metric learning approaches, particularly those based on triplet loss, have significantly improved retrieval performance by learning discriminativefeaturerepresentationsdirectlyfromdata.
TripletlearningisparticularlysuitableforCBIRbecauseit directly models relative similarity relationships between images.Givenaqueryimage(anchor),themodelretrieves images (positives) that are closer in the embedding space
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
thandissimilarimages(negatives).In[18],theTripletLowDimensional Convolutional Neural Network (TLDCNN) demonstrates the effectiveness of triplet loss in remote sensingCBIR.Themodellearnscompactanddiscriminative featurerepresentations,enablingefficientretrievalevenin large-scaledatasets.Furthermore,triplet-basedmethodsare capable of capturing fine-grained similarities, which are essential in applications such as satellite image analysis, where subtle differences in land-use patterns must be identified
Remote sensing datasets present unique challenges, including high intra-class variability (e.g., different appearances of the same land type) ,low inter-class separability(e.g.,similarvisualpatternsacrossclasses)and large-scale data volumes. Triplet-based methods have proven effective in addressing these challenges. In [16], a tripletnonlocalneuralnetworkisproposedtocaptureglobal contextualinformationinremotesensingimages.Nonlocal operations enable the model to consider long-range dependencies,improvingfeaturerepresentation.Thedualanchortripletlossintroducedin[16]furtherenhancesthe learning process by incorporating relationships among all samples within a triplet. This leads to improved feature discriminationandretrievalaccuracy
OneofthemajorchallengesinCBIRandremotesensingis the limited availability of labeled data. Annotating largescaledatasetsistime-consumingandexpensive.Toaddress this issue, semi-supervised and self-supervised learning approaches have been explored. In [19], triplet loss is integrated into semi-supervised frameworks to leverage bothlabeledandunlabeleddata.Byincorporatingpseudolabeling and consistency constraints, the model can learn meaningfulrepresentationsevenwithlimitedsupervision. Thisapproachsignificantlyimprovesfeatureseparationand generalization,especiallyinearlystagesoftraining.Italso demonstrates the flexibility of triplet learning in modern learningparadigms.
Tobetterunderstandtheeffectivenessofdifferenttriplet learningstrategiesandlossfunctions,acomparative analysisispresented.Thiscomparisonhighlightskey differencesinmargindesign,learningmechanisms,and performancecharacteristics.
Method
TripletLoss[1] Fixed Rankingloss
Simple,effective Slowconvergence
AdaptiveMargin [13] Dynamic Data-drivenmargin Betterseparation Complexdesign
AdaTriplet[14] Gradient-based Automarginlearning Stabletraining Moreparameters
DualAnchor[16] Extended Multi-samplerelation Better discrimination Highcomplexity
N-pairLoss[3] Implicit Multiplenegatives Fasterconvergence Memorycost
ProxyLoss[5] None Classrepresentatives Scalable Lessprecise
CircleLoss[8] Adaptive Unifiedoptimization Highperformance Hyperparametertuning
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
Fromthecomparativeanalysis,severalimportantinsights canbedrawn.Adaptivemarginmethodsoutperformfixedmargin approaches by dynamically adjusting constraints basedonsampledifficultyanddatadistribution.Advanced loss functions reduce dependency on triplet sampling, improvingtrainingefficiencyandconvergencespeed.Triplet variants enhance robustness by incorporating additional relationships among samples, leading to better feature representation. Proxy-based methods improve scalability, making them suitable for large-scale datasets. However, these improvements often come at the cost of increased complexityandadditionalhyperparameters.
InremotesensingandCBIRapplications,thechoiceofloss function and margin strategy plays a critical role in performance. Key requirements include ability to handle highintra-classvariability,supportforlarge-scaledatasets ,incorporation of semantic similarity and robustness to limitedlabeleddata Adaptivemarginstrategiescombined withadvancedlossfunctionsprovideapromisingsolutionto these challenges. In particular, hybrid approaches that integratemultiplelearningobjectivesaregainingincreasing attention
Whilesignificantprogresshasbeenmade,nosinglemethod isuniversallyoptimal.Theeffectivenessofagivenapproach depends on factors such as dataset characteristics, computational resources, and application requirements. Future research should focus on developing unified frameworksthatcombinethestrengthsofadaptivemargin strategies and advanced loss functions while minimizing theirlimitations
Despite significant advancements in triplet learning, adaptive margin strategies, and alternative loss functions, several challenges remain unresolved. These limitations hinder the effectiveness of deep metric learning systems, particularly in large-scale, multi-label, and real-world applications. Identifying these gaps is crucial for guiding future research and developing more robust retrieval systems.
Although adaptive margin strategies improve upon fixedmargin triplet loss, most existing approaches rely on heuristic measures such as distance [13] or gradient
information[14].Whileeffective,thesemethodsdonotfully capture complex semantic relationships inherent in realworlddatasets.Forinstance,inmanyapplicationssuchas remote sensing and CBIR, similarity is not binary but continuous.Twosamplesmaysharepartialsimilaritydueto overlapping features or multiple labels. However, current margin designstrategiesoften fail tomodel suchnuanced relationships, leading to suboptimal embedding representations. Moreover, designing an optimal adaptive margin function that generalizes across different datasets remainsachallengingproblem.Existingmethodsareoften task-specificandrequirecarefultuning.
Tripletsamplingremainsoneofthemostcriticalchallenges intripletlearning.Thenumberofpossibletripletsincreases exponentiallywithdatasetsize,makingexhaustivesampling infeasible.Althoughstrategiessuchassemi-hardmining[1] improve training efficiency, they introduce additional computationaloverhead.Furthermore,impropersampling can negatively impact model performance Easy triplets contribute little to learning .Hard triplets may introduce noise and instability .Semi-hard triplets require careful selection Even with adaptive margin strategies, the dependency on effective sampling is not completely eliminated.Thishighlightstheneedformoreefficientand scalablesamplingmechanisms.
Withtherapidgrowthoflarge-scaledatasetsinapplications such as remote sensing, scalability has become a major concern.Traditionaltriplet-basedmethodsrequirepairwise or triplet comparisons, which are computationally expensive.Advancedlossfunctionssuchasproxy-basedloss [5] and multi-similarity loss [7] address this issue by reducing the number of comparisons. However, these methodsmaysacrifice fine-grained relationshipsbetween individualsamples.Balancingscalabilityandrepresentation qualityremainsanopenresearchchallenge.Futuremethods should aim to maintain detailed similarity relationships whilereducingcomputationalcomplexity.
Oneofthemostsignificantresearchgapsliesinthehandling of multi-label datasets. In many real-world scenarios, includingremotesensing,animagemaybelongtomultiple classessimultaneously.Forexample,asatelliteimagemay containbuildings,roadsandvegetation
Insuchcases,similaritybetweensamplesisnotbinarybut depends on the degree of label overlap. However, most existing triplet learning methods treat samples as either similar or dissimilar, ignoring partial similarities. This
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
limitation leads to poor embedding quality and reduced retrieval performance in multi-label CBIR systems. Developingadaptivemarginstrategiesthatincorporatelabel overlap and semantic similarity is a critical research direction.
Most current approaches focus on distance-based relationshipsanddonotexplicitlyincorporatesemanticor contextual information. However, in many applications, similarityisinfluencedbyhigher-levelfactorssuchasspatial relationships,contextualinformation andlabelhierarchies Forexample,inremotesensing,therelationshipbetween objects (e.g., roads connected to buildings) provides importantcontextualcues.Ignoringsuchinformationlimits theeffectivenessofmetriclearningmodels.Althoughsome works,suchasdomainadaptationmethods[17],attemptto incorporate semantic constraints, this area remains underexplored. Integrating semantic and contextual information into margin design and loss functions is a promisingresearchdirection
Remote sensing introduces additional complexities that make metric learning more challenging. High intra-class variability due to changes in scale, orientation, and illumination .Low inter-class separability due to similar visualpatterns Limitedavailabilityoflabeleddata Although methods such as TLDCNN [18] and dual-anchor triplet networks [16] have shown promising results, they still struggletofullyaddressthesechallenges.Inparticular,the combination of multi-label data, large-scale datasets, and domain variations makes remote sensing a challenging testbedfortripletlearningmethods.
Basedontheabovediscussion,thekeyresearchgapscanbe summarizedasfollows-Lackofmulti-labeladaptivemargin strategies,inefficienttripletsamplingmechanisms,limited scalability for large datasets, poor integration of semantic andcontextualinformation,needforhybridandunifiedloss functions
Addressingthesechallengesrequiresashiftfromtraditional distance-based approaches to more sophisticated frameworks that incorporate semantic understanding, scalability,andadaptability.Futureresearchshouldfocuson designing multi-label aware margin functions ,developing efficient sampling strategies ,integrating semantic and
contextual information ,combining multiple loss functions intounifiedframeworks
Basedonthechallengesandresearchgapsidentifiedinthe previoussection,severalpromisingresearchdirectionscan beexploredtofurtherenhancetripletlearningandadaptive marginstrategies.
Oneofthemostcriticalfuturedirectionsisthedevelopment ofadaptivemarginstrategiesspecificallydesignedformultilabeldatasets.Inreal-worldscenarios,especiallyinremote sensingandCBIRapplications,imagesoftencontainmultiple semantic labels. Instead of treating similarity as a binary relationship,futuremethodsshoulddefinemarginfunctions basedonthedegreeoflabeloverlapbetweensamples.For example,samplessharingmorelabelsshouldhavesmaller margins,whilethosewithfewersharedlabelsshouldhave largermargins.Suchapproachescansignificantlyimprove embedding quality by capturing partial similarities and complexsemanticrelationships.
Anotherpromisingdirectionisthedevelopmentofhybrid lossfunctionsthatcombinethestrengthsofdifferentmetric learning approaches. While triplet loss provides relative similarity constraints, proxy-based loss [5] improves scalability,andcircleloss[8]offersa unifiedoptimization framework. Combining these methods can lead to faster convergence ,improved embedding discrimination and reduceddependencyontripletsampling Recentapproaches such as multi-similarity loss [7] already demonstrate the benefitsofcombiningmultiplesimilaritymeasures.Future workcanfurtherexploreunifiedframeworksthatintegrate adaptivemarginstrategieswithadvancedlossfunctions.
Attention mechanisms have shown remarkable success in variousdeeplearningtasks.Integratingattentionintometric learning can enable models to focus on the most discriminativeregionsorfeatures.Inthecontextofadaptive marginlearning,attentioncanbeusedtodynamicallyadjust marginsbasedonfeatureimportance.Forexample,regions with higher semantic relevance can be assigned stronger constraints Thisapproachisparticularlyusefulinremote sensing applications, where spatial context and object relationshipsplayasignificantrole.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 03 | Mar 2026 www.irjet.net p-ISSN: 2395-0072
Theavailabilityoflabeleddataisoftenlimitedinreal-world applications.Toaddressthisissue,self-supervisedandsemisupervisedlearningmethodscanbeintegratedwithtriplet learning. As demonstrated in [19], combining triplet loss withsemi-supervisedframeworksallowsmodelstoleverage both labeled and unlabeled data. This improves representation learning and reduces reliance on manual annotations. Future research can explore contrastive pretraining followed by triplet fine-tuning to further enhanceperformance.
Scalability remains a major challenge in metric learning. Futureresearchshouldfocusondesigningmethodsthatcan efficientlyhandlelarge-scaledatasetswithoutcompromising performance.Potentialdirectionsincludeefficientsampling strategies,memory-efficientlossfunctionsanddistributed training techniques .Proxy-based methods [5] provide a promising starting point, but further improvements are needed to maintain fine-grained relationships between samples.
Extendingtripletlearningtodomainadaptationscenariosis another important research direction. In real-world applications, training and testing data often come from different distributions As shown in [17], incorporating triplet loss into domain adaptation frameworks improves cross-domainalignment.Futureworkcanintegrateadaptive marginstrategiesintosuchframeworkstofurtherenhance generalization.
Thissurveypresentedacomprehensivereviewofadaptive margin strategies and loss function variants in triplet learning.Conventionaltripletloss,despiteitseffectiveness, suffers from limitations such as fixed margin design, inefficientsampling,andlackofscalability.Adaptivemargin strategies address these issues by dynamically adjusting separation constraints based on sample characteristics. Methodssuchasdistance-basedadaptivemargin[13]and gradient-aware approaches like AdaTriplet [14] demonstratesignificantimprovementsinconvergenceand embedding qualityIn addition, advanced loss functions, including N-pair loss [3], proxy-based loss [5], multisimilarity loss [7], and circle loss [8], provide alternative frameworksthatenhancescalabilityandreducedependency
on triplet sampling. Triplet learning and its variants have shownstrongperformanceinapplicationssuchasCBIRand remote sensing, where capturing semantic similarity is crucial.However,severalchallengesremain,particularlyin multi-labellearning,scalability,andsemanticunderstanding. Addressing these challenges requires the development of moresophisticatedmodelsthatintegrateadaptivemargin strategies, semantic information, and scalable learning frameworks. Future research in this direction has the potential to significantly advance the field of deep metric learning.
[1]F.Schroffetal.,“FaceNet:AUnifiedEmbeddingfor Face Recognition,” CVPR, 2015. [2]R.Hadselletal.,“DimensionalityReductionbyLearning an Invariant Mapping,” CVPR, 2006.
[3] K. Sohn, “Improved Deep Metric Learning with Multiclass N-pair Loss,” NIPS, 2016.
[4]H.Songetal.,“DeepMetricLearningviaLiftedStructured Feature Embedding,” CVPR, 2016.
[5]Y.Movshovitz-Attiasetal.,“NoFussDistanceMetric Learning using Proxies,” ICCV, 2017. [6]J.Wangetal.,“DeepMetricLearningwithAngularLoss,” ICCV,2017.
[7] X. Wang et al., “Multi-Similarity Loss,” CVPR, 2019. [8]Y.Sunetal.,“CircleLoss:AUnifiedPerspectiveofPair SimilarityOptimization,”CVPR,2020.
[11] C. Wu et al., “Sampling Matters in Deep Embedding Learning,”ICCV,2017.
[13] M. L. Ha and V. Blanz, “Deep Ranking with Adaptive MarginTripletLoss,”2021.
[14]K.Nguyenetal.,“AdaTriplet:AdaptiveGradientTriplet Loss,”MICCAI,2022.
[15]M.Lietal.,“SymmetricMetricLearningwithAdaptive Margin,”AAAI,2020.
[16]M.Zhangetal.,“TripletNonlocalNeuralNetworkwith Dual-Anchor Triplet Loss,” IEEE JSTARS, 2021.
[17] W. Deng et al., “Rethinking Triplet Loss for Domain Adaptation,”IEEETCSVT,2021.
[18]Y.Bouallegetal.,“TLDCNN:TripletLow-Dimensional CNN for Remote Sensing Retrieval,” 2020.
[19]I.Hernandez-Sequeiraetal.,“Semi-andSelf-Supervised MetricLearning,”IEEEGRSL,2024.