
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
Amit Gupta1 , Mrs. Arifa Khan2
1Master of Technology, Computer Science and Engineering, Lucknow Institute of Technology, Lucknow, India
2Assistant Professor, Department of Computer Science and Engineering, Lucknow Institute of Technology, Lucknow, India
Abstract - Self-supervisedlearning(SSL)has emergedas a transformativeapproachindeeplearning,enablingmodelsto learnmeaningfulrepresentationsfromunlabeleddata.Among various SSL paradigms, encoder–decoder architectures with masked reconstruction have demonstrated significant potential in structured data representation learning, such as tabular, time-series, and graph-based datasets. Dynamic masked reconstruction, a recent advancement over fixed maskingstrategies,adaptivelyselectsportionsofinputdatato mask during training, improving the model’s ability to generalize and capture underlying data structures. This review paper systematically examines the development, methodologies, and applications of self-supervised encoder–decoder architectures with dynamic masked reconstruction, emphasizing their effectiveness in structured data representation. The literature survey covers traditional autoencoders, transformer-based models, masked autoencoders, and hybrid approaches, highlighting performance metrics, strengths, and limitations reported in recentstudies.Additionally,thereviewevaluatesPython-based implementations, frameworks, and tools commonly used to build and experiment with these models, providing practical insightsforresearchersandpractitioners.Challenges,suchas dataset complexity, computational costs, and reproducibility issues,arediscussed,alongsideemergingtrendsandpotential future directions, including hybrid SSL models, adaptive masking strategies, and standardized benchmarking for structured datasets. By synthesizing existing research, this paper aims to offer a comprehensive perspective on current methodologiesandguidefutureworkinefficientandscalable representation learning for structured data in Python. The review demonstrates that dynamic masked reconstruction, combined with encoder–decoder architectures, represents a promising avenue for advancing self-supervised learning in structured domains.
Key Words: Self-Supervised Learning, Encoder–Decoder Architecture, Dynamic Masked Reconstruction, Structured Data Representation, Deep Learning, Python Implementation
1.1.1
Representation learning is a critical aspect of modern machinelearning that focuses on automatically extracting meaningfulandcompactfeaturesfromrawdata.Traditional machine learning methods often rely on handcrafted features, which are time-consuming and domain-specific, limitingtheirgeneralizability(Bengio,Courville&Vincent, 2013). Deep learning approaches, particularly those leveragingneuralnetworks,haverevolutionizedthisdomain by learning hierarchical representations that capture complexpatternsandlatentstructuresinherentinthedata (LeCun, Bengio & Hinton, 2015). Efficient representation learning is essential for improving the performance of downstream tasks such as classification, regression, clustering,andanomalydetection.
1.1.2
Structured data, including tabular datasets, time-series records,andgraphs,constituteasignificantportionofrealworldinformationacrossvariousdomains,suchasfinance, healthcare,andnetworkanalytics(Guoetal.,2021).Unlike unstructureddata(e.g.,imagesortext),structureddatahas clearly defined attributes, often with semantic meaning, making its effective representation critical for decisionmaking. Learning robust representations from structured data helps in uncovering relationships between features, reducingdimensionality,andenhancingpredictiveaccuracy indownstreamapplications.
A persistent challenge in supervised learning is the dependencyonlargeamountsoflabeleddata,whichisoften expensive, time-consuming, or even infeasible to obtain (Goodfellow,Bengio&Courville,2016).Structureddatasets frequentlysufferfromlabelsparsity,missingvalues,ornoisy annotations, which can severely degrade model performance.Theselimitationshavemotivatedresearchinto self-supervised learning, where models leverage intrinsic
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
datapatternstolearnusefulrepresentationswithoutrelying onextensivelabeleddatasets(Jing&Tian,2020).
1.2.1
Self-supervisedlearning(SSL)isaparadigminwhichmodels generate supervisory signals from the input data itself, rather than requiring manual annotations. This approach allowsneuralnetworkstolearnmeaningfulrepresentations bysolvingpretexttasks,suchaspredictingmaskedfeatures, reconstructinginputs,orcontrastingdatapoints(Chenetal., 2020).SSLhasgainedsubstantialattentionduetoitsability toexploitvastamountsofunlabeleddataefficiently,bridging the gap between supervised and unsupervised learning paradigms.
1.2.2
While supervised learning relies on labeled datasets for predictive modeling and unsupervised learning seeks to uncoverhiddenstructureswithoutlabels,SSLoccupiesan intermediate space. It leverages self-generated labels derivedfromthedataitself,effectivelyreducingthereliance on manual annotation while still guiding the learning process (Goyal et al., 2021). This positioning makes SSL particularly suitable for structured data scenarios where obtaining high-quality labeled datasets is challenging, yet understandinginter-featurerelationshipsremainscritical.
1.3.1
Thisreviewaimstoprovideacomprehensivesynthesisof researchonself-supervisedencoder–decoderarchitectures with dynamic masked reconstruction for structured data. Thesurveyfocusesonidentifyingkeymethodologies,model architectures,maskingstrategies,performancemetrics,and Python-based implementations. It aims to summarize advancements, highlight state-of-the-art techniques, and provide practical insights for researchers intending to developorimplementthesemodels.
1.3.2
Whilethesurveyextensivelycoversencoder–decoder-based self-supervisedmethods,itdoesnotdelveintounrelatedSSL approachesforunstructureddata,suchasimageortext-only models.Furthermore,theemphasisisonmodelsapplicable tostructureddatarepresentationandtheirimplementation usingPythonframeworkssuchasPyTorchandTensorFlow, providingguidanceonboththeoreticalandpracticalaspects. The survey also identifies challenges, research gaps, and potential future directions within this specific domain, ensuring a focused and relevant contribution to the literature.
2.1
To ensure a comprehensive and high-quality review, the literaturesearchprimarilyutilizedseveralleadingacademic databases. IEEE Xplore was employed to access peerreviewedconferencepapersandjournalarticlesfocusedon engineeringandcomputing,particularlyintheareasofdeep learning and self-supervised methods. Scopus and Web of Science provided a broader range of interdisciplinary articles, enabling the inclusion of both theoretical and applied studies. Google Scholar was used to capture additional sources, including preprints and open-access works, which are especially relevant for emerging techniques such as dynamic masked reconstruction. The combinationofthesedatabasesensuresabalancebetween depth,recency,andrelevanceoftheselectedliterature(Jing &Tian,2020).
2.2
The literature search was guided by a set of targeted keywordstocapturestudiesdirectlyrelevanttotheresearch topic. Primary search queries included “self-supervised learning”combinedwith“encoderdecoder”toidentifywork onarchitecturescapableoflearninglatentrepresentations withoutlabeleddata.Tospecificallylocatestudiesinvolving reconstruction-basedapproaches,“maskedreconstruction” and“representationlearning”wereused.Finally,keywords suchas“self-supervised+structureddata”helpedfocusthe searchonapplicationsrelevanttotabular,time-series,and graph datasets. Boolean operators, phrase searches, and truncations were applied to refine results and avoid irrelevantliterature(Chenetal.,2020;Guoetal.,2021).
3.1 Encoder–Decoder Architectures
3.1.1
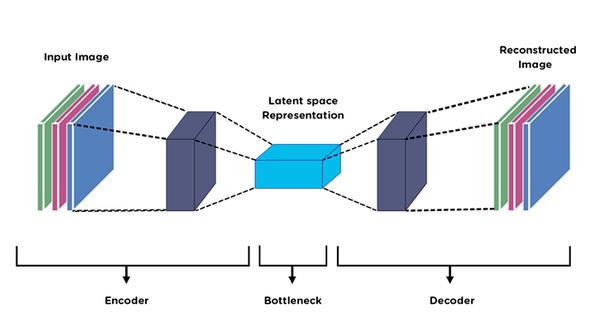
Encoder–decoderarchitecturesareaclassofneuralnetwork models designed to learn a mapping from input data to a latentrepresentationandthenreconstructtheoriginaldata orpredictatargetoutput.Theencodercompressestheinput into a compact latent space, capturing essential features, while the decoder reconstructs the input or produces desired outputs based on the latent representation (Goodfellow, Bengio & Courville, 2016). Training typically involves minimizing a reconstruction loss, such as mean squared error for continuous data, to ensure the latent representation retains critical information. Variants of encoder–decoder pipelines include simple autoencoders, denoising autoencoders, and variational autoencoders (VAEs), each with unique properties for handling noise, uncertainty, and latent space regularization (Kingma & Welling,2014).
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
Traditional encoder–decoder models relied on shallow architectureswithoneortwohiddenlayers,limitingtheir ability to capture complex nonlinear relationships in the data. In contrast, deep encoder–decoder models leverage multiplestackedlayers,oftenincorporatingconvolutionalor transformer-based modules, which enable hierarchical feature extraction and more expressive representations (LeCun,Bengio&Hinton,2015).Deepmodelsalsosupport advanced techniques like skip connections, attention mechanisms, and residual blocks, improving training stability and reconstruction fidelity. These deep architecturesare particularlyeffectiveforstructured data wherecapturinginter-featuredependenciesisessential.
3.2.1
Masked reconstruction emerged from natural language processing (NLP), most notably with the development of BERT (Bidirectional Encoder Representations from Transformers) and later Masked Autoencoders (MAE) for images(Devlinetal.,2019; He etal.,2022).Thecoreidea involvesmaskingaportionoftheinputdataandtrainingthe modeltopredictorreconstructthemaskedvaluesfromthe unmaskedcontext. This pretext task enables the model to learnmeaningfulfeaturerepresentationswithoutrequiring explicitlabels.
Masking serves multiple purposes in self-supervised learning. First, it forces the encoder–decoder model to captureglobalandlocaldependenciesinthedata,improving therobustnessofthelearnedembeddings.Second,dynamic maskingstrategies,whichadaptivelyselectfeaturestomask basedondatacharacteristics,canenhancegeneralizationby preventingoverfittingtospecificinputpatterns(Jing&Tian, 2020).Maskedreconstructionisparticularlyadvantageous forstructureddata,whererelationshipsamongfeaturesmay be sparse, irregular, or non-linear, and learning these dependenciesiscrucialfordownstreamtasks.
3.3.1
Structured data refers to information organized into predefinedschemasorformats,suchastables,spreadsheets, relational databases, time-series sequences, or graphstructured data (Guo et al., 2021). Each instance typically consistsofmultiplefeatures(columns)withconsistenttypes andrelationships.Structureddatadiffersfromunstructured data likeimagesortext,asitssemanticsareoften explicit anddirectlyinterpretable,butitpresentsuniquechallenges incapturinginter-featuredependenciesandpatterns.
The primary goal of structured data representation is to transformrawinputsintocompact,informativeembeddings that capture intrinsic patterns and relationships among features.Theserepresentationscanfacilitatedimensionality reduction, enabling efficient storage and computation, or feature embedding, where latent vectors encode essential information for downstream tasks such as classification, regression, clustering, or anomaly detection. Encoder–decoder architectures with masked reconstruction are particularlysuitableforachievingthesegoals,astheylearn bothfeature-leveldependenciesandglobalstructuresfrom unlabeleddata.
4.1.1
Autoencoders are one of the foundational self-supervised learning (SSL) models for representation learning. They consistofanencoderthatcompressestheinputdataintoa latentvectorandadecoderthatreconstructstheinputfrom thiscompressedrepresentation.Thetrainingobjectiveisto minimizethereconstructionerror,allowingthenetworkto capture the most informative features of the data (Goodfellow, Bengio & Courville, 2016). Autoencoders are widelyusedfordimensionalityreduction,featureextraction, andanomalydetectioninstructuredandunstructureddata.
4.1.2 Denoising
Denoisingautoencodersextendtraditionalautoencodersby introducing noise into the input data during training. The model learns to reconstruct the original, noise-free input, whichencouragestheencodertocapturemorerobustand generalizablefeatures(Vincentetal.,2010).Thisproperty makes denoising autoencoders particularly useful when handlingstructureddatasetswithmissingvalues,corrupted entries,orinherentvariability.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
Contrastive Predictive Coding (CPC) is a self-supervised method that learns representations by predicting future segmentsofasequenceorrelateddatapointsinlatentspace.
CPC leverages contrastive loss to distinguish between positive samples (related data) and negative samples (unrelated data), promoting embeddings that capture temporal or relational dependencies (Oord, Li & Vinyals, 2018).CPChasbeeneffectivelyappliedtostructureddata such as time-series and tabular sequences, improving downstreampredictiveperformance.
4.2
4.2.1
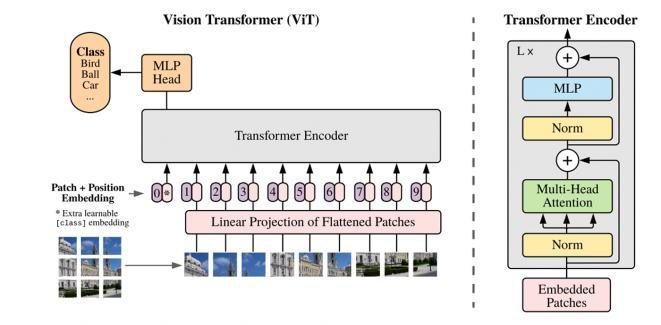
BERT (Bidirectional Encoder Representations from Transformers) introduced masked language modeling, where a subset of input tokens is masked and the model learnstopredictthemusingbidirectionalcontext(Devlinet al., 2019). This approach was later adapted to structured data, where masking features and reconstructing them enableslearninginter-featuredependencieswithoutlabeled data. BERT-style frameworks provide strong contextual embeddings, capturing relationships among all input featuressimultaneously.
4.2.2 Masked Auto encoders (MAE)
MaskedAutoencoders(MAE)extendthemaskingconceptto visual and tabular structured data, typically by randomly masking portions of the input and reconstructing them through encoder–decoder architecture (He et al., 2022). Unlike traditional auto encoders, MAEs focus on partial reconstruction, reducing computational overhead while forcingthemodeltoextractgloballycoherentfeaturesfrom theunmaskeddata.MAEshaveshownpromisingresultsin representation quality for downstream tasks while being computationallyefficient.
4.3.1 Concept of Dynamic Masking
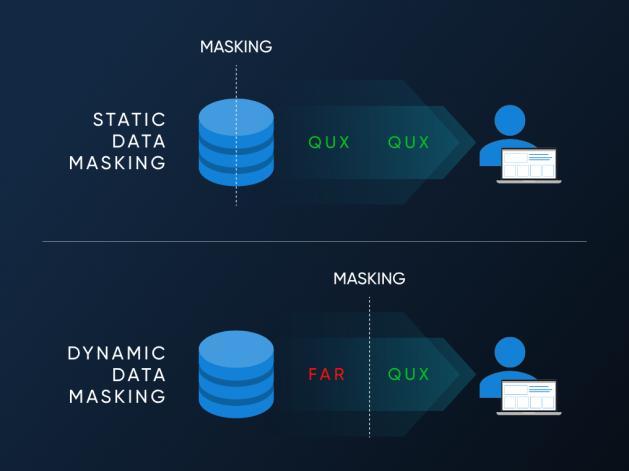
Dynamic masked reconstruction refers to an adaptive masking strategy where the subset of masked features or inputregionschangesacrosstrainingiterationsbasedonthe datacharacteristicsormodelfeedback.Thiscontrastswith fixed masking, where the same features or tokens are consistentlymaskedthroughouttraining.Dynamicmasking encourages the model to learn more comprehensive and robust representations, as it cannot overfit to a static maskingpattern(Xieetal.,2021).
4.3.2 Differences from Fixed or Random Masking
Whilefixedmaskingmayleadtooverfittingandinsufficient feature exploration, and random masking provides some variabilitybutignoresfeatureimportance,dynamicmasking isdesignedtoprioritizeinformativeorchallengingregions ineachbatch.Thisapproachenhancesgeneralization,allows betterutilizationoftheencoder–decoder’scapacity,andis especiallybeneficialforstructureddatawithheterogeneous feature importance (Jing & Tian, 2020). Dynamic masking hasthusbecomeakeymechanisminrecentSSLmodelsfor structuredrepresentationlearning.
5. LITERATURE REVIEW: DEEP ENCODER–DECODER MODELS WITH DYNAMIC MASKED RECONSTRUCTION
5.1.1 Model Type
Researchonself-supervisedencoder–decodermodelswith maskedreconstructioncanbebroadlycategorizedintothree types:traditionalautoencoders,transformer-basedmodels, andhybridarchitectures.Traditionalautoencodersandtheir variants,suchasdenoisingautoencoders,primarilyrelyon fully connected networks to reconstruct masked input featuresandaremostcommonlyappliedtotabulardatasets (Vincentetal.,2010).Transformer-basedmodels,inspired by BERT, leverage attention mechanisms to capture longrangedependencies,makingthemparticularlysuitablefor sequences,graphs,andotherstructureddatawithcomplex
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
inter-feature relationships (Devlin et al., 2019; He et al., 2022).Hybridmodelscombineautoencoderbackboneswith transformer encoders or attention modules, offering the benefitsofbotharchitectures:efficientreconstructionand contextual awareness. These categorizations help researchersselectarchitecturesaccordingtothenatureof thestructureddataandcomputationalresources.
Encoder–decodermodelswithmaskedreconstructionhave beenappliedacrossdiversestructureddatatypes.Tabular datasetsarewidelyusedforbenchmarkstudies,suchasUCI repository datasets, where reconstruction quality and downstreampredictiveaccuracyarekeyevaluationmetrics. Time-series datasets benefit from transformer-based masked reconstruction models that can capture temporal dependencies and irregular sampling (Oord, Li & Vinyals, 2018). Graph-structured data leverages masked node or edgereconstructiontolearnembeddingssuitablefornode classification,linkprediction,andclusteringtasks(Guoetal., 2021).Thechoiceofmodeltypeandmaskingstrategyoften dependsonthespecificapplicationdomainandtheinherent relationshipsinthedata.
Analysis of these studies reveals several key insights. Traditional autoencoders are computationally lightweight butoftenfailtocapturecomplexdependenciesinstructured data. Transformer-based masked reconstruction models provide superior context-aware embeddings but incur highercomputationalcostandmemoryusage(Devlinetal., 2019). Dynamic masked reconstruction improves performance by preventing overfitting to fixed masking patterns,enablingmoregeneralizedrepresentationsacross multiple structured datasets (Xie et al., 2021). Evaluation metricscommonlyincludereconstructionerror(MSE,MAE), downstream task performance (accuracy, F1-score), and embedding quality (clustering metrics). Availability of Python implementations varies: MAE and BERT-style frameworks are widely supported, while some dynamic masking approaches require custom coding for reproducibility.
Comparingthesemodelshighlightsthetrade-offsbetween representation quality, computational efficiency, and adaptabilitytodifferentstructureddatatypes.Autoencoders excelintabulardatawithmoderatefeaturecomplexitybut underperformforgraphsorlongsequences.Transformerbased models achieve higher representation fidelity, particularlyfortime-seriesandgraph-structureddata,due totheirabilitytocapturelong-rangedependencies.Dynamic masked reconstruction consistently outperforms fixed or randommaskingbyadaptivelyselectingimportantfeatures during training, improving generalization. Across studies,
dynamicmaskingprovidesthemostrobustperformanceon heterogeneous structured datasets, enabling a balance between reconstruction quality and computational efficiency.Thissynthesisindicatesthatfutureworkshould integrate hybrid architectures with adaptive masking strategiesandstandardizedbenchmarksforstructureddata tomaximizegeneralizationandreproducibility.
PyTorch has emerged as one of the most widely adopted deeplearningframeworksforimplementingself-supervised encoder–decoder models. Its dynamic computation graph allowsflexiblemodeldesign,makingitparticularlysuitable forexperimentationwithmaskedreconstructionstrategies (Paszke et al., 2019). PyTorch supports GPU acceleration, automatic differentiation, and modular network design, which enables researchers to efficiently implement autoencoders, BERT-style frameworks, and Masked Autoencoders (MAE). Its large community and extensive documentation also facilitate rapid prototyping of new architectures.
TensorFlow,alongwithitshigh-levelAPIKeras,providesa robust ecosystem for building deep learning models with production-ready deployment capabilities (Abadi et al., 2016). TensorFlow’s graph-based computation allows optimized performance for large datasets, and Keras simplifiesmodelconstruction,training,andevaluation.Both frameworkssupportencoder–decoderarchitecturesandcan incorporatemaskedreconstructionthroughcustomlayers or prebuilt modules. Additionally, TensorFlow offers TensorBoard for visualization, aiding in monitoring reconstructionlossandembeddingquality.
While PyTorch and TensorFlow handle deep learning operations, Scikit-learn remains critical for preprocessing structureddata,includingnormalization,featureselection, imputation,anddimensionalityreduction(Pedregosaetal., 2011).IntegratingScikit-learnwithPyTorchorTensorFlow pipelinesensuresthatstructureddatasetsaretransformed appropriately before being fed into encoder–decoder networks, which improves model stability and representationquality.
6.2.1
Maskedreconstructionreliesonlibrariessuchastorch.nn for defining neural network layers and
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
torchvision.transforms for input transformations, particularly when dealing with image-based structured representations or tabular-to-tensor conversions. Custom masking utilities are often implemented to dynamically selectfeaturesortokensforreconstructiontasks,enabling experimentation with different masking strategies and improvinggeneralization.
6.2.2
SeveralPythonframeworksprovidehigher-levelsupportfor masked reconstruction and self-supervised learning. HuggingFace’s Transformers library facilitates implementation of BERT-style models and MAE architectures with pretrained weights, allowing rapid adaptation to structured datasets. PyTorch Lightning abstracts training loops and checkpointing, simplifying reproducibilityanddistributedtraining,whichisespecially valuable for models with dynamic masked reconstruction (Heetal.,2022).
6.3.1 Coding
Maintaining clear and modular code is essential for implementingcomplexencoder–decodermodels.Standard practices include using separate modules for data preprocessing, model definition, training, and evaluation. Documenting functions, using type hints, and writing unit tests enhance readability and reproducibility, which are criticalinself-supervisedlearningresearch.
6.3.2 Open Source Repositories
Availability of open-source code repositories accelerates reproducibilityandfacilitatesbenchmarking.Manystudies provide PyTorch or TensorFlow implementations of MAE, BERT-style SSL, and dynamic masked reconstruction, allowing researchers to validate findings on custom structureddatasetsandextendmodelstonewdomains(Xie etal.,2021).
6.3.3 Performance Profiling (CPU vs GPU)
Encoder–decoder models with masked reconstruction are computationallyintensive,particularlytransformer-basedor dynamically masked architectures. Profiling code for CPU and GPU performance is essential to optimize batch sizes, memory usage, and training speed. GPU acceleration significantlyreducestrainingtime,whileCPUprofilinghelps identifybottlenecksinpreprocessingandmaskingroutines, ensuring efficient end-to-end workflows (Paszke et al., 2019).
Reconstruction error is the most fundamental metric for evaluating encoder–decoder models with masked reconstruction. It measures how accurately the decoder reconstructs the masked or original input from the latent representation. Common metrics include Mean Squared Error(MSE)andMeanAbsoluteError(MAE).MSEpenalizes larger deviations more heavily, making it suitable for datasets where large errors are particularly detrimental, whileMAEprovidesamoreinterpretablelinearmeasureof reconstruction accuracy (Goodfellow, Bengio & Courville, 2016).Instructureddata applications,lowreconstruction errorindicatesthatthelatentembeddingspreserveessential feature information, which is critical for downstream predictivetasks.
Beyond reconstruction, the quality of the learned latent embeddings is crucial. Clustering-based metrics, such as Silhouette Score, Davies-Bouldin Index, and CalinskiHarabaszIndex,arecommonlyusedtoevaluatehowwellthe embeddingsseparatedistinctclassesorpatternsinthedata (Guoetal.,2021).High-qualityembeddingstypicallyresult in well-separated clusters, indicating that the encoder captures meaningful feature representations even in unlabeleddatasets.Thesemetricsareparticularlyusefulin self-supervisedlearning,wheredownstreamlabelsmaybe limitedorunavailable.
7.1.3
Ultimately, the practical utility of self-supervised representations is measured through performance on downstream tasks. For structured data, these tasks often include classification (categorical output) or regression (continuous output). Metrics such as accuracy, F1-score, precision,recall,androotmeansquarederror(RMSE)are widelyused.Effectiverepresentationslearnedviamasked reconstruction often improve these metrics compared to baseline models without pretraining, demonstrating the transferabilityoftheembeddings(Heetal.,2022;Xieetal., 2021).
7.2.1 Performance Differences Across Models and Datasets
Comparativeanalysisacrossstudiesshowscleardifferences in performance based on model architecture, masking strategy, and dataset characteristics. Traditional
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
autoencodersgenerallyachievesatisfactoryreconstruction on tabular datasets but produce embeddings with lower clustering quality and downstream task performance (Vincentetal.,2010).Transformer-basedmodelsandMAEs consistently outperform in embedding quality and classification accuracy due to their ability to model longrangedependenciesandcontextualrelationships(Devlinet al.,2019;Heetal.,2022).Dynamicmaskedreconstruction furtherimproves generalizationacross diverse structured datatypesbyadaptivelyselectinginformativefeaturesfor reconstruction, resulting in lower MSE/MAE and higher clustering scores (Xie et al., 2021). Differences are also observed across dataset types: time-series data benefits more from transformers due to sequential dependencies, whereas tabular datasets can often be handled effectively with autoencoder-based architectures with dynamic masking.
When comparing results across studies, it is important to account for experimental variations, including dataset preprocessing, batch sizes, masking ratios, and training duration.Consistentbenchmarkingusingstandarddatasets (e.g.,UCItabulardatasets,PhysioNettime-series,orgraph benchmarks) provides meaningful comparisons of reconstructionerror,embeddingquality,anddownstream task performance. Python-based implementations in PyTorchorTensorFlowallowreproducibilityandefficient profiling across hardware (CPU vs GPU), ensuring that reportedperformancemetricsarereliableandcomparable.
Self-supervised learning (SSL) with encoder–decoder architectures has emerged as a powerful approach for structured data representation, addressing challenges associated with limited labeled data. This review has comprehensively analyzed traditional autoencoders, denoising autoencoders, contrastive predictive coding, transformer-based models, and hybrid frameworks, highlighting their architectures, masking strategies, and applicationsacrosstabular,time-series,andgraphdatasets. Masked reconstruction, inspired by frameworks such as BERTandMaskedAutoencoders(MAE),hasprovenhighly effective in enabling models to learn meaningful feature representations from unlabeled data. Dynamic masked reconstruction, which adaptively selects features to mask during training, further enhances generalization and robustness by encouraging the model to capture complex inter-feature dependencies without overfitting to static patterns.
Python-basedimplementations,particularlyinPyTorchand TensorFlow, facilitate reproducibility and practical experimentation, while evaluation metrics such as reconstruction error, clustering-based embedding quality, and downstream task performance provide standardized
benchmarksforcomparingmodels.Acrossstudies,dynamic masked reconstruction consistently improves representation quality and predictive performance, particularlyforheterogeneousstructureddatasets.Overall, this review demonstrates that SSL with encoder–decoder architectures,combinedwithadaptivemaskingstrategies, representsapromisingandscalableavenueforefficientand robust structured data representation. These findings providevaluableinsightsforresearchersandpractitioners seeking to implement or extend SSL models in Python for diversestructureddataapplications.
Despite its comprehensive scope, this review has several limitations.First,thefocusisrestrictedtoencoder–decoderbased SSL models with masked reconstruction, excluding other SSL paradigms, such as contrastive learning approaches for unstructured data, which may also offer insightsforstructureddata.Second,theemphasisonPython implementationslimitsthecoverageofmodelsdevelopedin other frameworks or languages. Third, due to the heterogeneity of datasets, evaluation metrics, and experimental setups across studies, direct quantitative comparisons may be affected by inconsistencies in preprocessing,maskingratios,andmodelhyperparameters. Finally, emerging trends and recent preprints may not be fully represented, as the literature search primarily prioritized peer-reviewed journal and top conference publicationswithinthelast5–10years.
1. Abadi,M.,Barham,P.,Chen,J.,Chen,Z.,Davis,A.,Dean, J.,Devin,M.,Ghemawat,S.,Irving,G.,Isard,M.&Kudlur, M.,2016.TensorFlow:Asystemforlarge-scalemachine learning.OSDI,16,pp.265–283.
2. Bengio, Y., Courville, A. & Vincent, P., 2013. Representation learning: A review and new perspectives. IEEE Transactions on Pattern Analysis andMachineIntelligence,35(8),pp.1798–1828.
3. Chen,T.,Kornblith,S.,Norouzi,M.&Hinton,G.,2020.A simple framework for contrastive learning of visual representations.InternationalConferenceonMachine Learning,pp.1597–1607.
4. Devlin,J.,Chang,M.-W.,Lee,K.&Toutanova,K.,2019. BERT:Pre-trainingofdeepbidirectionaltransformers for language understanding. NAACL-HLT, pp.4171–4186.
5. Goodfellow, I., Bengio, Y. & Courville, A., 2016. Deep Learning.MITPress.
6. Guo, C., Li, Y., Li, Y., He, H. & Chen, T., 2021. Representationlearningforstructureddata:Asurvey. InformationFusion,68,pp.136–150.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 02 | Feb 2026 www.irjet.net p-ISSN: 2395-0072
7. He, K., Chen, X., Xie, S., Li, Y., Dollár, P. & Girshick, R., 2022. Masked autoencoders are scalable vision learners.CVPR,pp.16000–16009.
8. Jing,L.&Tian,Y.,2020.Self-supervisedvisualfeature learning with deep neural networks: A survey. IEEE Transactions on Pattern Analysis and Machine Intelligence,43(11),pp.4037–4058.
9. Kingma, D.P. & Welling, M., 2014. Auto-encoding variationalBayes.InternationalConferenceonLearning Representations(ICLR).
10. LeCun,Y.,Bengio,Y.&Hinton,G.,2015.Deeplearning. Nature,521(7553),pp.436–444.
11. Oord,A.v.d.,Li,Y.&Vinyals,O.,2018.Representation learning with contrastive predictive coding. arXiv preprintarXiv:1807.03748.
12. Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan,G.,Killeen,T.,Lin,Z.,Gimelshein,N.,Antiga,L.& Desmaison, A., 2019. PyTorch: An imperative style, high-performance deep learning library. Advances in NeuralInformationProcessingSystems,32,pp.8024–8035.
13. Pedregosa, F., Varoquaux, G., Gramfort, A., Michel, V., Thirion, B., Grisel, O., Blondel, M., Prettenhofer, P., Weiss, R., Dubourg, V. & Vanderplas, J., 2011. Scikitlearn:MachinelearninginPython.JournalofMachine LearningResearch,12,pp.2825–2830.
14. Vincent, P., Larochelle, H., Lajoie, I., Bengio, Y. & Manzagol,P.-A.,2010.Stackeddenoisingautoencoders: Learningusefulrepresentationsinadeepnetworkwith alocaldenoisingcriterion.JournalofMachineLearning Research,11,pp.3371–3408.
15. Xie, J., Lu, Y., Zhang, T. & Zhang, C., 2021. Adaptive masked reconstruction for self-supervised representationlearning.NeuralNetworks,140,pp.50–62.
16. Li, H., Wang, X., Zhang, Z., Wu, Z., Xiao, L. & Zhu, W., 2025.Self supervisedMaskedGraphAutoencodervia Structure awareCurriculum.Proceedingsofthe42nd InternationalConferenceonMachineLearning,PMLR 267,pp.36215–36235.
17. Shi, Y., Dong, Y., Tan, Q., Jundong, L., & Liu, N., 2023. GiGaMAE: Generalizable Graph Masked Autoencoder via Collaborative Latent Space Reconstruction. arXiv preprint.
18. Sun, C., 2023. HAT GAE: Self Supervised Graph Auto encoderswithHierarchicalAdaptiveMaskingand TrainableCorruption.arXivpreprint.
19. Hou,Z.,He,Y.,Cen,Y.,Liu,X.,Dong,Y.,Kharlamov,E.& Tang, J., 2023. GraphMAE2: A Decoding Enhanced MaskedSelf SupervisedGraphLearner.arXivpreprint.
20. Tu,W.,Liao,Q.,Zhou,S.,Peng,X.,Ma,C.,Liu,Z.,&Cai,Z., 2023.RARE:RobustMaskedGraphAutoencoder.arXiv preprint.
21. Foumani,N.M.etal.,2024.Series2Vec:similarity based self supervisedrepresentationlearningfortimeseries classification.DataMiningandKnowledgeDiscovery, 38,pp.2520–2544.
22. Chen, X. et al., 2023. Context Autoencoder for Self Supervised Representation Learning. arXiv preprint.
23. Cheng,M.,Liu,Q.,Liu,Z.,Zhang,H.,Zhang,R.&Chen,E., 2023. TimeMAE: Self Supervised Representations of Time Series with Decoupled Masked Autoencoders. arXivpreprint.
24. Zhang, C., Zhang, C., Song, J., Yi, J.S.K. & Kweon, I.S., 2023. A Survey on Masked Autoencoder for Visual Self Supervised Learning. IJCAI International Joint ConferenceonArtificialIntelligence.
25. EmergentMind(2026).MaskedAutoencoder:Scalable Self Supervision. EmergentMind online article (overviewofMAEprinciples).
26. EmergentMind (2025). Self Supervised Masked Autoencoding Overview. EmergentMind online resource(principlesofmaskedreconstruction).
27. Uelwer,T.,Robine,J.,Wagner,S.S.etal.,2025.Asurvey onself supervisedmethodsforvisualrepresentation learning.MachineLearning,114,article111.
28. ScienceDirect(2025).EfficientTableEmbeddingsvia Self Supervised Structural Semantic Graph Autoencoder.InformationProcessing&Management.
29. ScienceDirect(2024).TS MAE:Amaskedautoencoder for time series representation learning. Information Sciences.
30. ScienceDirect (2024). A self supervised learning frameworkbasedonmaskedautoencoderforcomplex wafer bin map classification. Expert Systems with Applications.